AI Fundamentals
A Beginner's Guide to Neural Networks, Algorithms, and Real-World Applications
You want to understand AI, but the technical jargon and complex mathematics make it feel impossible to break through.
67 pages3 chaptersAug 27, 2026Artificial IntelligenceCreated by Liz
About this book
This book strips away the intimidation and builds your knowledge from the ground up. You'll discover how neural networks actually learn, master the essential terminology that appears everywhere in AI discussions, and explore real-world applications that are reshaping industries today. From computer vision systems that recognize faces to natural language processing that powers chatbots, you'll see how these technologies work in practice. You'll also learn the foundational mathematics that drives AI algorithms and, critically, understand where AI falls short—its limitations, risks, and the ethical considerations that matter. Whether you're curious about the technology shaping our future or preparing for a career in tech, this guide provides the clarity and practical knowledge you need to think confidently about artificial intelligence.
Table of contents
- Chapter 1: Core AI Concepts and TerminologyWhat Is Artificial Intelligence?, Essential AI Terminology You Need to KnowRead below
- Chapter 2: Neural Networks and AI AlgorithmsHow Neural Networks Learn and Adapt, Understanding AI Algorithm Fundamentals, The Mathematics Behind AI
- Chapter 3: AI in Action: Vision, Language, and BeyondComputer Vision: Teaching Machines to See, Natural Language Processing: Understanding Human Language
- Conclusion
Chapter 1: Core AI Concepts and Terminology
Imagine asking a friend to sort your email, translate a menu, and beat you at chess, three tasks that once required three entirely different human experts, now handled by variations of the same underlying idea: artificial intelligence. That single idea covers an enormous range of systems, from the spell checker in a phone to the software that guides a self-driving car. The word gets used so loosely in headlines and advertisements that it can start to feel meaningless, applied to everything from a smart thermostat to a chatbot that writes poetry. Before going further into how these systems work, it helps to slow down and build a shared vocabulary.
This matters because every later idea in this book rests on a small set of terms that get reused constantly. Words like Model, Training Data, and Inference will appear again and again once the discussion turns to neural networks, computer vision, and language processing. Getting comfortable with these words now means the later chapters will read as extensions of familiar ideas rather than a wall of new jargon. Think of this chapter as learning the names of the tools in a workshop before watching someone build furniture with them.
The goal here is not to memorize definitions for their own sake, but to build a working mental model. Once you understand what makes a system count as artificial intelligence, and how learning types like Supervised Learning and Unsupervised Learning differ, you gain the ability to evaluate claims you hear elsewhere. A news story claiming an AI "diagnosed cancer" or "wrote a novel" becomes something you can question intelligently, rather than accept or dismiss on faith.
Two sections make up this foundation. The first tackles the definition of artificial intelligence itself, including the important distinction between Narrow AI and General AI. The second builds out the vocabulary list, covering machine learning, deep learning, and the different flavors of training a machine can undergo. By the end, terms that once sounded like buzzwords will function as precise, usable concepts.
What Is Artificial Intelligence?
Artificial Intelligence refers to the branch of computer science focused on building systems that perform tasks normally associated with human thinking. This includes recognizing speech, identifying objects in images, making decisions from incomplete information, and generating language. The field traces back to a foundational workshop at Dartmouth College, where researchers including John McCarthy coined the term itself and proposed that every aspect of learning could in principle be simulated by a machine[1]. That founding ambition, building a machine that reasons the way a person does, still shapes how the public imagines AI today, even though most real systems fall far short of it.
A useful way to separate the hype from the reality is to distinguish between two categories: Narrow AI and General AI. Narrow AI describes any system built to do one job, and only that job, extremely well. A chess engine that can defeat any human grandmaster cannot fold laundry or hold a conversation, because it was never built to do those things. Virtually every AI system in commercial use today, from spam filters to recommendation engines, falls into this narrow category.
General AI, sometimes called artificial general intelligence, describes a hypothetical system capable of understanding and learning any intellectual task a human can, transferring knowledge fluidly between domains. No such system exists yet, despite frequent claims in popular media. Keeping this distinction clear prevents a common confusion: a chatbot that writes convincing sentences is still narrow, tuned for language generation, not a general reasoning mind that understands the world the way a person does.
The callout below captures this distinction in a form you can return to whenever a news headline overstates what an AI system can do.
Key takeaway: Narrow AI vs. General AI
Narrow AI: built for one specific task (image recognition, translation, game-playing).
General AI: a hypothetical system that could learn any task a human can.
Every AI product available today is Narrow AI.
Consider three familiar examples to see the narrow category in action. A voice assistant that sets a timer and answers trivia questions seems flexible, but each of its skills was individually built and trained by engineers, then stitched together behind one interface. A fraud-detection system at a bank flags suspicious transactions by finding patterns in past data, but it has no concept of money, trust, or crime beyond the numbers it was shown. A photo app that automatically tags faces recognizes patterns of pixels associated with a name, without any understanding of who that person actually is. Each system looks intelligent within its lane, and useless outside it.
This narrow-but-effective quality explains why AI has spread so quickly through industries in the last decade. Companies do not need a machine that understands everything, they need a machine that reliably automates one costly, repetitive task. A narrow system trained to read chest X-rays for signs of pneumonia can process thousands of images a day, catching patterns a tired radiologist might miss late in a shift. That narrowness is a feature, not a limitation, when the goal is efficiency rather than philosophical achievement.
It also explains why so many AI failures happen at the edges of a system's training. A self-driving car trained mostly on sunny California roads can struggle badly with snow it has rarely seen, because its skill was built from specific examples rather than general understanding. This fragility connects directly to Bias in AI, a concept explored further in the vocabulary section, where the data a system learns from directly shapes and limits what it can do well.
A second useful lens for understanding artificial intelligence is to ask what problem a given system is solving, rather than how "smart" it sounds. Some systems classify things into categories, such as sorting an email as spam or not spam. Others predict a number, such as estimating a house price from its size and location. Still others generate new content, such as producing an image or a paragraph of text, a category known as Generative AI that later chapters explore through language and vision applications. Naming the task type quickly cuts through marketing language.
The distinction between artificial intelligence as a broad field and Machine Learning as a specific approach within that field trips up many newcomers. Early AI research in the 1950s and 1960s often relied on hand-written logical rules, where programmers explicitly coded "if this, then that" instructions for every scenario. Machine learning, developed and popularized through work by early researchers and expanded dramatically since, took a different route, letting systems find their own patterns from examples rather than following rules a human wrote out in advance[2]. Nearly all AI systems built today use this learning-based approach rather than the older rule-based style.
Understanding artificial intelligence as a field, then, means holding two ideas at once. First, AI is the overall ambition of building machines that perform intelligent tasks, an ambition that stretches back nearly seventy years and is still far from its most ambitious form. Second, almost everything called AI in practice today is a narrow, task-specific system trained through machine learning on examples rather than programmed with explicit rules. Keeping both ideas in view prevents the two most common mistakes: dismissing AI as "just math" with nothing impressive about it, and overestimating a chatbot or image generator as something approaching human understanding.
Essential AI Terminology You Need to Know
Machine Learning is the technique that makes most modern AI possible, and it deserves a precise definition before anything else. It is a method of building systems that improve their performance on a task by being exposed to examples, rather than by following instructions written line by line. A spam filter built with machine learning does not contain a rule that says "block emails with the word free in all caps." Instead, it has seen thousands of labeled emails and learned, on its own, which patterns of words and formatting tend to appear in spam versus legitimate mail.
That example points directly to the next essential term: Training Data. This is the collection of examples a machine learning system studies in order to learn its task, and its quality shapes everything the system can later do. If a spam filter's training data only ever included English-language emails, it would likely perform poorly on spam written in French or Japanese, because it never saw examples in those languages. This dependency on training data is not a minor footnote, it is arguably the single most important limiting factor in how well any AI system performs in the real world.
Once a machine learning system has been trained, the result is called a Model. A model is the trained artifact itself, a set of learned patterns stored in a form the computer can use to make decisions on new data it has never seen before. Think of a model as a recipe distilled from thousands of cooking attempts. It is not the ingredients (the training data) and it is not the act of cooking (the training process), it is the finished, reusable set of instructions that resulted from that process.
Using a trained model to make a decision on new data is called Inference. If training is the process of a student studying for years, inference is the moment that student sits down and answers an actual exam question. When a photo app instantly recognizes a face in a picture just taken, that instant recognition is inference, the model applying what it learned during training to something brand new. Training typically happens once, often taking hours, days, or even weeks on powerful hardware, while inference happens repeatedly and quickly, often in a fraction of a second, every time the system is used.
Machine learning itself splits into three major learning styles, and distinguishing them clearly resolves a huge amount of confusion found in casual AI discussions. The table below lays out how each style differs in terms of what data it needs and what kind of problem it solves.
| Learning Type | Data Required | Typical Use Case |
|---|---|---|
| Supervised Learning | Labeled examples (input plus correct answer) | Spam detection, price prediction |
| Unsupervised Learning | Unlabeled examples (no correct answer given) | Customer segmentation, anomaly detection |
| Reinforcement Learning | No fixed dataset, feedback from actions taken | Game-playing agents, robotics control |
Supervised Learning is the most common style in commercial use, and it works by showing a model pairs of inputs and correct outputs until it can predict the output for a new input on its own. A supervised system for predicting house prices is trained on past sales, each one paired with its actual sale price, so the model learns the relationship between features like square footage and the final number. Nearly every classification and prediction task discussed later in this book, including much of computer vision and sentiment analysis, is built using supervised learning at its foundation.
Unsupervised Learning takes the opposite approach, working with data that has no correct answer attached at all. Instead of predicting a known label, an unsupervised system looks for hidden structure or grouping within the data itself. A retailer might feed years of purchase history into an unsupervised system to discover that customers naturally cluster into groups, such as bulk buyers versus occasional browsers, without ever telling the system in advance what those groups should be. This makes unsupervised learning especially useful for exploration, when the goal is to discover unknown patterns rather than confirm a known outcome.
Reinforcement Learning works differently still, training a system through trial and error using rewards and penalties rather than a fixed set of labeled examples. An agent takes an action, observes the result, and receives a signal indicating whether that action was good or bad, gradually learning a strategy that maximizes reward over time. This approach became famous through DeepMind's AlphaGo system, which learned to play the board game Go at a superhuman level partly through reinforcement learning against itself, defeating a world champion player[3]. Reinforcement learning suits problems involving sequences of decisions, such as robotics or game-playing, where the "right answer" only becomes clear after a series of actions plays out.
Deep Learning is a specific and highly influential subset of machine learning, built around structures called neural networks that stack many processing layers on top of each other. The word "deep" refers to that stacking, dozens or even hundreds of layers, each one transforming the data a little further before passing it to the next. This layered structure is what allows deep learning systems to handle messy, high-dimensional data like images, audio, and raw text far more effectively than older machine learning techniques could. The internal mechanics of how these layers actually function, including concepts like weights and activation functions, belong to the discussion of neural networks and algorithms in a later chapter.
It is worth pausing on why deep learning became so dominant only in the last fifteen years or so, despite the underlying mathematical ideas dating back decades earlier. Two ingredients had to arrive together: enormous amounts of digital training data, generated by the internet and smartphones, and enormous amounts of cheap computing power, largely enabled by graphics processing hardware originally built for video games. Without both pieces in place at once, even a brilliant algorithm cannot perform well, which is why many older AI ideas remained theoretical curiosities until relatively recently.
Bias in AI describes a systematic and often unintended skew in a model's behavior, usually traced back to patterns or gaps in its training data. If a hiring model is trained mostly on résumés from past successful employees at a company with a historically homogeneous workforce, it can end up favoring candidates who resemble that existing group, regardless of actual qualifications. This is not a matter of a computer holding conscious prejudice, it is a mathematical reflection of imbalances baked into the examples it was shown. Recognizing bias early requires actively auditing training data and model outputs, rather than assuming a system is neutral simply because it is built from numbers rather than opinions.
A well-known real-world instance of this problem occurred when a facial analysis system was found to perform significantly worse at identifying darker-skinned faces compared to lighter-skinned ones, a gap traced to training datasets that overwhelmingly featured lighter-skinned individuals[4]. This example illustrates why training data quality is not a side issue but a central ethical and technical concern running through every application discussed later in this book. A model can only reflect the world it was shown, and if that world was incomplete or skewed, the model's decisions will carry that same skew forward into every prediction it makes.
Bringing these terms together with a concrete scenario helps cement them. Picture a company building a system to recognize handwritten digits on mailed checks. It gathers thousands of scanned digit images, each labeled with the correct number, that collection is the training data. It chooses supervised learning, since each example comes with a known correct answer attached. It builds a deep learning system, layering multiple processing stages to handle the visual complexity of handwriting. After training finishes, the resulting model is deployed at a bank, where it performs inference on every new check that arrives, reading digits in a fraction of a second. If the training images mostly came from one style of handwriting, bias could creep in, causing the model to misread checks written in an unfamiliar style.
The checklist below offers a quick way to test your grasp of these nine core terms before moving into how the underlying neural networks that power deep learning actually function.
Core Vocabulary Self-Check
- Can you explain the difference between a Model and Training Data in your own words?
- Can you name one real-world example each of Supervised Learning and Unsupervised Learning?
- Can you explain why Reinforcement Learning suits game-playing better than a fixed dataset would?
- Can you describe how Bias in AI can enter a system without anyone intending it to?
- Can you distinguish Training from Inference using a non-technical analogy?
These nine terms, artificial intelligence, machine learning, deep learning, training data, model, inference, supervised learning, unsupervised learning, and reinforcement learning, along with narrow AI, general AI, and bias in AI, form a vocabulary set that will resurface constantly. When the next chapter opens up the internal mechanics of neural networks, layers, weights, and the mathematics of learning, these words will already feel familiar rather than foreign. That familiarity is the entire purpose of building this foundation first, so the more technical material ahead has something solid to stand on.
Notes
Chapter 1: Core AI Concepts and Terminology
- 1. John McCarthy and others, A Proposal for the Dartmouth Summer Research Project on Artificial Intelligence, 1955
- 2. Arthur Samuel, "Some Studies in Machine Learning Using the Game of Checkers," IBM Journal of Research and Development, 1959
- 3. David Silver and others, "Mastering the Game of Go with Deep Neural Networks and Tree Search," Nature, 2016
- 4. Joy Buolamwini and Timnit Gebru, "Gender Shades," Proceedings of Machine Learning Research, 2018
This is the end of the free sample. The full book has 3 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Artificial Intelligence knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Artificial Intelligence book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Artificial Intelligence book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
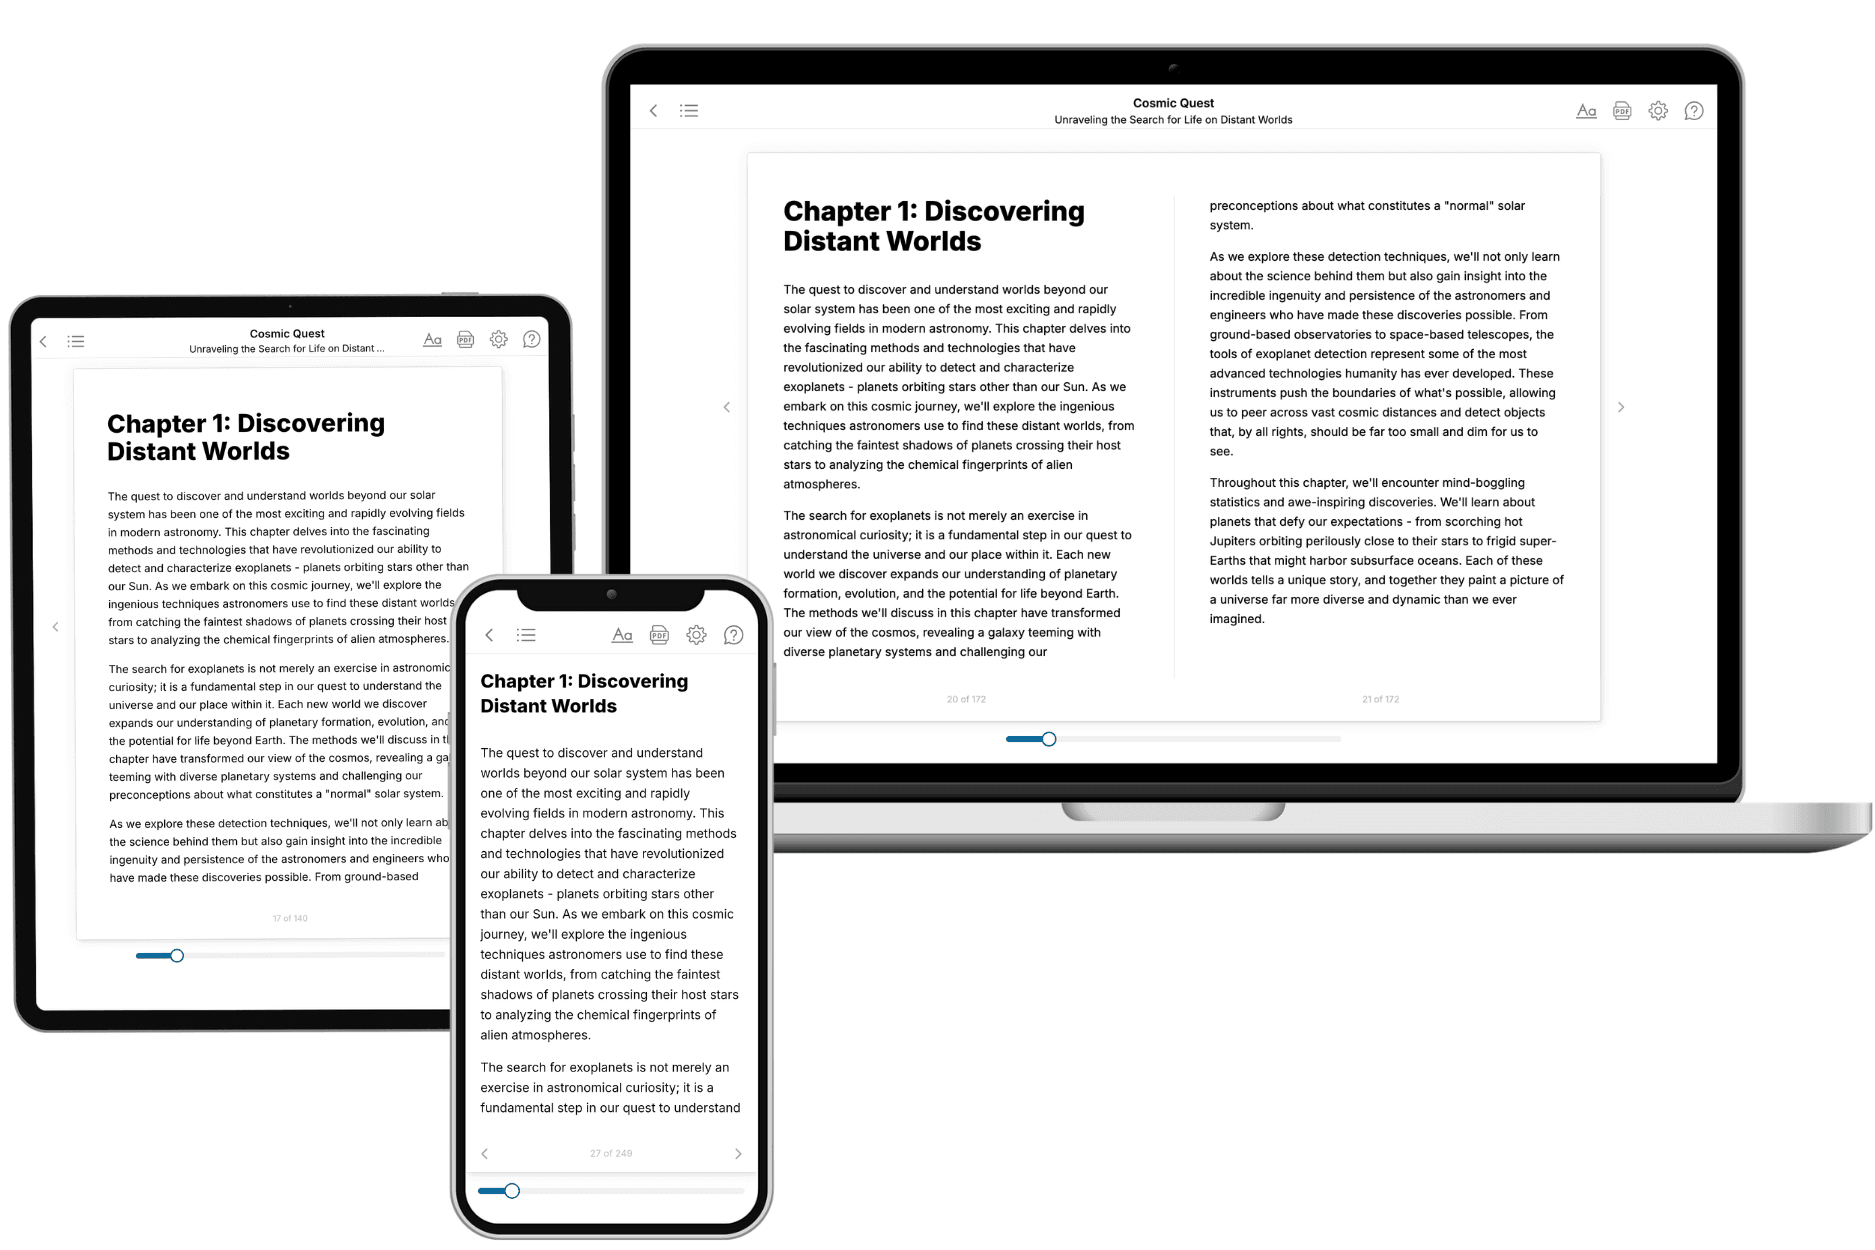
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.