Computational Density Functional Theory
Algorithms, Implementation, and Numerical Methods for Electronic Structure Calculations
Many believe that Density Functional Theory is purely a theoretical framework best left to quantum chemists and physicists.
284 pages14 chaptersSep 15, 2025Quantum Chemistry
About this book
This misconception prevents computational scientists from harnessing one of the most powerful tools for understanding matter at the atomic level. You'll discover how DFT bridges the gap between quantum mechanics and practical computation, transforming an intractable many-body problem into algorithms you can implement and optimize. This book demystifies the numerical methods behind modern electronic structure codes, showing you how to build efficient DFT implementations from the ground up. Through systematic exploration of the Kohn-Sham equations, exchange-correlation functionals, and self-consistent field methods, you'll gain deep insight into both the theoretical foundations and computational strategies that make DFT calculations possible. Each algorithm is presented with clear mathematical derivations, practical implementation details, and performance considerations for modern computing architectures. Whether you're developing new computational methods, optimizing existing codes, or simply want to understand what happens inside DFT software packages, this comprehensive guide provides the algorithmic knowledge and numerical expertise needed to master computational density functional theory.
Table of contents
- IntroductionThe Quantum Many-Body Challenge, DFT as a Computational Solution, An Algorithmic Perspective, Structure and Approach of This BookRead below
- Chapter 1: Quantum Mechanical FoundationsThe Time-Independent Schrödinger Equation, The Electronic Many-Body Problem, Born-Oppenheimer Approximation, Computational Complexity of Exact Solutions
- Chapter 2: Density Functional Theory FundamentalsHohenberg-Kohn Theorems, Electron Density as the Central Variable, Energy Functionals and Variational Principles, The Kohn-Sham Approach
- Chapter 3: Kohn-Sham Equations and Self-ConsistencyKohn-Sham Orbital Equations, The Kohn-Sham Effective Potential, Self-Consistent Field Iteration, Convergence Criteria and Monitoring
- Chapter 4: Exchange-Correlation FunctionalsLocal and Semi-Local Approximations, Local Density Approximation (LDA), Generalized Gradient Approximation (GGA), Hybrid Functionals and Exact Exchange, Computing Functional Derivatives
- Chapter 5: Basis Sets and RepresentationsBasis Set Fundamentals, Gaussian Basis Functions, Plane Wave Basis Sets, Real-Space Grid Representations, Basis Set Convergence and Completeness
- Chapter 6: Numerical Integration MethodsQuadrature Rules and Theory, Molecular Integration Grids, Atomic-Centered Grid Construction, Exchange-Correlation Energy Integration
- Chapter 7: Self-Consistent Field AlgorithmsBasic SCF Iteration Scheme, Density and Potential Mixing, DIIS Convergence Acceleration, Level Shifting and Damping Techniques
- Chapter 8: Linear Algebra and Matrix OperationsGeneralized Eigenvalue Problems, Efficient Matrix Diagonalization, Sparse Matrix Techniques, Iterative Linear System Solvers
- Chapter 9: Pseudopotentials and Core ApproximationsPseudopotential Theory and Construction, Norm-Conserving Pseudopotentials, Ultrasoft and PAW Methods, Nonlocal Pseudopotential Operators
- Chapter 10: Periodic Systems and Solid StateBloch's Theorem and k-Point Sampling, Brillouin Zone Integration, Supercell Approaches, Ewald Summation for Long-Range Interactions
- Chapter 11: Forces and Geometry OptimizationHellmann-Feynman Forces, Efficient Force Computation, Molecular Geometry Optimization, Constrained Optimization Methods
- Chapter 12: Parallel Computing and PerformanceDFT Parallelization Strategies, Domain Decomposition Methods, Load Balancing and Communication, GPU Acceleration Techniques
- Chapter 13: Advanced DFT MethodsTime-Dependent DFT Foundations, Linear Response Theory, Excited State Calculations, van der Waals Corrections
- Chapter 14: Implementation and Code DevelopmentDFT Code Architecture Design, Efficient Data Structures, Testing and Validation Strategies, Performance Analysis and Profiling
- Conclusion
- Glossary
- Further Reading
Introduction
Understanding matter at the atomic level represents one of the most fundamental challenges in computational science. When you examine a simple water molecule, you encounter a quantum mechanical system where eighteen electrons interact simultaneously through complex many-body forces. The mathematical description of this system requires solving the Schrödinger equation for all possible electron configurations—a task that becomes computationally intractable even for modest molecular systems. Traditional quantum mechanical approaches scale exponentially with system size, making direct solutions impossible for anything beyond the smallest molecules. This computational barrier has historically limited our ability to predict material properties, design new compounds, or understand chemical reactions from first principles.
Density Functional Theory emerges as a revolutionary approach that transforms this intractable many-body problem into a computationally manageable framework. Rather than tracking the positions and interactions of individual electrons, DFT reformulates quantum mechanics in terms of electron density—a three-dimensional function that describes how electrons are distributed in space. This conceptual shift reduces the complexity from dealing with 3N coordinates for N electrons to working with a single three-dimensional density function. The mathematical elegance of this transformation, established through the Hohenberg-Kohn theorems, provides both theoretical rigor and computational practicality. Modern electronic structure calculations routinely handle systems with thousands of atoms, enabling predictions of material properties, drug interactions, and catalytic processes that would be impossible with traditional quantum mechanical methods.
The computational implementation of DFT requires sophisticated numerical algorithms that bridge quantum mechanical theory with practical computing architectures. Each DFT calculation involves iterative solution of the Kohn-Sham equations, numerical integration of exchange-correlation functionals, efficient matrix diagonalization, and careful convergence monitoring. The algorithms must balance computational efficiency with numerical accuracy while handling the diverse mathematical structures that arise in electronic structure theory. Understanding these implementation details becomes crucial whether you are developing new computational methods, optimizing existing codes, or interpreting results from DFT calculations. This book provides comprehensive coverage of the algorithmic foundations that make modern DFT calculations possible, combining theoretical insights with practical implementation strategies.
The Quantum Many-Body Challenge
The fundamental challenge in computational quantum chemistry stems from the exponential scaling of the many-body Schrödinger equation. Consider a system with N electrons: the complete wavefunction depends on 3N spatial coordinates plus N spin coordinates, creating a mathematical object that lives in a 4N-dimensional space. For a modest organic molecule with 50 electrons, this corresponds to a 200-dimensional problem where the wavefunction must be represented on a computational grid. Even with a minimal discretization of 10 points per dimension, storing the wavefunction would require 10^200 numbers—far exceeding the number of atoms in the observable universe. This exponential scaling, known as the curse of dimensionality, makes direct solution of the Schrödinger equation computationally impossible for systems of chemical interest.
The mathematical structure of the electronic Hamiltonian compounds this complexity through the presence of electron-electron repulsion terms. The total energy of an N-electron system includes kinetic energy terms for each electron, attractive interactions between electrons and nuclei, and crucially, repulsive interactions between all pairs of electrons. These electron-electron interactions cannot be separated into independent single-particle problems, creating a fundamentally correlated many-body system. Traditional approaches like Hartree-Fock theory attempt to approximate these correlations through mean-field methods, but achieving chemical accuracy often requires post-Hartree-Fock techniques with even more severe computational scaling. Configuration interaction methods, for example, scale factorially with system size, limiting their application to very small molecules despite decades of algorithmic development.
The computational bottlenecks in quantum chemistry calculations manifest in several critical areas that determine practical feasibility. Matrix operations dominate the computational cost, particularly the diagonalization of large Hamiltonian matrices that grow quadratically with basis set size. For systems requiring thousands of basis functions, these matrices contain millions of elements and require sophisticated numerical linear algebra techniques. Memory requirements present another fundamental limitation: storing two-electron integrals scales as the fourth power of basis set size, quickly exhausting available computer memory. Additionally, the iterative nature of self-consistent field calculations requires repeated evaluation of expensive integrals and matrix operations, multiplying the computational cost by factors of ten to one hundred depending on convergence behavior.
Real-world molecular systems present additional computational challenges that extend beyond simple scaling considerations. Transition metal complexes involve d and f orbitals with complex nodal structures that require large basis sets for accurate representation. Biological macromolecules contain thousands of atoms with diverse chemical environments, from hydrophobic protein cores to charged active sites. Solid-state materials introduce periodic boundary conditions and require integration over the Brillouin zone, adding another layer of computational complexity. These systems demand computational methods that can handle diverse chemical bonding situations while maintaining reasonable computational cost and memory requirements.
The failure of traditional quantum mechanical approaches to handle large systems has historically created a significant gap between theoretical understanding and practical applications. Chemists studying enzyme catalysis, materials scientists designing new semiconductors, and physicists investigating magnetic materials all require quantum mechanical insights for systems far too large for conventional methods. This computational bottleneck has limited the predictive power of quantum chemistry and forced researchers to rely on empirical models or simplified approximations. The development of Density Functional Theory represents a fundamental breakthrough that addresses these limitations by reformulating the quantum mechanical problem in terms of computationally tractable variables.
Understanding the specific mathematical origins of computational complexity provides crucial insight into why DFT represents such a significant advance. The many-body wavefunction contains far more information than typically needed for chemical applications—most chemical properties depend on electron density rather than the detailed form of the wavefunction. Traditional methods expend enormous computational effort to determine wavefunction details that ultimately contribute little to observable properties. This mismatch between computational effort and chemical relevance suggests that alternative formulations focusing directly on electron density might achieve comparable accuracy with dramatically reduced computational cost. The theoretical foundation for such an approach emerged through the work of Hohenberg, Kohn, and Sham, establishing the mathematical framework that underlies modern DFT calculations.
The transition from wavefunction-based methods to density-based approaches requires careful consideration of what information is preserved and what is approximated. While the exact many-body wavefunction contains complete information about the quantum system, electron density captures the essential features needed for most chemical applications. Bond lengths, reaction energies, electronic band structures, and molecular geometries all depend primarily on how electrons are distributed in space rather than on the detailed quantum mechanical phases present in the wavefunction. This observation suggests that density-based methods might achieve chemical accuracy while avoiding the exponential scaling that plagues wavefunction methods. The mathematical formalization of this intuition through density functional theory provides both theoretical justification and practical algorithms for electronic structure calculations.
Modern computational chemistry has evolved to embrace this density-based perspective, with DFT calculations now representing the dominant approach for studying large molecular and solid-state systems. The success of DFT in predicting experimental observables across diverse chemical systems validates the fundamental insight that electron density contains the essential quantum mechanical information needed for chemical applications. However, the practical implementation of DFT requires sophisticated numerical algorithms that transform the theoretical framework into efficient computational procedures. Understanding these algorithmic details becomes essential for anyone seeking to apply DFT methods effectively or to develop new computational approaches for electronic structure problems.
DFT as a Computational Solution
Density Functional Theory revolutionizes electronic structure calculations by reformulating the quantum mechanical problem in terms of electron density rather than the many-body wavefunction. The electron density ρ(r) represents the probability of finding an electron at position r, integrated over all possible positions of the remaining electrons. This three-dimensional function contains dramatically less information than the full wavefunction but, remarkably, the Hohenberg-Kohn theorems prove that it determines all ground-state properties of the system. The mathematical transformation from a 4N-dimensional wavefunction to a three-dimensional density function reduces the computational complexity from exponential to polynomial scaling. This fundamental insight enables quantum mechanical calculations on systems containing thousands of atoms—a capability that seemed impossible with traditional wavefunction-based methods.
The practical implementation of DFT centers on the Kohn-Sham approach, which introduces a fictitious system of non-interacting electrons that produces the same electron density as the true interacting system. This clever mathematical construction allows the kinetic energy to be calculated exactly using single-particle orbitals, while electron-electron interactions are handled through classical electrostatics plus an exchange-correlation functional. The Kohn-Sham equations take the form of single-particle Schrödinger equations with an effective potential that depends on the electron density. Solving these equations iteratively through self-consistent field methods provides both the electron density and the total energy of the system. The computational cost scales as the third power of system size, making calculations feasible for large molecular and solid-state systems.
The exchange-correlation functional represents the heart of DFT accuracy and the primary source of approximation in practical calculations. This functional captures all the complex many-body effects that are not included in the kinetic energy and classical electrostatics terms. The exact form of the exchange-correlation functional remains unknown, leading to a hierarchy of approximations with different levels of sophistication and computational cost. Local density approximation (LDA) treats the exchange-correlation energy as a local function of density, while generalized gradient approximation (GGA) includes dependence on density gradients. Hybrid functionals incorporate a fraction of exact exchange, improving accuracy for many chemical systems at the cost of increased computational complexity. The choice of exchange-correlation functional significantly impacts both the accuracy and computational requirements of DFT calculations.
Numerical implementation of DFT requires sophisticated algorithms for several key computational tasks that determine both accuracy and efficiency. Basis set representation of the Kohn-Sham orbitals involves choosing between localized functions like Gaussians or delocalized functions like plane waves, each with distinct advantages for different types of systems. Numerical integration of the exchange-correlation energy requires specialized quadrature schemes that handle the complex structure of atomic and molecular densities. Self-consistent field convergence demands careful mixing of input and output densities to achieve stable iteration, often requiring acceleration techniques like DIIS (Direct Inversion in the Iterative Subspace). Matrix diagonalization for the Kohn-Sham equations becomes the computational bottleneck for large systems, necessitating efficient linear algebra algorithms and parallel computing strategies.
The computational advantages of DFT extend beyond simple scaling considerations to include favorable memory requirements and parallelization properties. Unlike post-Hartree-Fock methods that require storage of four-index electron repulsion integrals, DFT calculations work primarily with two-index quantities like density matrices and overlap integrals. This reduced memory footprint enables calculations on larger systems and simplifies implementation on distributed computing architectures. The local nature of exchange-correlation functionals facilitates domain decomposition approaches where different processors handle different spatial regions. Additionally, the iterative structure of self-consistent field calculations allows for efficient checkpointing and restart capabilities, essential for long-running calculations on large systems.
Real-world applications demonstrate the transformative impact of DFT on computational chemistry and materials science. Pharmaceutical companies routinely use DFT calculations to predict drug-target interactions and optimize molecular properties before synthesis. Materials scientists employ DFT to design new catalysts, semiconductors, and energy storage materials by predicting electronic and structural properties from first principles. Biochemists study enzyme mechanisms and protein folding using DFT calculations on active site models containing hundreds of atoms. These applications would be impossible with traditional quantum chemical methods, highlighting how DFT has expanded the scope of computational chemistry to address problems of direct technological and scientific importance.
The success of DFT in diverse chemical applications stems from its ability to capture essential quantum mechanical effects while remaining computationally tractable. Chemical bonding, reaction energetics, and electronic properties all depend primarily on electron density distributions rather than detailed wavefunction structure. DFT calculations typically achieve chemical accuracy (errors of 1-5 kcal/mol) for thermochemical properties, making them reliable for predicting experimental observables. The method handles different types of chemical bonding—covalent, ionic, metallic, and hydrogen bonding—within a unified theoretical framework. This versatility, combined with favorable computational scaling, has made DFT the method of choice for electronic structure calculations across chemistry, physics, and materials science.
Modern DFT implementations leverage advanced computational techniques to achieve maximum efficiency and accuracy for large-scale calculations. Linear scaling algorithms reduce the computational cost from cubic to linear dependence on system size for sufficiently large systems with localized electronic structure. Pseudopotential methods eliminate the need to treat core electrons explicitly, focusing computational effort on chemically relevant valence electrons. Parallel computing architectures, including both traditional CPU clusters and modern GPU accelerators, enable calculations on systems with tens of thousands of atoms. These algorithmic and technological advances continue to expand the range of systems accessible to DFT calculations, opening new frontiers in computational chemistry and materials science.
The theoretical foundation of DFT provides confidence in its predictions while acknowledging the limitations imposed by exchange-correlation approximations. The Hohenberg-Kohn theorems guarantee that exact DFT would provide exact ground-state properties, establishing a clear target for functional development. Systematic improvement of exchange-correlation functionals continues through incorporation of additional physical effects like dispersion interactions, self-interaction corrections, and non-local correlation. Understanding both the strengths and limitations of different DFT approximations becomes crucial for choosing appropriate methods for specific applications and interpreting computational results in the context of experimental observations.
An Algorithmic Perspective
The computational implementation of Density Functional Theory requires a sophisticated interplay of numerical algorithms that transform theoretical equations into efficient computer code. At the algorithmic level, DFT calculations involve several distinct computational phases, each with unique numerical challenges and optimization opportunities. The self-consistent field iteration forms the outer loop, requiring convergence of the electron density through repeated solution of the Kohn-Sham equations. Within each iteration, matrix diagonalization dominates the computational cost, typically consuming 60-80% of the total calculation time for large systems. Numerical integration of exchange-correlation functionals requires specialized quadrature schemes that adapt to the varying length scales present in atomic and molecular systems. Understanding these algorithmic components and their interactions becomes essential for developing efficient DFT implementations or optimizing existing codes for specific applications.
Matrix operations in DFT calculations present unique computational challenges that differ significantly from typical scientific computing applications. The overlap matrix S and Hamiltonian matrix H are both Hermitian and positive definite, but their condition numbers can vary dramatically depending on the basis set and molecular geometry. The generalized eigenvalue problem HC = SCE requires specialized algorithms that maintain numerical stability while achieving optimal computational performance. For large systems, iterative diagonalization methods like Davidson or Lanczos algorithms become essential, as they avoid the cubic scaling of direct diagonalization methods. The sparse structure of these matrices in localized basis sets enables further optimization through sparse matrix techniques, but requires careful attention to data structures and memory access patterns to achieve optimal performance on modern computing architectures.
Numerical integration algorithms in DFT must handle the complex spatial structure of electron densities and exchange-correlation functionals with high accuracy and efficiency. Molecular integration grids typically combine atomic-centered spherical grids with sophisticated partitioning schemes that ensure smooth transitions between atomic regions. The radial component uses specialized quadrature rules like Gauss-Chebyshev or exponential grids that concentrate points near atomic nuclei where densities vary rapidly. Angular integration employs Lebedev grids that maintain spherical symmetry while providing exact integration of spherical harmonics up to a specified order. The total number of grid points can reach millions for large molecules, making efficient grid generation and density evaluation crucial for overall performance. Adaptive grid refinement techniques dynamically adjust point density based on local density gradients, optimizing the balance between accuracy and computational cost.
Self-consistent field convergence algorithms must balance stability and efficiency while handling the nonlinear nature of the Kohn-Sham equations. Simple mixing schemes like linear combination of input and output densities often exhibit slow convergence or oscillatory behavior, particularly for systems with small HOMO-LUMO gaps or complex electronic structure. Advanced mixing methods like Pulay's DIIS (Direct Inversion in the Iterative Subspace) accelerate convergence by extrapolating optimal input densities from the history of previous iterations. The algorithm maintains a set of density differences and corresponding error vectors, solving a linear system to determine optimal mixing coefficients. Level shifting techniques artificially increase orbital energy gaps during early iterations, improving convergence stability at the cost of slightly modified eigenvalues. Damping methods reduce the magnitude of density updates when convergence problems arise, trading convergence speed for stability.
Memory management and data structure design significantly impact the performance and scalability of DFT implementations. The electron density must be stored and manipulated on integration grids containing millions of points, requiring efficient data structures that minimize memory bandwidth requirements. Basis function evaluation at grid points involves expensive exponential and polynomial calculations that benefit from vectorization and caching strategies. The density matrix, containing basis function pair information, exhibits sparsity patterns that depend on molecular geometry and basis set locality. Exploiting this sparsity through compressed storage formats and specialized algorithms can reduce both memory requirements and computational cost. For parallel implementations, data distribution strategies must balance computational load while minimizing communication overhead, particularly for the global operations required in matrix diagonalization and density integration.
Parallel computing algorithms for DFT calculations must address the diverse computational patterns present in different phases of the calculation. Matrix diagonalization requires global communication for eigenvalue problems, making it challenging to scale to large numbers of processors. Domain decomposition approaches distribute integration grids across processors, enabling efficient parallelization of exchange-correlation energy and potential calculations. The two-electron integral evaluation can be parallelized over basis function quartets, but requires careful load balancing due to the varying computational cost of different integral types. Hybrid parallelization strategies combine MPI for inter-node communication with OpenMP or GPU acceleration for intra-node parallelism, maximizing utilization of modern heterogeneous computing architectures. Communication-avoiding algorithms minimize data movement by restructuring calculations to maximize local computation and reduce global synchronization points.
Algorithmic complexity analysis reveals the computational bottlenecks that limit DFT scalability and guides optimization efforts. The formal O(N³) scaling of matrix diagonalization can be reduced to O(N) for sufficiently large systems with localized electronic structure using linear scaling algorithms. These methods exploit the exponential decay of density matrix elements to truncate long-range interactions while maintaining chemical accuracy. However, the crossover point where linear scaling becomes advantageous depends on system size, electronic structure, and implementation details. For many practical applications, conventional cubic scaling algorithms remain more efficient due to their superior prefactors and simpler implementation. Understanding these scaling relationships helps guide algorithm selection and system size planning for computational studies.
Error analysis and numerical precision considerations play crucial roles in DFT algorithm design and validation. Basis set truncation errors decrease systematically with basis set size but at the cost of increased computational requirements. Integration grid errors depend on grid density and can be controlled through convergence testing with successively finer grids. Self-consistent field convergence criteria must balance computational cost with numerical precision, typically requiring energy convergence of 10⁻⁶ to 10⁻⁸ hartree for reliable results. Round-off errors in matrix operations can accumulate during iterative procedures, particularly for ill-conditioned systems or extended calculations. Careful numerical analysis and validation against reference calculations ensures that algorithmic approximations do not compromise the physical accuracy of DFT predictions.
Modern algorithmic developments continue to push the boundaries of DFT computational efficiency and applicability. Machine learning techniques accelerate expensive components like exchange-correlation functional evaluation or basis set optimization through trained surrogate models. Quantum computing algorithms explore potential advantages for specific DFT components, though practical quantum advantage remains a long-term prospect. Automatic differentiation enables efficient computation of analytical derivatives for geometry optimization and property calculations. These algorithmic innovations, combined with advances in computer hardware, continue to expand the range of systems and properties accessible to DFT calculations, opening new frontiers in computational chemistry and materials science.
Structure and Approach of This Book
This book adopts a systematic approach that builds from fundamental quantum mechanical principles to practical implementation details, ensuring that you develop both theoretical understanding and computational expertise. The early chapters establish the quantum mechanical foundation, explaining why traditional approaches fail for large systems and how DFT reformulates the problem in computationally tractable terms. The middle chapters focus on the core algorithms that form the heart of any DFT implementation: solving the Kohn-Sham equations, evaluating exchange-correlation functionals, and achieving self-consistent convergence. The later chapters address advanced topics including parallel computing, specialized methods for periodic systems, and modern algorithmic developments. Each chapter includes detailed mathematical derivations, algorithmic pseudocode, and practical implementation considerations that bridge the gap between theory and working computer code.
The mathematical presentation balances rigor with accessibility, providing complete derivations while emphasizing the computational implications of theoretical results. Key equations are presented in forms that directly translate to computer algorithms, with explicit attention to numerical stability and computational efficiency. Mathematical concepts are illustrated through concrete examples that demonstrate both correct implementation and common pitfalls. The notation remains consistent throughout the book, with a comprehensive glossary that defines all symbols and technical terms. Footnotes provide references to original literature and additional mathematical details for readers seeking deeper understanding. This approach ensures that the book serves both as a learning resource and as a practical reference for implementation projects.
Algorithmic content emphasizes practical implementation details that are often omitted from theoretical treatments but prove crucial for successful code development. Each major algorithm is presented through multiple perspectives: high-level pseudocode that captures the essential logic, detailed implementation notes that address numerical issues, and performance analysis that guides optimization efforts. Common implementation mistakes are highlighted with specific examples of incorrect approaches and their consequences. Memory management, data structure design, and computational complexity receive explicit attention throughout the algorithmic discussions. The goal is to provide sufficient detail that a competent programmer could implement the algorithms successfully while understanding the design decisions that impact performance and accuracy.
Code examples and implementation strategies are presented in a language-agnostic manner that emphasizes algorithmic concepts rather than specific programming syntax. Pseudocode uses clear, mathematical notation that translates readily to any programming language while avoiding the syntactic details that can obscure algorithmic content. Where specific implementation details matter—such as memory layout for matrix operations or parallel communication patterns—the discussion includes concrete examples with explicit performance implications. The focus remains on understanding the computational structure of DFT algorithms rather than mastering particular software libraries or programming environments. This approach ensures that the content remains relevant across different computing platforms and programming languages.
Practical considerations receive equal attention with theoretical development, reflecting the reality that successful DFT implementations require careful attention to numerical and computational details. Convergence criteria, error analysis, and validation strategies are discussed in detail with specific recommendations for different types of calculations. Performance optimization techniques are presented with quantitative analysis of their impact on computational cost and memory requirements. Parallel computing strategies include both theoretical scaling analysis and practical considerations for implementation on modern computing architectures. The treatment of these practical issues draws on decades of experience in DFT code development, providing insights that are typically learned through trial and error rather than formal instruction.
The progression through topics follows the logical structure of a DFT calculation while building computational sophistication gradually. Early chapters focus on single-processor algorithms and exact mathematical relationships, establishing a solid foundation before introducing approximations and parallel computing complications. The treatment of exchange-correlation functionals begins with simple local approximations before progressing to more sophisticated gradient-corrected and hybrid methods. Basis set discussions start with conceptual issues before addressing the numerical linear algebra challenges that dominate computational cost. This pedagogical approach ensures that you understand the fundamental principles before tackling the implementation complexities that arise in production DFT codes.
Advanced topics in later chapters build on the foundational material while addressing specialized applications and cutting-edge developments. The treatment of periodic systems extends molecular DFT concepts to solid-state applications, with detailed discussion of k-point sampling and Brillouin zone integration. Time-dependent DFT introduces the additional complexity of excited state calculations while building on the ground-state formalism developed earlier. Parallel computing strategies are presented as natural extensions of single-processor algorithms rather than completely separate topics. This integrated approach helps you understand how advanced methods relate to the core DFT framework and how they can be incorporated into existing implementations.
Each chapter includes exercises and projects that reinforce the material through hands-on implementation experience. Simple programming exercises focus on specific algorithmic components like numerical integration or matrix diagonalization, allowing you to master individual techniques before combining them into complete DFT implementations. Larger projects guide you through the development of simplified but functional DFT codes that demonstrate the integration of multiple algorithmic components. Theoretical exercises explore mathematical relationships and derive key results that are used in the algorithmic development. These exercises serve both as learning tools and as validation that you have mastered the essential concepts needed for successful DFT implementation.
The book concludes with guidance on code development practices, testing strategies, and performance analysis techniques that are essential for developing robust and efficient DFT implementations. Software engineering principles are discussed in the context of scientific computing, with emphasis on code organization, documentation, and version control practices that facilitate collaborative development. Testing methodologies include both unit tests for individual algorithmic components and integration tests that validate complete calculations against reference results. Performance analysis techniques help identify computational bottlenecks and guide optimization efforts. This practical guidance reflects the reality that modern DFT codes are complex software systems that require careful engineering practices to achieve reliability and maintainability alongside computational performance.
This is the end of the free sample. The full book has 14 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Quantum Chemistry knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Quantum Chemistry book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Quantum Chemistry book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
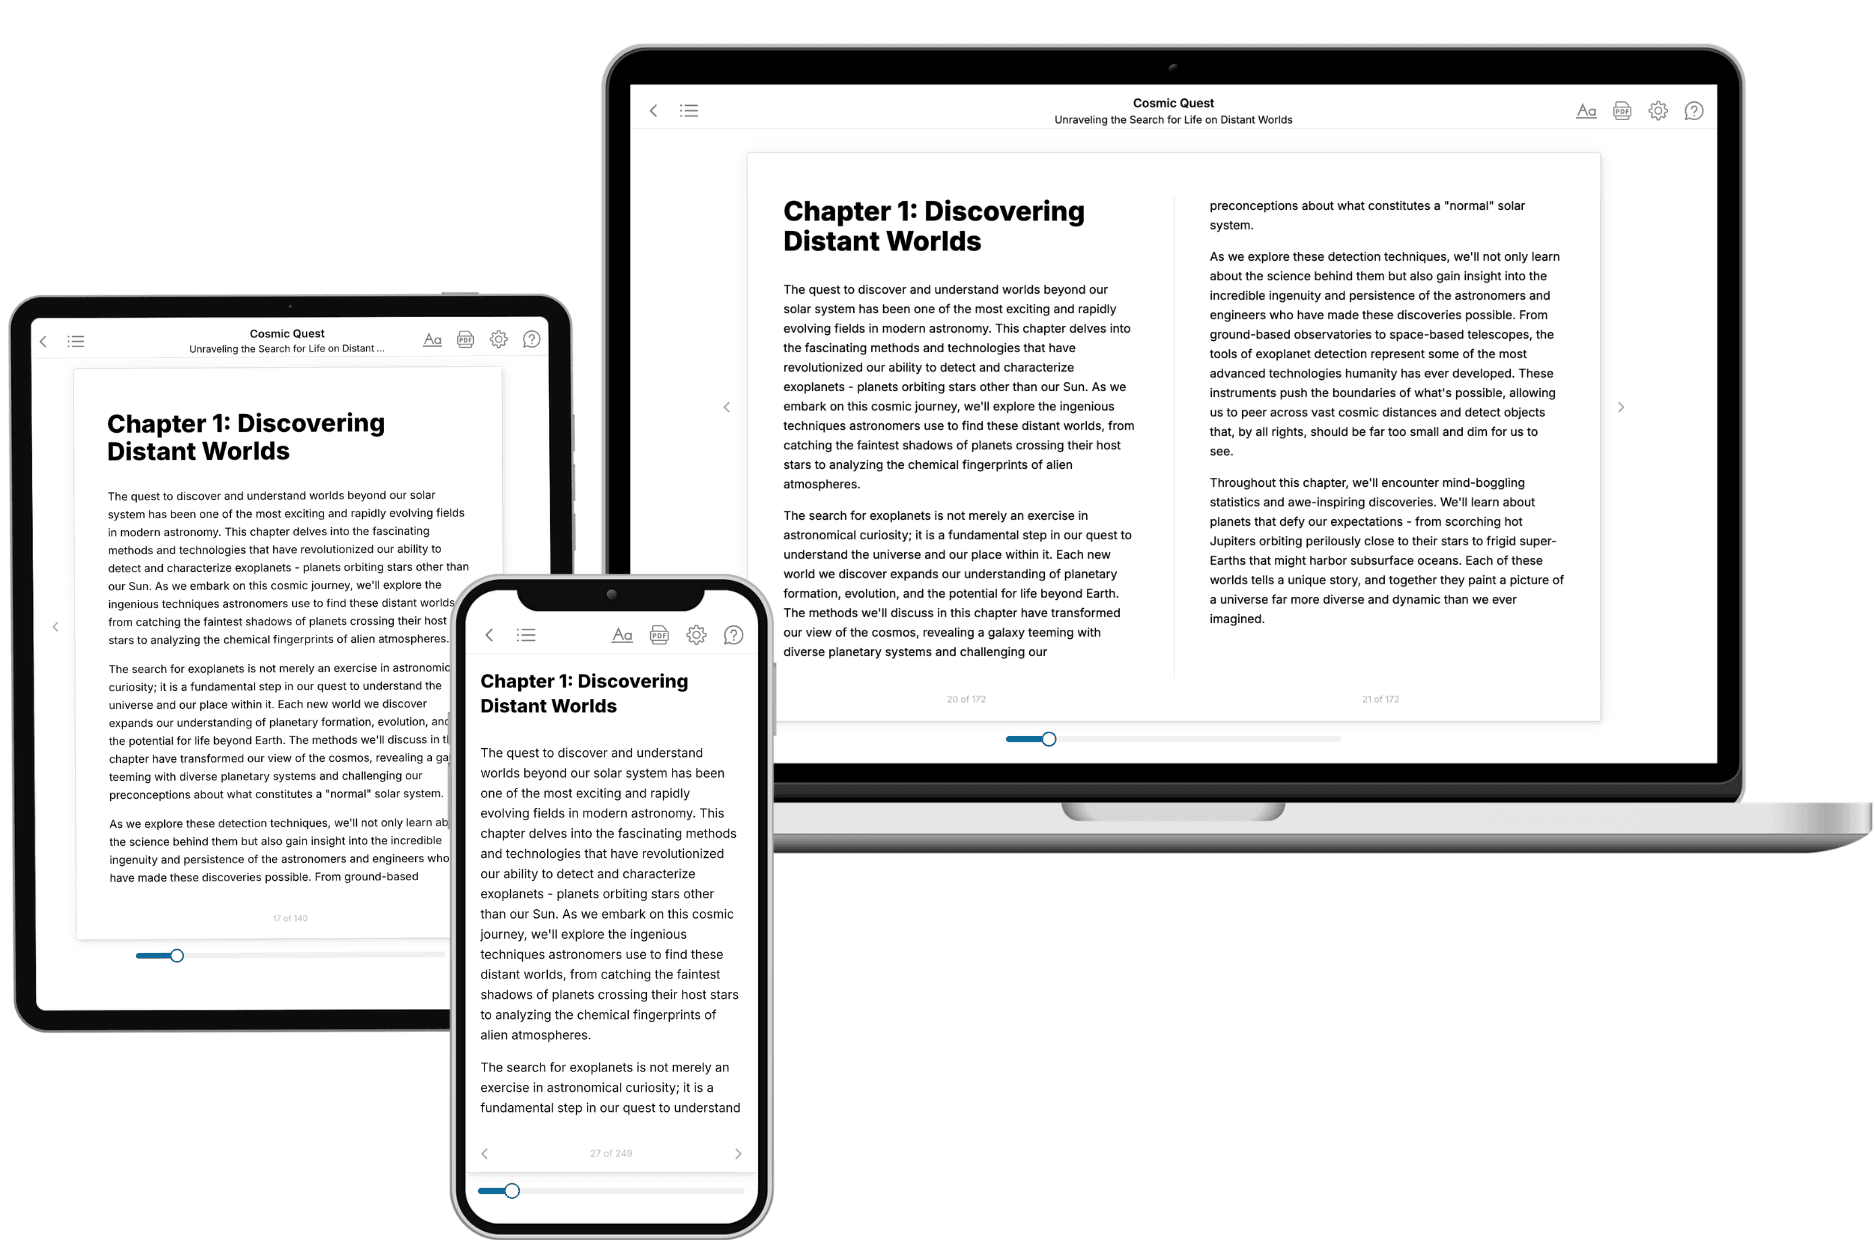
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.