Cross Validation in Monte Carlo Integration
Master the Art of Validating Numerical Integration Methods
Imagine confidently deploying Monte Carlo integration methods knowing exactly how reliable your results truly are.
207 pages9 chaptersJul 26, 2026Monte Carlo Integration
About this book
This book bridges the gap between theoretical understanding and practical application of cross validation techniques in numerical integration. You'll discover how to systematically validate your integration methods, detect hidden biases in your estimates, and build robust computational workflows. Whether you're working with low-dimensional integrals or navigating high-dimensional spaces, you'll learn concrete strategies for assessing accuracy, managing computational trade-offs, and implementing validation frameworks that work in real-world scenarios. This comprehensive guide combines mathematical rigor with practical implementation guidance, giving you the tools to transform uncertainty into confidence in your numerical results.
Table of contents
- IntroductionWhy Validation Matters in Numerical Integration, Monte Carlo Integration: A Quick Primer, Cross Validation Fundamentals, How to Use This BookRead below
- Chapter 1: Foundations of Monte Carlo IntegrationRandom Sampling Principles, Understanding Convergence Rates, Sources of Error in Monte Carlo Methods
- Chapter 2: Cross Validation Theory and ConceptsValidation vs. Testing: Key Distinctions, The Bias-Variance Tradeoff in Validation, Statistical Foundations of Cross Validation
- Chapter 3: K-Fold Cross Validation for IntegrationHow K-Fold Cross Validation Works, Choosing the Optimal K Value, Implementing K-Fold in Practice
- Chapter 4: Leave-One-Out and Advanced TechniquesLeave-One-Out Cross Validation, Managing Computational Costs, Nested Cross Validation Strategies
- Chapter 5: Variance Reduction and ValidationImportance Sampling and Cross Validation, Stratified Sampling Validation, Control Variates and Validation Interaction
- Chapter 6: Error Estimation and Confidence IntervalsEstimating True Integration Error, Building Reliable Confidence Intervals, Detecting Systematic Bias Through Validation
- Chapter 7: High-Dimensional Integration ChallengesThe Curse of Dimensionality, Adapting Cross Validation for High Dimensions, Sample Size and Validation Trade-offs
- Chapter 8: Practical Implementation and WorkflowsDesigning Your Validation Pipeline, Tools and Libraries for Cross Validation, Best Practices and Common Pitfalls
- Chapter 9: Case Studies and Real-World ApplicationsFinancial Modeling and Risk Assessment, Physics Simulations and Scientific Computing, Integration in Machine Learning Pipelines
- ConclusionKey Takeaways, Future Directions in Validation Research
- Glossary of Terms
- Further Reading and Resources
Introduction
A Monte Carlo integration routine returns a number. That number comes with an estimated error, usually derived from the sample variance of the integrand evaluations. Most practitioners stop there, trusting that number as a faithful representation of the true integration error. But the sample-based error estimate and the actual error in the result are not the same thing, and the gap between them can be surprisingly large. When the integrand has structure that the sampler does not capture well, or when the sampling strategy has been tuned to look good on a particular region of the domain, the reported error can be optimistic by an order of magnitude or more.
This is not a theoretical concern. In financial risk modeling, an underestimated integration error translates directly into mispriced derivatives or miscalculated Value-at-Risk figures. In physics simulations, it means confidence intervals that do not actually contain the true quantity being estimated at the stated probability. In machine learning, it means normalization constants or expected values that feed downstream models with quietly corrupted inputs. The consequences are real, and they are often invisible until something breaks in production or a result fails to replicate.
Cross Validation offers a principled way to close that gap. Originally developed in the context of statistical model selection, Cross Validation is fundamentally a technique for estimating how well a procedure generalizes beyond the data it was applied to. When adapted to Monte Carlo Integration, it becomes a tool for asking a sharper question than the standard error formula answers: not just "how variable are my samples?" but "how well does my integration estimate hold up when evaluated on data it has not seen?" That distinction is the foundation of everything this book builds toward.
The chapters that follow move from mathematical foundations through concrete implementation, covering K-Fold Cross Validation, Leave-One-Out Cross Validation, Nested Cross Validation, and their interactions with Variance Reduction techniques like Importance Sampling, Stratified Sampling, and Control Variates. Each concept is grounded in the specific demands of numerical integration, not borrowed wholesale from machine learning without adaptation. The goal throughout is to give you both the theory to understand why these methods work and the practical detail to apply them in your own computational workflows.
Why Validation Matters in Numerical Integration
Numerical integration methods are evaluated by how close their output is to the true value of the integral. The problem is that the true value is almost never known in advance. If it were, there would be no need to integrate numerically. This creates a fundamental challenge: you need to assess the quality of an answer without access to the ground truth. Standard error estimates fill this role partially, but they carry assumptions that are often violated in practice.
The standard Monte Carlo error estimate is derived from the Central Limit Theorem (MC context). It assumes that the sample mean estimator converges to the true integral at a rate proportional to 1/√N, where N is the number of samples. This convergence guarantee is real, but it describes asymptotic behavior. For any finite N, the actual error depends heavily on the variance of the integrand under the sampling distribution. If that variance is poorly estimated, the error bound is poorly estimated too.[1]
Consider a concrete example. Suppose you are integrating a function that is nearly zero across 95% of its domain but has a sharp, high-amplitude spike in the remaining 5%. A uniform random sampler will miss that spike most of the time. When it does miss it, the sample variance will be low, the error estimate will look small, and the result will be confidently wrong. This is not a pathological edge case. It describes a large class of integrands that appear in option pricing, particle transport, and Bayesian posterior normalization.
A low reported error is not evidence of a good estimate. It is evidence that the sampler did not encounter the hard parts of the integrand. Validation is the process of checking whether those hard parts were actually covered.
Validation in numerical integration means deliberately testing your estimator against held-out samples or held-out subregions of the domain. The logic is similar to how a machine learning practitioner holds out a Test Set to check whether a model has overfit to training data. In the integration context, Overfitting has a specific meaning: the sampling strategy or the estimator has been implicitly tuned to perform well on the samples it drew, and that performance does not generalize to the full domain.
This kind of implicit tuning happens more often than practitioners realize. Adaptive sampling methods, for instance, concentrate samples in regions where the integrand is large or variable. That is exactly what you want for efficiency. But it also means the sampler has learned something about the integrand from the data it collected, and the error estimate based on those same samples is no longer unbiased. Cross Validation provides a way to detect and correct for this effect.
The practical stakes are straightforward. A validated integration result comes with an error estimate that has been tested against data the estimator did not use to produce the result. An unvalidated result comes with an error estimate that is, at best, a self-reported grade. For any application where the integration result feeds a decision, a model, or a published finding, the difference between those two situations is the difference between a result you can defend and one you cannot.
Validation also surfaces Systematic Bias, which is distinct from random error. A biased estimator returns values that are consistently too high or too low, regardless of how many samples are drawn. Standard error estimates based on sample variance do not detect bias at all. Cross Validation, by comparing estimates across independent subsets of samples, can reveal systematic offsets that would otherwise remain hidden. The chapter on error estimation covers this in detail, but the principle is worth establishing here: variance and bias are separate problems, and they require separate diagnostic tools.
Monte Carlo Integration: A Quick Primer
Monte Carlo Integration estimates a definite integral by drawing random samples from a probability distribution over the integration domain and averaging the integrand values at those sample points. The method is named after the Monte Carlo Casino in Monaco, a reference to the role of randomness at its core. Its appeal is that the Convergence Rate of O(1/√N) is independent of the dimension of the integration domain, which makes it uniquely suited to high-dimensional problems where deterministic quadrature methods become computationally infeasible.[2]
The basic procedure works as follows. To estimate the integral of a function f(x) over a domain D with respect to a probability measure p(x), you draw N independent samples x₁, x₂, ..., xN from p(x) and compute the Sample Mean Estimator:
Î = (1/N) * Σ f(xᵢ) / p(xᵢ) for i = 1 to NThis estimator is unbiased under mild regularity conditions, meaning its expected value equals the true integral. The variance of the estimator decreases as 1/N, which is why the standard deviation (the typical error) decreases as 1/√N. The Central Limit Theorem (MC context) then guarantees that for large N, the distribution of the estimator is approximately normal, which is what allows the construction of Confidence Intervals (MC) around the estimate.
Random Sampling is the engine of the method, and the choice of sampling distribution p(x) has a large effect on efficiency. Uniform sampling over the domain is the simplest choice, but it is rarely the best one. Importance Sampling replaces the uniform distribution with one that concentrates samples where the integrand is large, reducing variance without changing the expected value of the estimator. Stratified Sampling divides the domain into subregions and samples each one independently, ensuring coverage across the full domain. Control Variates use a related function with a known integral to reduce the variance of the estimator further. These Variance Reduction techniques are covered in depth in the chapter dedicated to them.
The sources of error in Monte Carlo Integration fall into two categories. The first is statistical error, which arises from the randomness of the sampling process and decreases predictably with N. The second is systematic error, which arises from biases in the sampling strategy, numerical precision issues, or structural mismatches between the sampling distribution and the integrand. Statistical error is visible in the sample variance. Systematic error is not, and it is the primary target of Cross Validation as a diagnostic tool.
One important property of Monte Carlo Integration is that its Convergence Rate does not depend on the smoothness of the integrand. Deterministic methods like Gaussian quadrature converge much faster for smooth functions, but their convergence degrades sharply when the integrand has discontinuities, sharp gradients, or high-dimensional structure. Monte Carlo Integration handles all of these cases with the same O(1/√N) rate, which is why it dominates in applications like Financial Risk Monte Carlo, Physics Simulation Validation, and ML Pipeline Integration where the integrands are complex and high-dimensional.
Understanding these mechanics is a prerequisite for understanding why Cross Validation is necessary. The method's reliance on random samples means that any single run of the estimator is a random variable. Two runs with different random seeds will produce different results. The question Cross Validation answers is whether those results are consistently close to the true integral, or whether they are variable in ways that the standard error estimate does not capture. The chapter on Monte Carlo foundations develops these mechanics in full mathematical detail; this primer is enough to follow the validation concepts introduced here.
Cross Validation Fundamentals
Cross Validation is a resampling procedure that estimates how well a method performs on data it was not trained or tuned on. In its most general form, it works by partitioning available data into subsets, using some subsets to fit or run the method, and using the remaining subsets to evaluate performance. The evaluation on held-out data gives an estimate of Generalization Error, which is the error the method would produce on genuinely new data from the same distribution.
The concept originated in statistical model selection, where the goal is to choose between competing models without Overfitting to the available data. A model that is evaluated only on the data used to fit it will appear better than it actually is, because it has had the opportunity to adapt to the specific noise patterns in that data. Holding out a Validation Set and evaluating on it instead gives a more honest picture of performance. The same logic applies directly to Monte Carlo Integration when the sampling strategy has been adapted to the integrand.
The Bias-Variance Tradeoff is central to understanding how Cross Validation works. A validation procedure that uses very little held-out data will have low bias (it uses most of the data for estimation) but high variance (the held-out evaluation is noisy). A procedure that holds out a lot of data will have lower variance in the evaluation but higher bias in the estimation step, because less data was used to produce the estimate. K-Fold Cross Validation manages this tradeoff by rotating the held-out subset across K different partitions and averaging the results, giving a more stable estimate than any single split.
In the context of Monte Carlo Integration, the "data" is the set of sample points drawn from the domain, and the "model" is the integration estimator. The key insight is that the sample points are not just inputs to the estimator; they are also the only evidence available about the integrand's behavior. When the same sample points are used both to run the estimator and to evaluate its error, the error estimate is optimistic. Cross Validation separates these two roles by using different subsets of sample points for estimation and evaluation.
Here is a concrete illustration of how this works in practice. Suppose you draw 1,000 sample points and use all of them to compute a Monte Carlo estimate. The sample variance of those 1,000 evaluations gives you an error estimate. Now suppose instead you split the 1,000 points into 10 groups of 100. For each group, you compute an estimate using only that group's 100 points, then compare it to the estimate from the other 900 points. The spread of those 10 comparisons gives you a different, and often more reliable, picture of the estimator's variability. That is the core of K-Fold Cross Validation applied to integration.
Leave-One-Out Cross Validation (LOO-CV) takes this to the extreme by holding out one sample point at a time and repeating the process N times. This gives the lowest-bias estimate of Generalization Error but at a Computational Cost (CV) that scales linearly with N. For large Monte Carlo runs, this can be prohibitive. The chapter on advanced techniques covers when LOO-CV is worth the cost and when K-Fold Cross Validation is a better choice.
Nested Cross Validation adds another layer by using an outer loop to estimate Generalization Error and an inner loop to select or tune the sampling strategy. This is particularly relevant when Importance Sampling or other adaptive methods are being used, because those methods have parameters (like the proposal distribution) that need to be chosen without looking at the evaluation data. Nested Cross Validation ensures that the tuning and the evaluation remain independent, preventing a subtle form of data leakage that can make results look better than they are.
The distinction between a Validation Set and a Test Set is worth clarifying here, because it matters for how results are reported. The Validation Set is used during the development of the method, to guide choices about sampling strategy, sample size, and estimator design. The Test Set is held out entirely until the final evaluation, and it is used only once. Using the Test Set multiple times, even to make small adjustments, converts it into a Validation Set and invalidates its role as an unbiased performance estimate. This discipline is standard in machine learning and equally important in Monte Carlo Integration workflows.
How to Use This Book
This book is organized to build understanding progressively, but it is also designed so that experienced practitioners can navigate directly to the topics most relevant to their work. The chapters follow a logical sequence from mathematical foundations through implementation and application, but each chapter is written to be as self-contained as possible, with explicit pointers to the foundational material it depends on.
The first two chapters establish the mathematical and statistical foundations. The chapter on Monte Carlo foundations covers Random Sampling, Convergence Rate, and the sources of error that Cross Validation is designed to detect. The chapter on Cross Validation theory covers the Bias-Variance Tradeoff, the distinction between Validation Set and Test Set, and the statistical reasoning behind why held-out evaluation gives more reliable error estimates than in-sample evaluation. If you are already comfortable with both of these areas, you can move directly to the K-Fold chapter and refer back as needed.
The middle section of the book, covering K-Fold Cross Validation, Leave-One-Out Cross Validation, Nested Cross Validation, and Variance Reduction interactions, is where the core technical content lives. These chapters are sequential in the sense that each one builds on the previous, but they are also modular. If your primary interest is in Stratified Sampling validation, for instance, you can read the Variance Reduction chapter after reading the K-Fold chapter, without needing to work through the Leave-One-Out material first.
The chapter on error estimation and Confidence Intervals (MC) is particularly important for practitioners who need to report results formally. It covers Coverage Probability, the detection of Systematic Bias through Cross Validation, and the construction of error bounds that are honest about what they do and do not guarantee. This chapter draws on all the preceding material and is best read after the K-Fold and Leave-One-Out chapters.
The chapter on high-dimensional integration addresses the Curse of Dimensionality as it specifically affects Cross Validation reliability. This is not a general treatment of high-dimensional Monte Carlo; it focuses on the ways that Concentration of Measure and sparse coverage degrade the diagnostic power of Cross Validation, and on Dimension-Adaptive Cross Validation strategies that partially compensate. If your work involves integrals in more than roughly 10 dimensions, this chapter is essential reading before applying the earlier methods.
The implementation chapter translates all the preceding theory into a concrete Validation Pipeline. It covers library selection, Reproducibility practices, and the avoidance of Data Leakage in computational workflows. It includes worked examples in Python using standard scientific computing libraries, with enough detail to adapt the code to your own integration problems. The chapter on case studies then grounds everything in three domain-specific applications: Financial Risk Monte Carlo, Physics Simulation Validation, and ML Pipeline Integration. Each case study walks through a complete validation workflow, from problem setup through result interpretation.
A few practical notes on how to get the most from the material. The mathematical notation is kept consistent throughout the book, with a Glossary at the end for reference. Canonical terms are used exactly as defined in the Glossary, so if a term appears unfamiliar, checking there first will usually resolve the confusion. The code examples are written for clarity rather than maximum performance; they are starting points for your own implementations, not production-ready libraries.
The book assumes familiarity with probability theory at the level of expectation, variance, and the Central Limit Theorem (MC context), and with basic numerical methods at the level of understanding what a quadrature rule does. It does not assume prior knowledge of Cross Validation or of the specific ways Monte Carlo Integration differs from other numerical methods. If you have worked with Monte Carlo methods in any domain and want to understand how to assess their reliability more rigorously, the material here is written for you.
One final orientation point: the goal of this book is not to make Monte Carlo Integration more complicated. The method's simplicity is one of its genuine strengths. The goal is to make the assessment of Monte Carlo results more honest, so that the confidence you place in a numerical answer is proportional to the evidence supporting it. Cross Validation is the tool that makes that proportionality possible, and by the end of the book, applying it should feel as natural as computing the sample variance does now.
This is the end of the free sample. The full book has 9 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Monte Carlo Integration knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Monte Carlo Integration book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Monte Carlo Integration book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
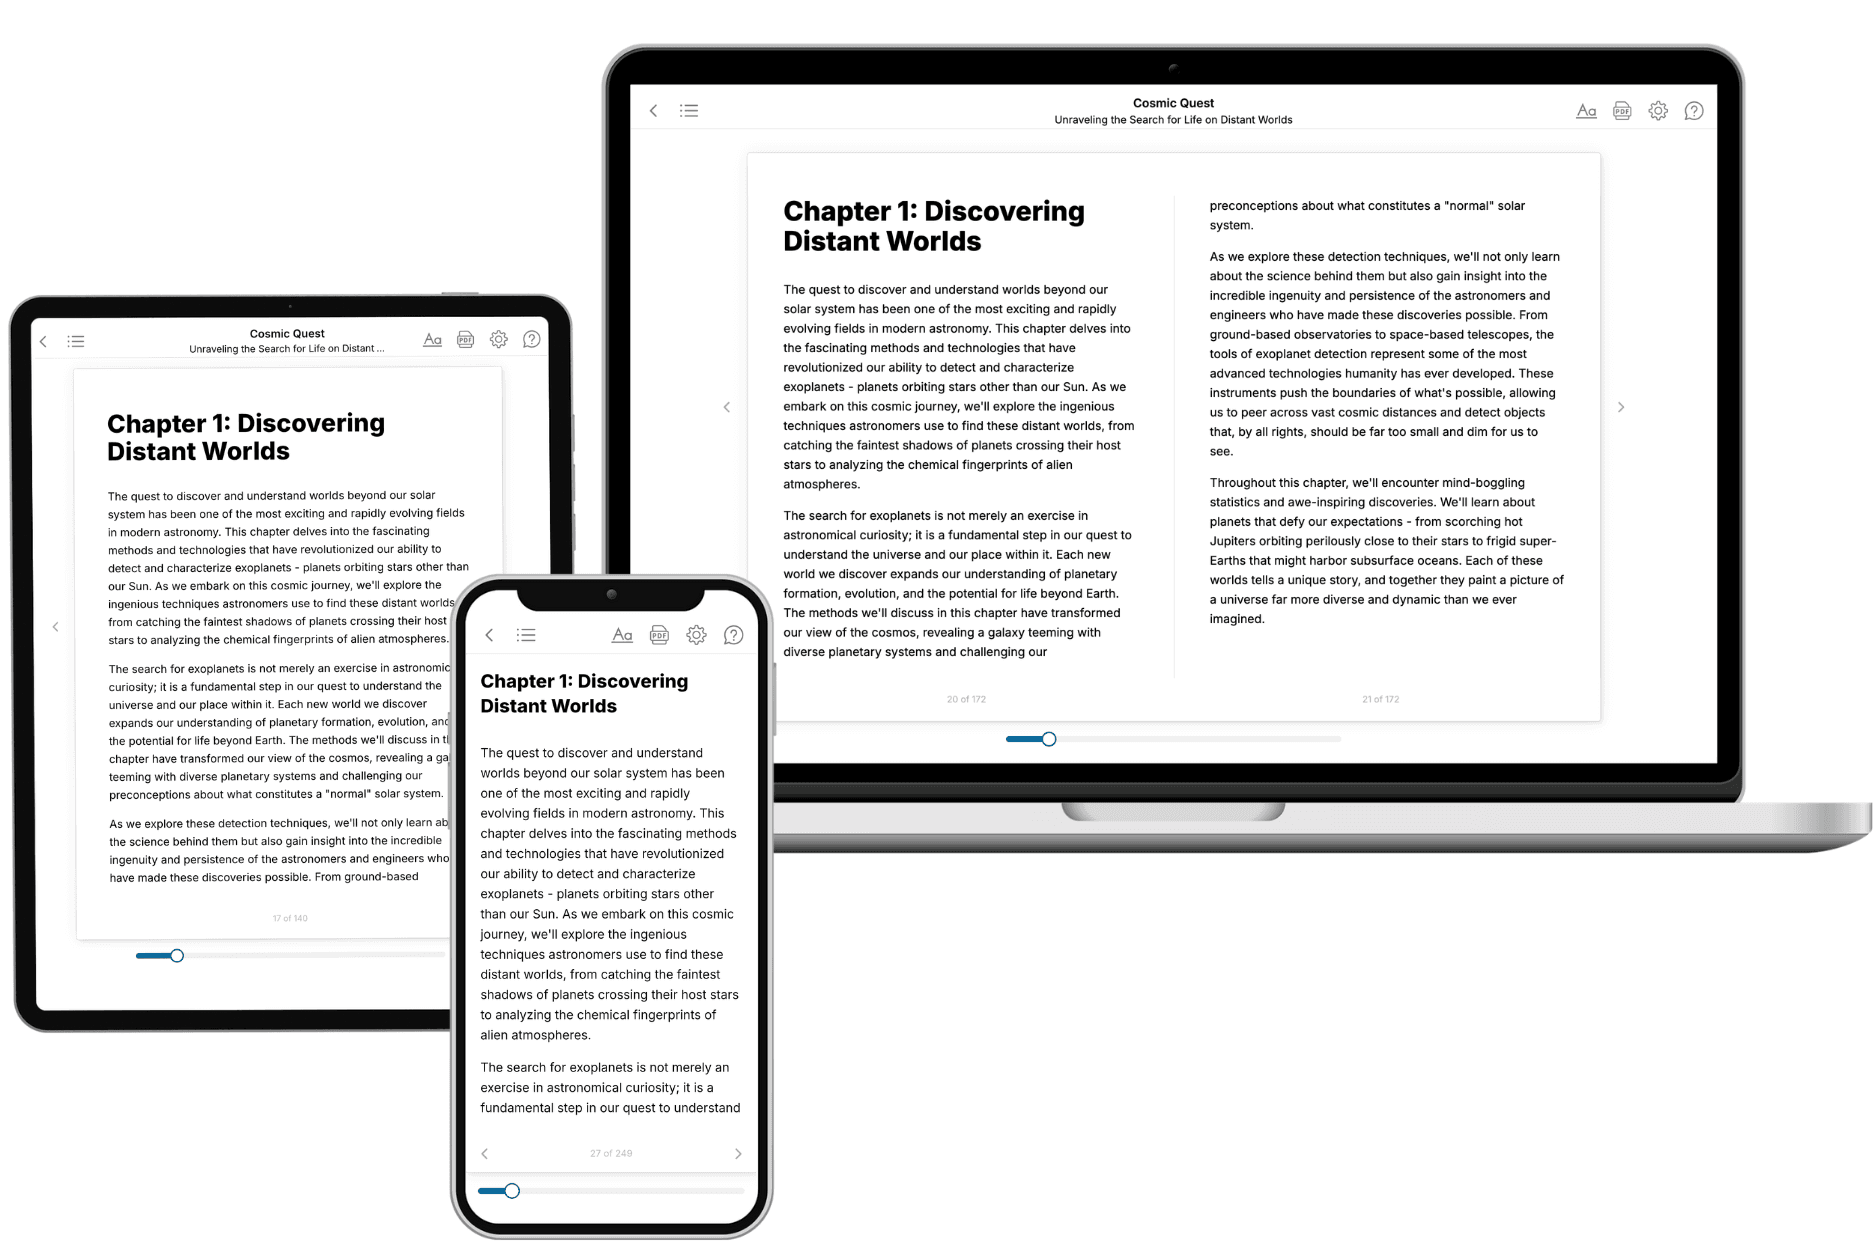
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.