CUDA Mastery
Advanced Techniques for High-Performance GPU Computing
GPU bottlenecks are holding back your most ambitious projects.
300 pages15 chaptersApr 30, 2025Software DevelopmentCreated by Ishan
About this book
You've conquered the basics of CUDA, but now you're facing complex challenges that demand advanced solutions. "CUDA Mastery" is your comprehensive guide to breaking through these barriers and unleashing the full potential of GPU computing. This book dives deep into cutting-edge CUDA techniques, offering practical strategies for optimizing memory management, maximizing parallel execution, and fine-tuning performance across diverse applications. You'll explore advanced topics such as dynamic parallelism, CUDA graphs, and tensor cores, gaining insights that will revolutionize your approach to GPU programming. From optimizing AI model performance to accelerating scientific simulations, "CUDA Mastery" equips you with the tools to tackle the most demanding computational tasks. You'll learn how to develop custom kernels, implement efficient GPU libraries, and master the art of CUDA profiling and debugging.
Table of contents
- IntroductionThe Evolution of CUDA and GPU Computing, Overview of Advanced CUDA Techniques, Prerequisites and How to Use This Book, Developing a Performance-Oriented MindsetRead below
- Chapter 1: Mastering CUDA Thread HierarchyThread Blocks and Grids Revisited, Warp-Level Execution Model, Advanced Thread Synchronization Techniques, Harnessing Cooperative Groups
- Chapter 2: Advanced Memory Optimization StrategiesMaximizing Shared Memory Usage, Perfecting Memory Coalescing, Identifying and Resolving Bank Conflicts, Leveraging Texture Memory for Performance
- Chapter 3: Advanced Parallel Programming PatternsOptimized Reduction Techniques, Efficient Scan and Prefix Sum Algorithms, High-Performance Stencil Computations, Sparse Matrix Operations on GPUs
- Chapter 4: Harnessing Dynamic ParallelismDesigning Dynamic Kernel Launches, Implementing Recursive Algorithms on GPUs, Dynamic Load Balancing Strategies, Understanding Limitations and Overhead
- Chapter 5: Mastering Streams and Asynchronous ExecutionDeep Dive into CUDA Streams, Asynchronous Memory Operations, Concurrent Kernel Execution, Stream Priorities and Scheduling
- Chapter 6: Advanced Memory Management TechniquesUnified Memory: Beyond the Basics, Managed Memory and Oversubscription, Optimizing Pinned Memory Usage, Implementing Custom Memory Pools
- Chapter 7: Kernel Optimization TechniquesInstruction-Level Parallelism, Minimizing Warp Divergence, Fine-tuning Occupancy, Kernel Fusion Strategies
- Chapter 8: Leveraging CUDA Libraries for PerformancecuBLAS Optimization Techniques, Efficient Sparse Computations with cuSPARSE, Maximizing cuFFT Performance, Boosting Productivity with Thrust
- Chapter 9: Optimizing Workflows with CUDA GraphsCreating and Launching CUDA Graphs, Updating and Reusing Graphs, Integrating Graphs with Streams, Performance Implications of Graph Usage
- Chapter 10: Scaling to Multi-GPU SystemsPeer-to-Peer Access and Transfer, CUDA-Aware MPI for Distributed Computing, Exploring NVSHMEM for GPU Communication, Synchronization in Multi-GPU Environments
- Chapter 11: Accelerating AI and Deep LearningHarnessing Tensor Cores for AI Workloads, Mixed Precision Training Techniques, Optimizing cuDNN for Deep Learning, Efficient AI Inference on GPUs
- Chapter 12: Exploring Advanced CUDA FeaturesImplementing Persistent Threads, Warp Shuffle Instructions, Just-in-Time Compilation with NVRTC, GPUDirect for Optimized I/O
- Chapter 13: Advanced Profiling and DebuggingDeep Dive into Nsight Compute, Advanced NVPROF Analysis, Leveraging CUDA-memcheck and Sanitizers, Implementing Custom Profiling Solutions
- Chapter 14: Real-world Optimization Case StudiesOptimizing an End-to-End ML Pipeline, Accelerating a Complex Scientific Simulation, Enhancing Real-time Rendering Performance, Scaling Big Data Processing on GPUs
- Chapter 15: Future Trends in GPU ComputingPreparing for Next-Generation GPU Hardware, The Evolution of CUDA and GPU Programming Models, The Convergence of AI and HPC, GPUs in the Age of Quantum Computing
- Conclusion
- Glossary
- Further Reading
Introduction
Welcome to "CUDA Mastery: Advanced Techniques for High-Performance GPU Computing." This book is designed to take your GPU programming skills to the next level, providing you with the advanced knowledge and techniques needed to push the boundaries of parallel computing. As a highly experienced computer scientist and CEO with a strong foundation in GPU computing, you're already aware of the transformative power of CUDA. Now, it's time to delve deeper into the intricacies of this technology and unlock its full potential for your cutting-edge applications in AI, scientific simulations, and high-performance computing.
In this introduction, we'll set the stage for your journey into advanced CUDA programming. We'll explore the evolution of CUDA and GPU computing, provide an overview of the advanced techniques you'll master throughout this book, discuss the prerequisites for making the most of this material, and help you develop a performance-oriented mindset that's crucial for success in high-performance computing. By the end of this chapter, you'll have a clear roadmap for your learning journey and be primed to tackle the complex challenges that lie ahead.
The Evolution of CUDA and GPU Computing
The landscape of high-performance computing has been dramatically reshaped by the advent of GPU computing and CUDA. What began as a specialized tool for graphics rendering has evolved into a powerhouse for general-purpose parallel computing, revolutionizing fields from artificial intelligence to scientific simulations. To appreciate the significance of the advanced techniques you'll learn in this book, it's essential to understand the journey that brought us here.
The concept of using graphics processing units for non-graphical computations, known as GPGPU (General-Purpose computing on Graphics Processing Units), emerged in the early 2000s. However, it wasn't until NVIDIA introduced CUDA (Compute Unified Device Architecture) in 2006 that GPU computing truly began to realize its potential. CUDA provided a more accessible and flexible programming model for harnessing the massive parallelism of GPUs, opening up new possibilities for accelerating a wide range of computational tasks.
Since its inception, CUDA has undergone significant evolution. Early versions focused on providing basic access to GPU resources, with subsequent releases introducing more sophisticated features and optimizations. The introduction of unified memory in CUDA 6.0 (2013) marked a significant milestone, simplifying memory management and improving programmer productivity. Dynamic parallelism, introduced in CUDA 5.0 for Kepler architecture GPUs, allowed for more complex and adaptive parallel algorithms. Recent versions have brought advancements like cooperative groups, CUDA graphs, and improved support for AI and deep learning workloads.
Alongside CUDA's software evolution, GPU hardware has made remarkable strides. From the early days of the Tesla architecture to the current Ampere and Hopper generations, GPUs have seen exponential increases in computational power, memory bandwidth, and energy efficiency. Specialized hardware features like tensor cores have been introduced to accelerate specific workloads, particularly in the realm of AI and machine learning. The latest GPUs can perform mixed-precision operations, offering a balance between accuracy and performance that's crucial for many advanced applications.
This co-evolution of hardware and software has led to GPU computing becoming an indispensable tool in numerous fields. In scientific computing, GPUs have enabled simulations of unprecedented scale and complexity, from climate modeling to molecular dynamics. The AI revolution, particularly the deep learning boom, has been largely powered by GPU acceleration. In data analytics, GPUs are processing massive datasets at speeds that were once unimaginable. Even traditional high-performance computing domains like financial modeling and cryptography have been transformed by the adoption of GPU computing.
As a seasoned computer scientist, you've likely witnessed and perhaps contributed to this evolution. The techniques and strategies you'll learn in this book are the culmination of years of research, development, and real-world application by the GPU computing community. They represent the current state of the art in CUDA programming, enabling you to leverage the full capabilities of modern GPUs.
However, it's important to recognize that the field of GPU computing continues to evolve rapidly. The techniques you'll master here are not the end of the journey, but rather a solid foundation for staying at the forefront of this dynamic field. As new GPU architectures emerge and CUDA continues to evolve, the principles and advanced concepts you'll learn will serve as a springboard for adapting to and leveraging future innovations.
Throughout this book, we'll frequently reference this evolutionary context. Understanding where certain techniques came from, why they were developed, and how they've been refined over time will give you a deeper appreciation for their significance and help you apply them more effectively in your own work. Moreover, this historical perspective will enhance your ability to anticipate and adapt to future developments in GPU computing.
As we delve into advanced CUDA techniques, keep in mind that you're not just learning a set of static skills, but becoming part of an ongoing revolution in computing. The knowledge you gain here will empower you to push the boundaries of what's possible with GPU computing, potentially contributing to the next wave of innovations in this exciting field.
Overview of Advanced CUDA Techniques
"CUDA Mastery" is designed to take you on a comprehensive journey through the most advanced aspects of CUDA programming. This book isn't just about learning individual techniques; it's about developing a deep understanding of how to leverage the full power of modern GPUs to solve complex computational problems. Let's take a high-level tour of the advanced techniques and concepts you'll master in the coming chapters.
We'll begin by diving deep into the CUDA thread hierarchy, exploring advanced concepts like warp-level execution and cooperative groups. Understanding these fundamental building blocks at an advanced level is crucial for writing highly optimized CUDA code. You'll learn how to fine-tune your thread organization to maximize parallelism and efficiency, and how to leverage warp-level primitives for even greater performance.
Memory optimization is a critical aspect of high-performance GPU computing, and we'll cover advanced strategies in detail. You'll learn how to make the most of shared memory, perfect your memory coalescing techniques, and resolve bank conflicts that can significantly impact performance. We'll also explore advanced uses of texture memory and other specialized memory types to accelerate specific types of computations.
The book will then guide you through advanced parallel programming patterns that go beyond basic parallelization. You'll master optimized reduction techniques, efficient scan and prefix sum algorithms, and high-performance stencil computations. These patterns form the backbone of many complex GPU algorithms and understanding them at a deep level will significantly enhance your ability to design efficient CUDA solutions.
Dynamic parallelism is a powerful feature that allows for more flexible and adaptive GPU algorithms. We'll explore how to design dynamic kernel launches, implement recursive algorithms on GPUs, and develop dynamic load balancing strategies. You'll also gain a nuanced understanding of the limitations and potential overhead of dynamic parallelism, enabling you to make informed decisions about when and how to use this feature.
Asynchronous execution and CUDA streams are essential tools for maximizing GPU utilization, especially in complex applications. You'll learn advanced techniques for managing multiple streams, optimizing asynchronous memory operations, and achieving true concurrency in your GPU workloads. We'll also cover stream priorities and scheduling to give you fine-grained control over execution order.
Advanced memory management techniques will be a key focus, including a deep dive into unified memory, managed memory oversubscription, and optimized use of pinned memory. You'll also learn how to implement custom memory pools for maximum efficiency in memory-intensive applications.
Kernel optimization is where the rubber meets the road in CUDA programming. We'll explore instruction-level parallelism, techniques for minimizing warp divergence, and strategies for fine-tuning occupancy. You'll also learn advanced kernel fusion techniques to minimize launch overhead and maximize data reuse.
Leveraging CUDA libraries effectively is crucial for many high-performance applications. We'll cover advanced usage of libraries like cuBLAS, cuSPARSE, cuFFT, and Thrust, showing you how to squeeze every ounce of performance out of these optimized tools.
CUDA Graphs represent a paradigm shift in how complex GPU workloads can be organized and executed. You'll learn how to create, update, and optimize CUDA Graphs to streamline your workflows and achieve unprecedented levels of performance for complex, multi-kernel applications.
As you scale your applications to multi-GPU systems, new challenges and opportunities arise. We'll explore advanced techniques for multi-GPU programming, including peer-to-peer access, CUDA-aware MPI for distributed computing, and the cutting-edge NVSHMEM library for GPU communication.
Given the increasing convergence of HPC and AI, we'll dedicate significant attention to accelerating AI and deep learning workloads. You'll learn how to harness tensor cores, implement mixed-precision training techniques, and optimize deep learning frameworks for maximum performance.
We'll also explore a range of advanced CUDA features, including persistent threads, warp shuffle instructions, just-in-time compilation with NVRTC, and GPUDirect for optimized I/O. These techniques will give you a toolkit for tackling some of the most challenging problems in GPU computing.
Profiling and debugging are essential skills for any advanced CUDA programmer. You'll gain expertise in using advanced tools like Nsight Compute and NVPROF, and learn how to implement custom profiling solutions for your specific needs.
To tie everything together, we'll examine real-world optimization case studies, applying the advanced techniques you've learned to complex, practical problems. These case studies will cover a range of domains, from machine learning pipelines to scientific simulations and big data processing.
Finally, we'll look towards the future of GPU computing, exploring emerging trends and preparing you to adapt to next-generation GPU hardware and programming models.
By the end of this book, you'll have a comprehensive understanding of advanced CUDA techniques, enabling you to develop cutting-edge GPU-accelerated applications that push the boundaries of performance and capability. This knowledge will empower you to tackle the most demanding computational challenges in your field, whether you're developing AI systems, running complex scientific simulations, or pushing the limits of high-performance computing in other domains.
Prerequisites and How to Use This Book
Before diving into the advanced techniques covered in this book, it's important to ensure you have the necessary foundation. As an experienced computer scientist and CEO with advanced knowledge in GPU computing, you likely already possess much of this background. However, let's review the key prerequisites to help you make the most of the material presented in "CUDA Mastery."
First and foremost, a solid understanding of C++ programming is essential. CUDA is an extension of C++, and many advanced techniques leverage C++ features. You should be comfortable with concepts such as templates, lambda functions, and the C++ Standard Library. If you need a refresher, consider reviewing a comprehensive C++ resource before proceeding.
A strong grasp of parallel computing concepts is also crucial. You should be familiar with parallel algorithms, synchronization primitives, and common parallel programming patterns. Understanding the challenges of parallel computing, such as race conditions and load balancing, will be important for appreciating the advanced techniques presented in this book.
Familiarity with the basics of CUDA programming is a must. You should be comfortable with concepts such as kernel launches, thread blocks and grids, shared memory usage, and basic memory management in CUDA. If you need to brush up on these fundamentals, NVIDIA's official CUDA documentation and introductory tutorials are excellent resources.
A basic understanding of computer architecture, particularly as it relates to GPUs, will be helpful. Familiarity with concepts like memory hierarchy, SIMD (Single Instruction, Multiple Data) execution, and basic performance optimization principles will provide valuable context for the advanced techniques we'll explore.
Some knowledge of linear algebra and numerical methods can be beneficial, especially for chapters dealing with scientific computing and AI acceleration. While not strictly necessary for understanding the CUDA techniques themselves, this mathematical background will help you appreciate the applications and optimizations discussed.
To make the most of this book, you'll need access to a CUDA-capable GPU and the CUDA toolkit installed on your development machine. While the concepts can be understood without hands-on practice, implementing and experimenting with the techniques yourself will significantly enhance your learning experience.
As for how to use this book, it's designed to be both a comprehensive guide and a reference resource. While the chapters build on each other to some extent, each also stands alone as a deep dive into a particular aspect of advanced CUDA programming. Here are some suggestions for getting the most out of your reading:
1. Start with a full read-through to get a comprehensive overview of advanced CUDA techniques. This will help you understand how different concepts interrelate and give you a broad perspective on high-performance GPU computing.
2. As you read, make note of techniques that are particularly relevant to your current projects or areas of interest. You can then revisit these sections for more in-depth study and implementation.
3. Don't just read – implement. The code examples and case studies provided are meant to be starting points for your own experimentation. Try to adapt the techniques to your own problems and see how they perform.
4. Use the book as a reference. Once you've read through it, you'll likely find yourself returning to specific sections when tackling particular optimization challenges in your work.
5. Pay attention to the cross-references between chapters. Many advanced techniques build on or complement each other, and understanding these relationships will give you a more holistic view of CUDA optimization.
6. Take advantage of the further reading suggestions at the end of each chapter. These will point you towards additional resources for deepening your understanding of specific topics.
7. Remember that mastery comes with practice. The techniques in this book are advanced and may take time to fully grasp and apply effectively. Be patient with yourself and persistent in your learning.
8. Stay curious and keep exploring. The field of GPU computing is rapidly evolving, and while this book covers the current state of the art, new techniques and best practices are always emerging. Use the knowledge gained here as a foundation for continued learning and experimentation.
By approaching this book with a combination of systematic study and hands-on experimentation, you'll be well-equipped to master advanced CUDA techniques and apply them to push the boundaries of what's possible in your GPU computing projects. Remember, the goal is not just to understand these techniques in isolation, but to develop the skills to combine and adapt them creatively to solve complex, real-world problems.
Developing a Performance-Oriented Mindset
As you embark on your journey to master advanced CUDA techniques, it's crucial to cultivate a performance-oriented mindset. This way of thinking goes beyond simply learning and applying optimization techniques; it involves developing an intuition for performance, a systematic approach to problem-solving, and a commitment to continuous improvement. Let's explore the key aspects of this mindset and how you can develop it.
First and foremost, adopt a data-driven approach to performance optimization. In the world of high-performance computing, intuition can be misleading, and what seems like a logical optimization might not always yield the expected results. Always measure performance before and after applying optimizations. Use profiling tools extensively to understand where your code spends time and resources. Make decisions based on empirical evidence rather than assumptions.
Develop a holistic view of performance. While it's important to optimize individual kernels, true mastery comes from understanding how all components of your application interact. Consider the entire pipeline of your application, including data transfer, kernel execution, and host-side operations. Sometimes, the most significant performance gains come from restructuring your application's overall flow rather than micro-optimizing a single kernel.
Cultivate curiosity about the underlying hardware. Advanced CUDA programming requires a deep understanding of GPU architecture. Stay curious about how different GPU features work, from memory hierarchies to warp execution. When you encounter unexpected performance behavior, dig deep to understand the hardware-level reasons behind it. This curiosity will not only help you optimize current code but also prepare you for future GPU architectures.
Embrace the concept of trade-offs. In high-performance computing, there's rarely a one-size-fits-all solution. Every optimization comes with trade-offs, whether in terms of memory usage, code complexity, or portability. Develop the ability to analyze these trade-offs and make informed decisions based on your specific requirements and constraints.
Adopt an iterative approach to optimization. Don't expect to achieve peak performance in one go. Start with a working solution, profile it, identify the most significant bottlenecks, apply optimizations, and then repeat the process. This iterative approach allows you to make steady progress and avoid premature optimization of less critical code sections.
Cultivate a deep understanding of parallel algorithms. Many performance problems in CUDA programming stem from suboptimal algorithmic choices. Invest time in studying parallel algorithms and data structures. Understanding how to reformulate problems to better suit parallel execution is often more valuable than low-level code optimizations.
Develop a keen awareness of memory operations. In GPU computing, memory access patterns and data movement often have the most significant impact on performance. Train yourself to always be aware of where data is located, how it's being accessed, and how it moves between different memory spaces. This awareness will guide you towards more efficient memory usage patterns.
Stay updated with the latest developments. The field of GPU computing is rapidly evolving. New hardware features, software optimizations, and best practices emerge regularly. Make it a habit to stay informed about the latest CUDA releases, GPU architectures, and research in high-performance computing. This ongoing learning will help you continually refine your optimization strategies.
Practice thinking at multiple levels of abstraction. Advanced CUDA programming often requires you to think both at a high level (overall application structure and algorithms) and at a low level (warp-level operations, memory access patterns). Develop the ability to switch between these levels of abstraction fluidly, understanding how high-level decisions impact low-level performance and vice versa.
Foster a collaborative mindset. Some of the most challenging performance problems are solved through collaboration. Engage with the CUDA and GPU computing community, share your experiences, and learn from others. Participate in forums, attend conferences, and contribute to open-source projects. This collaborative approach will expose you to diverse perspectives and solutions.
Develop patience and persistence. Achieving optimal performance often requires meticulous work and can be frustrating at times. Cultivate the patience to methodically work through complex performance issues and the persistence to keep pushing for better solutions even when progress seems slow.
Learn to balance performance with other software qualities. While performance is crucial, it shouldn't come at the expense of code readability, maintainability, or correctness. Develop the judgment to know when to prioritize raw performance and when other factors should take precedence.
Finally, cultivate a mindset of continuous improvement. No matter how optimized your code is, there's always potential for further enhancement. Whether it's through algorithmic improvements, better utilization of new hardware features, or more efficient coding practices, maintain a drive to continually refine and improve your CUDA code.
By developing this performance-oriented mindset, you'll not only be better equipped to apply the advanced techniques covered in this book but also to innovate and develop novel optimizations of your own. Remember, mastering CUDA is not just about knowing a set of techniques; it's about developing the intuition, skills, and approach to tackle any high-performance computing challenge effectively.
As you progress through "CUDA Mastery," keep this mindset at the forefront. Apply it to the techniques you learn, the problems you solve, and the code you write. With time and practice, this performance-oriented approach will become second nature, enabling you to push the boundaries of what's possible in GPU computing and drive innovation in your field.
This is the end of the free sample. The full book has 15 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Software Development knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Software Development book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Software Development book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
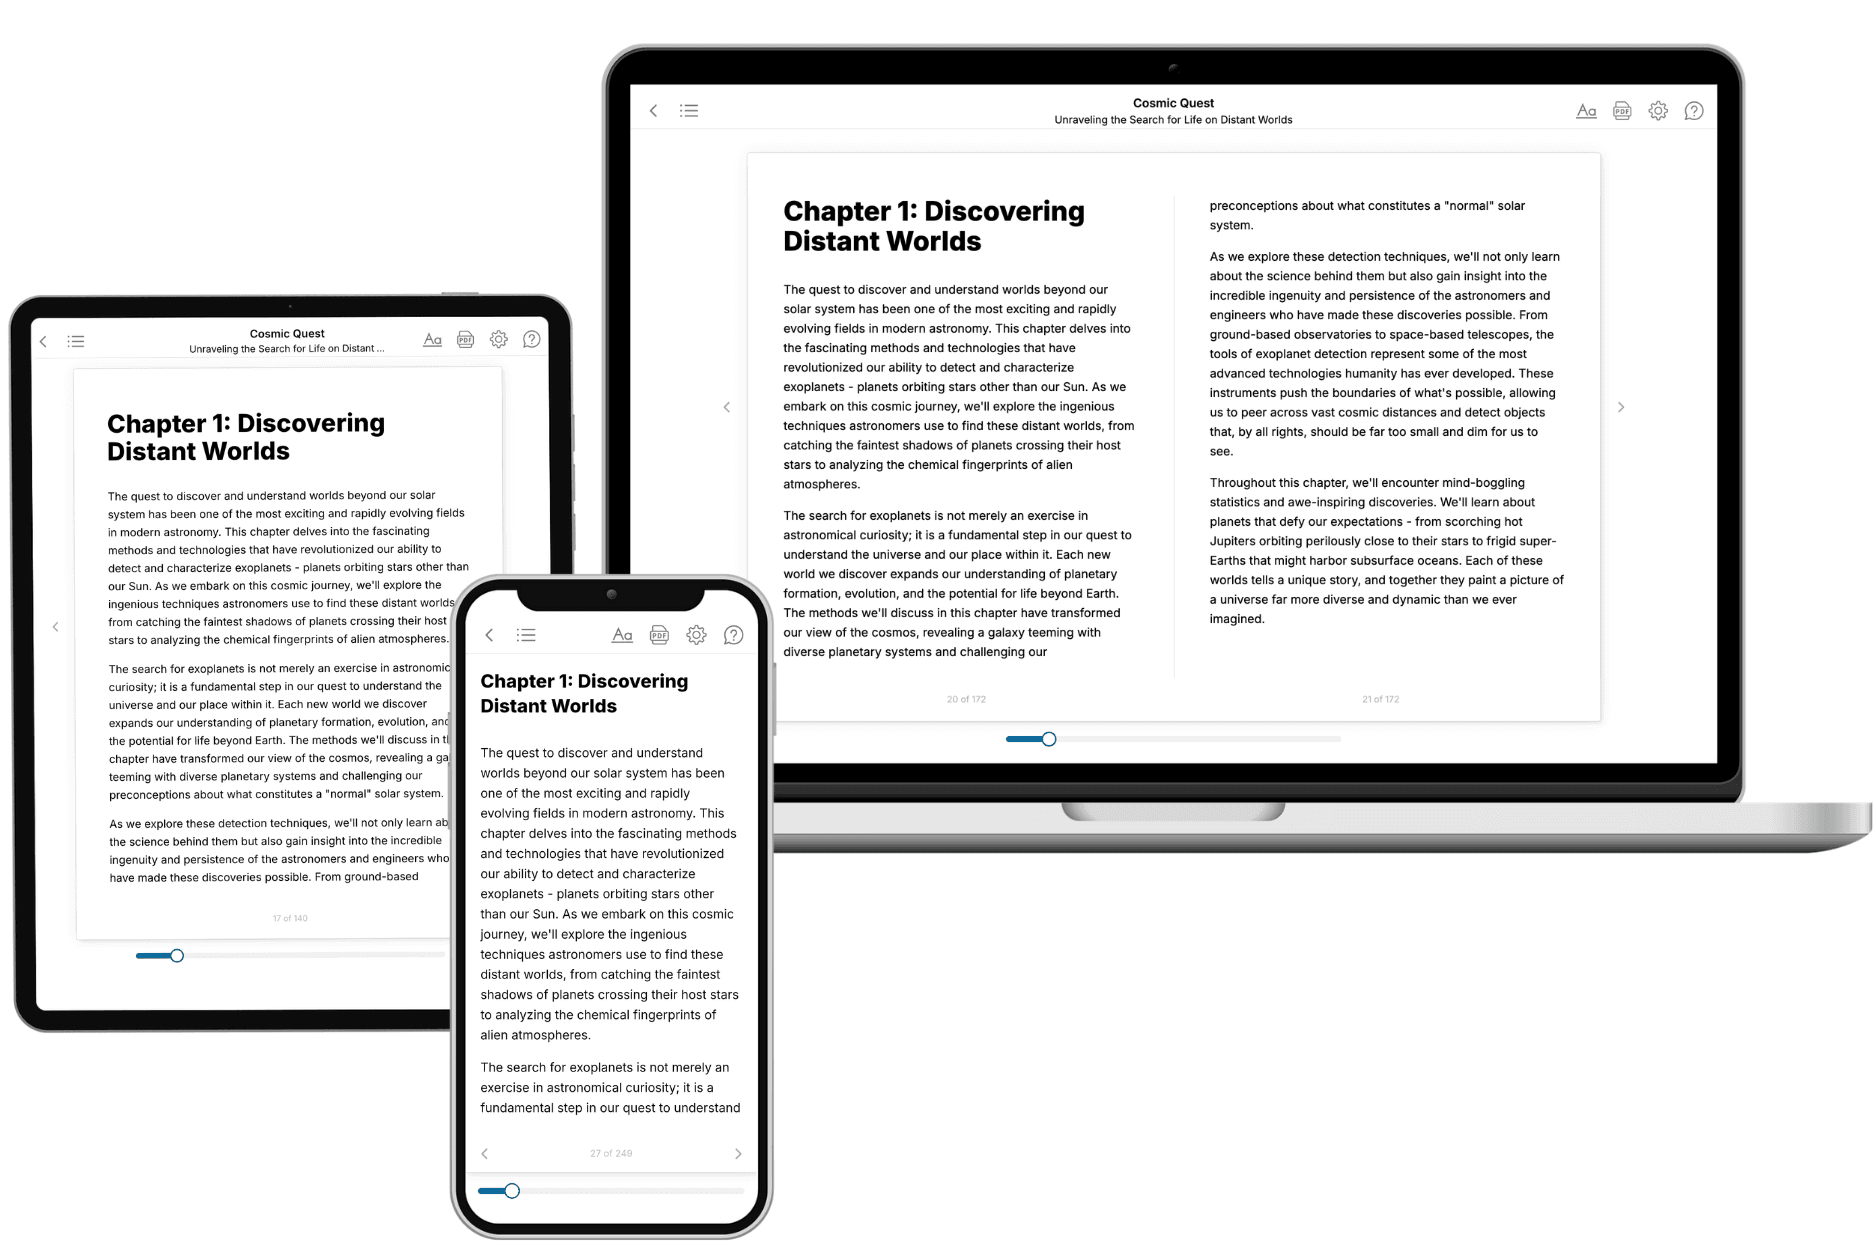
- 3. Get your tailored book
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.