Embeddings Mastery Blueprint
Personalized Strategies for Expert-Level Understanding of Vector Representations and Their Applications
Most developers think embeddings are just fancy vectors you plug into a model and hope for the best.
176 pages10 chaptersOct 23, 2025AI and Machine Learning
About this book
This misconception leads to suboptimal performance, wasted computational resources, and frustration when similarity systems fail to deliver meaningful results. The truth is that embeddings are sophisticated mathematical constructs that require strategic thinking, careful evaluation, and domain-specific optimization to reach their full potential. This book provides you with a comprehensive blueprint for mastering embeddings at an expert level. You'll move beyond surface-level understanding to grasp the mathematical foundations, learn how to evaluate and optimize embedding quality, and discover how to adapt embeddings to your specific domain. From building efficient similarity matching systems using Approximate Nearest Neighbor algorithms to creating cross-lingual embeddings that work across languages, you'll gain practical strategies that translate directly into production-ready solutions. Whether you're building recommendation engines, semantic search systems, or knowledge graphs, this personalized guide gives you the tools and techniques to make embeddings work effectively for your applications.
Table of contents
- IntroductionThe Embeddings Revolution in Modern Systems, Your Personalized Learning Path, A Practical Approach to MasteryRead below
- Chapter 1: Embedding FundamentalsUnderstanding Vector Space Representations, Mathematical Foundations of Embeddings, Types of Embeddings and Their Use Cases
- Chapter 2: Semantic Embeddings and Meaning CapturePrinciples of Semantic Representation, Encoding Context and Relationships, Modern Semantic Embedding Models
- Chapter 3: Distance Metrics and Similarity MeasuresEuclidean Distance and Vector Norms, Cosine Similarity and Other Distance Functions, Choosing the Right Metric for Your Application
- Chapter 4: Graph Embeddings and Relational StructuresGraph Representation Learning Fundamentals, Node Embeddings and Network Analysis, Practical Applications of Graph Embeddings
- Chapter 5: Cross-Lingual EmbeddingsCreating Shared Multilingual Vector Spaces, Alignment Techniques Across Languages, Building Multilingual Applications
- Chapter 6: Embedding Evaluation and Quality AssessmentKey Evaluation Metrics and Benchmarks, Intrinsic Evaluation Methods, Extrinsic Evaluation in Real Applications
- Chapter 7: Embedding Optimization and RegularizationCore Optimization Strategies, Embedding Regularization Techniques, Hyperparameter Tuning for Better Performance
- Chapter 8: Domain Adaptation StrategiesTransfer Learning for Embeddings, Creating Domain-Specific Embeddings, Fine-Tuning Techniques for Your Domain
- Chapter 9: Building Vector Similarity SystemsApproximate Nearest Neighbor Algorithms, Locality Sensitive Hashing Implementation, Scalable Similarity Search Architecture
- Chapter 10: Model Integration and Production DeploymentIntegration Patterns for Embedding Models, Production Deployment Considerations, Monitoring and Maintaining Embedding Systems
Introduction
Embeddings have transformed how machines understand and process information, yet many developers treat them as black boxes—mysterious mathematical objects that somehow make their models work better. This approach leaves enormous potential untapped. When you truly understand embeddings, you gain the ability to build systems that capture nuanced semantic relationships, search through billions of data points in milliseconds, and transfer knowledge across languages and domains. The difference between a developer who uses embeddings and one who masters them is the difference between following recipes and understanding the chemistry of cooking.
The journey from intermediate to expert-level understanding requires more than reading documentation or running tutorial code. You need to grasp the mathematical foundations that make embeddings work, develop intuition about when different techniques apply, and build practical experience with real-world challenges like evaluation, optimization, and scaling. This book provides that comprehensive path, designed specifically for developers with solid programming foundations who are ready to move beyond surface-level implementation. Every concept connects to practical applications, every technique includes concrete examples, and every chapter builds toward production-ready skills.
The landscape of embeddings extends far beyond simple word vectors. Modern applications demand sophisticated understanding of graph embeddings for social networks, cross-lingual representations for multilingual systems, and efficient similarity search algorithms that scale to production workloads. Domain adaptation techniques let you customize general-purpose embeddings for specialized fields, while regularization methods ensure your models generalize well to unseen data. This introduction sets the stage for your transformation from competent practitioner to embeddings expert, outlining the revolution these techniques have sparked and the personalized learning path that will take you there.
The Embeddings Revolution in Modern Systems
The fundamental challenge that embeddings solve is representation. Traditional systems treated words, images, and other data as discrete symbols with no inherent relationships. The word king
was just an identifier, completely separate from queen
or monarch
. Embeddings changed everything by representing data as points in continuous vector space, where semantic similarity translates to geometric proximity. This breakthrough enabled machines to understand that king
relates to queen
similarly to how man
relates to woman
, capturing relationships that discrete representations could never express. The implications ripple through every domain of modern computing, from search engines that understand intent to recommendation systems that predict preferences.
Consider how embeddings revolutionized natural language processing. Before embeddings, systems relied on sparse representations like one-hot encoding, where each word occupied a single dimension in a vocabulary-sized vector. A vocabulary of fifty thousand words required fifty thousand dimensions, with each word represented by a vector of all zeros except a single one. These representations were computationally expensive, statistically inefficient, and captured no semantic information. Modern embeddings compress this into dense vectors of perhaps three hundred dimensions, where every dimension contributes to meaning and similar concepts cluster together. This compression isn't just about efficiency—it fundamentally changes what's computationally possible.
The revolution extends beyond text into images, audio, graphs, and multimodal data. Image embeddings let you search photos by describing what you want to find, not just matching keywords. Audio embeddings enable speaker recognition and music recommendation based on acoustic similarity. Graph embeddings capture the structure of social networks, knowledge bases, and molecular interactions. Each domain presents unique challenges, but the underlying principle remains constant: transform discrete, high-dimensional data into continuous, dense representations that preserve meaningful relationships. This universality makes embeddings one of the most powerful tools in modern machine learning.
Production systems at major technology companies demonstrate the practical impact of embeddings at scale. Search engines use embeddings to understand query intent and match it with relevant documents, even when exact keywords don't appear. Recommendation systems embed users and items into shared spaces where proximity indicates preference. Fraud detection systems embed transaction patterns to identify anomalies. Translation services use cross-lingual embeddings to transfer knowledge between languages. These aren't experimental applications—they're core infrastructure handling billions of requests daily. The companies that master embeddings gain significant competitive advantages in user experience and system performance.
The mathematical elegance of embeddings enables operations that seem almost magical. Vector arithmetic captures semantic relationships: the vector for king
minus man
plus woman
yields a vector close to queen
. This isn't a trick or coincidence—it's a natural consequence of how embeddings encode relationships in geometric space. You can perform analogical reasoning, measure semantic similarity, cluster related concepts, and visualize high-dimensional relationships by projecting into two or three dimensions. These operations work because embeddings preserve the structure of the original data while making it computationally tractable.
However, the revolution comes with challenges that separate effective implementations from failed experiments. Poor quality embeddings produce meaningless results, wasting computational resources and developer time. Embeddings trained on biased data perpetuate and amplify those biases. Scaling similarity search to billions of vectors requires sophisticated algorithms and infrastructure. Adapting general-purpose embeddings to specialized domains demands careful strategy. Evaluating embedding quality isn't straightforward—what metrics matter depends on your application. These challenges explain why understanding embeddings deeply matters more than simply knowing how to call an API.
The current state of embeddings technology offers unprecedented opportunities for developers who invest in mastery. Pre-trained models provide excellent starting points, but customization separates good systems from great ones. Open-source libraries handle low-level implementation details, letting you focus on architecture and optimization. Cloud services offer scalable infrastructure for similarity search. Research continues to advance the field, with new techniques for efficiency, quality, and applicability emerging regularly. The barrier to entry has never been lower, but the ceiling for expertise remains high. This gap between basic usage and expert application is where significant value lies.
Understanding the embeddings revolution means recognizing both the power and the limitations of these techniques. Embeddings excel at capturing patterns in training data and generalizing to similar examples. They struggle with rare events, adversarial inputs, and concepts absent from training data. They compress information, which means some details get lost. They reflect the biases and limitations of their training data. Expert practitioners know when embeddings are the right tool and when alternative approaches work better. They understand the tradeoffs between different embedding techniques and can make informed decisions based on specific requirements. This nuanced understanding transforms embeddings from mysterious black boxes into powerful, controllable tools.
Your Personalized Learning Path
Your journey to embeddings mastery builds on your existing foundation as a mid-level developer with professional experience. You already understand programming fundamentals, data structures, and basic machine learning concepts. This book doesn't waste time on prerequisites you've already mastered. Instead, it focuses on the specific knowledge and skills that transform intermediate understanding into expert-level capability. The path is structured to build progressively, with each chapter introducing concepts that depend on previous material while remaining focused on practical application. You'll move from mathematical foundations through evaluation and optimization to production deployment, gaining both theoretical understanding and hands-on skills.
The learning path begins with embedding fundamentals, ensuring you have solid grounding in vector space representations and mathematical principles. You'll understand not just what embeddings are, but why they work and how different design choices affect their behavior. This foundation is critical because advanced techniques build on these basics. Without understanding vector norms, you can't effectively choose distance metrics. Without grasping dimensionality, you can't optimize embedding size. Without knowing how training objectives shape representations, you can't adapt embeddings to your domain. These fundamentals aren't abstract theory—they're practical knowledge that informs every decision you'll make when working with embeddings.
From fundamentals, you'll progress to semantic embeddings and meaning capture. This is where embeddings become truly powerful, moving beyond simple co-occurrence statistics to encode context, syntax, and conceptual relationships. You'll learn how modern models like transformers create contextualized embeddings where the same word has different representations depending on usage. You'll understand attention mechanisms that let models focus on relevant information. You'll see how pre-training on large corpora creates embeddings that transfer effectively to downstream tasks. These concepts directly impact the quality of systems you build, determining whether your similarity search returns relevant results or your classification model generalizes well.
Distance metrics and similarity measures form the next critical component of your learning path. Choosing the right metric for your application isn't arbitrary—it fundamentally affects what your system considers similar. Euclidean distance works well for some applications but fails for others. Cosine similarity handles different vector magnitudes gracefully but ignores absolute scale. Manhattan distance, Mahalanobis distance, and learned metrics each have appropriate use cases. You'll develop intuition about when each metric applies and how to evaluate whether your choice is working. This knowledge prevents common mistakes like using Euclidean distance on normalized embeddings or cosine similarity when magnitude matters.
Graph embeddings extend your capabilities to relational data structures. Social networks, knowledge graphs, citation networks, and molecular structures all benefit from embeddings that capture not just node properties but also network topology. You'll learn techniques like node2vec, DeepWalk, and graph neural networks that create embeddings preserving both local and global structure. These methods open possibilities for link prediction, community detection, and graph classification. The applications span recommendation systems, drug discovery, fraud detection, and knowledge base completion. Understanding graph embeddings significantly expands the types of problems you can solve with embedding techniques.
Cross-lingual embeddings address the challenge of working with multiple languages. Rather than building separate systems for each language, you'll learn to create shared vector spaces where semantically similar concepts cluster together regardless of language. This enables zero-shot transfer, where models trained on high-resource languages work on low-resource languages without additional training data. You'll understand alignment techniques that map monolingual spaces into shared multilingual spaces. You'll see how to evaluate cross-lingual quality and handle language-specific phenomena. These skills are increasingly valuable as applications serve global audiences and need to work across language boundaries.
Evaluation and quality assessment receive dedicated attention because you can't improve what you can't measure. You'll learn both intrinsic metrics that evaluate embeddings directly and extrinsic metrics that measure performance on downstream tasks. You'll understand when each type of evaluation is appropriate and how to interpret results. You'll see common pitfalls like overfitting to specific benchmarks or using metrics that don't align with application goals. You'll develop systematic approaches to diagnosing embedding quality issues and identifying improvement opportunities. This evaluation expertise is what separates developers who iterate blindly from those who make targeted, effective improvements.
Optimization and regularization techniques give you tools to improve embedding quality and prevent overfitting. You'll learn strategies for choosing learning rates, batch sizes, and training duration. You'll understand regularization methods like dropout, weight decay, and adversarial training that improve generalization. You'll see how to balance multiple training objectives and handle class imbalance. You'll develop intuition about when embeddings are undertrained, overtrained, or suffering from optimization issues. These skills let you extract maximum value from your training data and computational resources, creating embeddings that perform well on real-world data, not just training sets.
Domain adaptation strategies address the common scenario where general-purpose embeddings don't quite fit your specific application. You'll learn transfer learning techniques that start with pre-trained embeddings and adapt them to your domain. You'll understand when to freeze layers versus fine-tune them, how much domain-specific data you need, and how to avoid catastrophic forgetting. You'll see examples from medical text, legal documents, scientific literature, and other specialized domains. These techniques dramatically reduce the data and computation required to achieve good performance in specialized applications, making embeddings practical even when you don't have massive datasets.
The learning path culminates in building production-ready similarity systems. You'll master Approximate Nearest Neighbor algorithms like HNSW, IVF, and LSH that make similarity search practical at scale. You'll understand the tradeoffs between accuracy, speed, and memory usage. You'll learn to implement Locality Sensitive Hashing for efficient similarity detection. You'll see how to architect scalable systems that handle billions of vectors and thousands of queries per second. You'll understand monitoring, maintenance, and continuous improvement of deployed systems. These practical skills transform theoretical knowledge into production capabilities that deliver business value.
A Practical Approach to Mastery
This book takes a deliberately practical approach to embeddings mastery, balancing theoretical understanding with hands-on application. Every concept includes concrete examples showing how it works in practice. Every technique includes implementation guidance with specific steps you can follow. Every chapter addresses common challenges and provides troubleshooting advice. The goal isn't just to explain embeddings but to give you the tools and confidence to build production systems that leverage them effectively. Theory matters, but only insofar as it informs practical decisions and improves real-world outcomes.
The practical approach manifests in several ways throughout the book. First, examples use realistic scenarios drawn from actual applications rather than toy datasets. You'll see how embeddings work for product recommendations with millions of items, document search across diverse corpora, and social network analysis with complex relationship patterns. Second, code examples demonstrate implementation patterns you can adapt to your projects. While the book doesn't include complete applications, it provides the building blocks and architectural patterns you need. Third, each chapter includes specific metrics and evaluation criteria so you can assess whether techniques are working for your use case.
The book emphasizes decision-making frameworks over prescriptive rules. Embeddings involve numerous choices: dimensionality, training objectives, distance metrics, optimization strategies, and more. Rather than claiming one approach is always best, you'll learn how to evaluate tradeoffs and make informed decisions based on your specific requirements. For example, when choosing embedding dimensionality, you'll understand the tradeoffs between expressiveness, computational cost, and overfitting risk. You'll learn to run experiments that reveal which choice works best for your data and application. This decision-making capability is what enables expert-level practice.
Common pitfalls and failure modes receive explicit attention throughout the book. You'll learn what goes wrong when embeddings are poorly trained, inappropriately applied, or inadequately evaluated. You'll see examples of systems that failed and understand why. You'll develop intuition about warning signs that indicate problems. This knowledge helps you avoid costly mistakes and debug issues when they arise. For instance, you'll learn to recognize when poor performance stems from inadequate training data versus inappropriate architecture versus suboptimal hyperparameters. Each cause requires different solutions, and expert practitioners diagnose accurately.
The practical approach includes specific implementation guidance for popular tools and libraries. You'll see examples using frameworks like TensorFlow, PyTorch, and Hugging Face Transformers. You'll learn about specialized libraries for similarity search like FAISS, Annoy, and ScaNN. You'll understand when to use managed services versus building custom solutions. However, the focus remains on concepts and patterns that transcend specific tools. Technologies change rapidly, but fundamental principles endure. By understanding both the concepts and current implementations, you'll be prepared to adapt as the ecosystem evolves.
Performance optimization receives practical treatment with specific techniques you can apply. You'll learn how to profile embedding systems to identify bottlenecks. You'll see strategies for reducing memory usage, accelerating training, and speeding up inference. You'll understand when to use techniques like quantization, pruning, and knowledge distillation. You'll learn to balance accuracy against computational constraints. These optimization skills are critical for production systems where performance directly impacts user experience and operational costs. The difference between a system that works in development and one that scales in production often comes down to these optimization techniques.
The book addresses the full lifecycle of embedding systems, not just initial development. You'll learn how to monitor embedding quality in production, detect when retraining is needed, and manage model updates without disrupting service. You'll understand A/B testing strategies for evaluating embedding improvements. You'll see how to handle edge cases and gracefully degrade when embeddings fail. You'll learn to build systems that improve over time as you collect more data and refine your approach. This lifecycle perspective ensures your systems remain effective long after initial deployment.
Real-world constraints shape the practical approach throughout the book. You'll learn to work with limited training data, computational budgets, and time constraints. You'll see strategies for achieving good results without massive datasets or expensive infrastructure. You'll understand when simple approaches suffice and when sophisticated techniques justify their complexity. You'll learn to make pragmatic tradeoffs that deliver value within real-world constraints. This practical wisdom distinguishes developers who ship effective systems from those who pursue theoretical perfection that never reaches production.
The book's structure supports multiple learning styles and use cases. You can read sequentially for comprehensive understanding or jump to specific chapters addressing immediate needs. Each chapter stands relatively independently while building on foundational concepts from earlier material. Code examples and implementation details let hands-on learners experiment as they read. Conceptual explanations and decision frameworks support those who prefer understanding principles before implementation. References and footnotes point to additional resources for deeper exploration. This flexibility ensures the book serves as both initial learning resource and ongoing reference.
Ultimately, the practical approach aims to transform you from someone who uses embeddings into someone who masters them. You'll develop intuition about when embeddings are appropriate and when alternatives work better. You'll gain confidence in your ability to evaluate embedding quality, diagnose problems, and implement improvements. You'll understand the tradeoffs involved in different design choices and make informed decisions. You'll be able to explain embeddings to colleagues, evaluate vendor claims, and architect systems that leverage embeddings effectively. This mastery opens career opportunities, enables you to solve more complex problems, and positions you as an expert in a critical area of modern machine learning.
The journey to mastery requires active engagement beyond passive reading. You'll get the most value by experimenting with concepts as you learn them, applying techniques to your own projects, and reflecting on what works and what doesn't. Consider maintaining a learning journal where you document insights, questions, and experiments. Build small projects that let you practice techniques in isolation before integrating them into larger systems. Engage with the broader community through forums, conferences, and open-source contributions. Mastery comes not from reading alone but from the combination of understanding, practice, and reflection. This book provides the roadmap and resources, but your active engagement drives the transformation from intermediate to expert-level capability.
This is the end of the free sample. The full book has 10 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the AI and Machine Learning knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- AI and Machine Learning book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your AI and Machine Learning book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
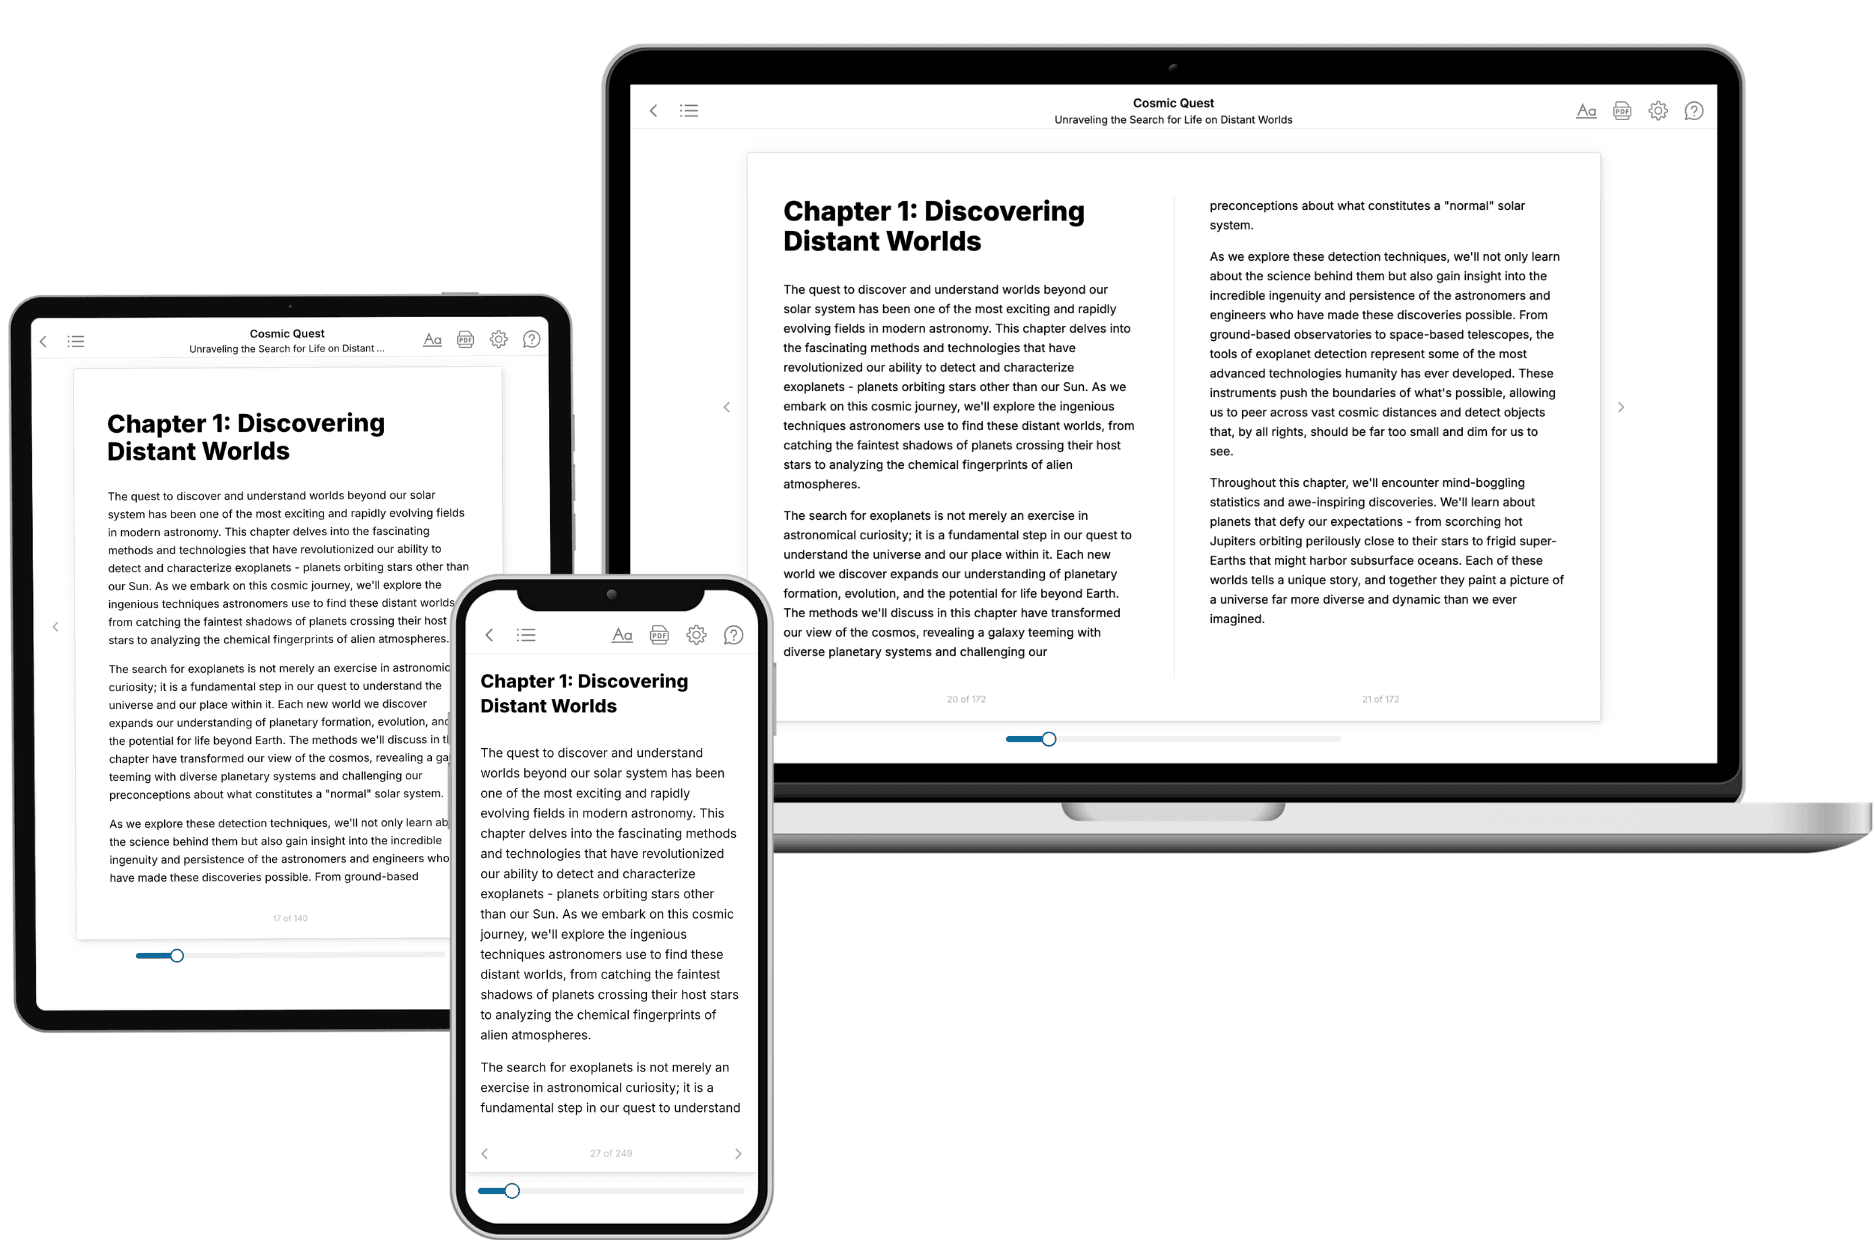
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.