Instruction-Level Parallelism Mastery
Unlocking Performance Through Advanced Processor Architecture and Algorithm Design
Most developers believe that writing faster code simply means using better algorithms or more threads.
331 pages17 chaptersEnglishSep 11, 2025Computer Science and Algorithms
About this book
This common misconception overlooks one of the most powerful performance optimization opportunities available: instruction-level parallelism. While your processor is capable of executing multiple instructions simultaneously within a single thread, most code fails to take advantage of this capability. This comprehensive guide reveals how modern processors actually work beneath the surface, showing you how to write code that naturally exploits instruction-level parallelism. You'll discover the intricate dance between hardware and software that enables processors to find and execute parallel instructions, even in seemingly sequential programs. From understanding pipeline architectures to mastering advanced techniques like out-of-order execution and speculative processing, you'll gain the knowledge needed to optimize performance at the instruction level. Whether you're designing algorithms, optimizing existing code, or architecting new systems, this book provides the deep technical insights you need to harness the full power of modern processors. You'll learn practical techniques for eliminating bottlenecks, reducing dependencies, and structuring code that allows processors to achieve maximum throughput. By the end of this book, you'll have a complete understanding of how instruction-level parallelism works and how to apply this knowledge to create significantly faster, more efficient software that fully utilizes the sophisticated capabilities of contemporary computing architectures.
Table of contents
- IntroductionThe Modern Parallelism Landscape, Why Instruction-Level Parallelism Matters, Our Approach to Mastering ILP, Prerequisites and Background KnowledgeRead below
- Chapter 1: Foundations of Instruction-Level ParallelismDefining Instruction-Level Parallelism, Sequential vs Parallel Instruction Execution, Types of Parallelism in Computing, Measuring and Quantifying ILP
- Chapter 2: Processor Architecture FundamentalsThe Instruction Execution Cycle, Pipeline Architecture Basics, Superscalar Processor Design, Multiple Execution Units and Functional Units
- Chapter 3: Dependencies and HazardsData Dependencies and RAW Hazards, Control Dependencies and Branch Hazards, Structural Hazards and Resource Conflicts, Analyzing and Visualizing Dependencies
- Chapter 4: Pipeline Optimization TechniquesData Forwarding and Bypassing, Minimizing Pipeline Stalls, Optimal Pipeline Depth Considerations, Balancing Pipeline Stages
- Chapter 5: Out-of-Order ExecutionPrinciples of Out-of-Order Execution, Instruction Window and Scheduling, Reorder Buffer and Commit Logic, Reservation Stations and Tomasulo's Algorithm
- Chapter 6: Register Renaming and False DependenciesUnderstanding False Dependencies, Register Renaming Mechanisms, Physical vs Architectural Registers, Advanced Renaming Algorithms
- Chapter 7: Branch Prediction and Speculative ExecutionImpact of Branches on ILP, Branch Prediction Techniques, Speculative Execution Strategies, Branch Misprediction Recovery
- Chapter 8: Memory-Level ParallelismMemory Hierarchy and Access Patterns, Cache-Level Parallelism, Hardware and Software Prefetching, Memory Disambiguation and Load-Store Queues
- Chapter 9: Compiler Techniques for ILPInstruction Scheduling Algorithms, Loop Unrolling and Optimization, Software Pipelining Techniques, Trace Scheduling and Global Optimization
- Chapter 10: VLIW and EPIC ArchitecturesVery Long Instruction Word Principles, Explicitly Parallel Instruction Computing, Compiler-Based Instruction Scheduling, Challenges and Limitations of VLIW
- Chapter 11: Vector Processing and SIMDVector Processing Concepts, SIMD Instruction Sets and Extensions, Auto-Vectorization Techniques, Optimizing Vector Performance
- Chapter 12: Multithreading and ILP InteractionSimultaneous Multithreading Basics, Thread-Level vs Instruction-Level Parallelism, Resource Sharing in SMT Processors, ILP-Aware Thread Scheduling
- Chapter 13: Performance Analysis and ProfilingKey ILP Performance Metrics, Profiling Tools and Techniques, Identifying ILP Bottlenecks, Hardware Performance Counters
- Chapter 14: Code Optimization StrategiesWriting ILP-Friendly Code, Reducing Data Dependencies, Branch Optimization Techniques, Optimizing Memory Access Patterns
- Chapter 15: Algorithm Design for ILPDesigning Inherently Parallel Algorithms, Choosing ILP-Friendly Data Structures, Algorithmic Transformations for Parallelism, Complexity Analysis with ILP Considerations
- Chapter 16: Real-World Case StudiesNumerical Computing Optimizations, Image and Signal Processing Applications, Database Query Processing, Scientific Computing Applications
- Chapter 17: Future Trends and Emerging TechnologiesQuantum Computing and Parallelism, Neuromorphic Computing Architectures, AI Accelerators and Specialized Processors, The Future of Instruction-Level Parallelism
- ConclusionKey Takeaways and Summary, Applying ILP Knowledge in Practice
- Glossary
- Further Reading
Introduction
Every second, your processor executes billions of instructions with remarkable efficiency, yet most software developers remain unaware of the sophisticated parallelism techniques happening beneath their code. While you focus on algorithms, data structures, and high-level optimizations, your processor is simultaneously executing multiple instructions, predicting branches, reordering operations, and managing complex dependencies—all within a single thread of execution. This hidden layer of parallelism, known as instruction-level parallelism (ILP), represents one of the most significant opportunities for performance optimization that most programmers never fully understand or exploit.
The gap between what processors can do and what most code allows them to do is substantial. Modern processors contain sophisticated hardware capable of executing four, six, or even eight instructions simultaneously within a single clock cycle. They can look ahead hundreds of instructions, predict which branches your program will take, and execute operations speculatively before they're even needed. Yet the majority of software fails to take advantage of these capabilities, leaving enormous performance potential untapped. This disconnect exists because instruction-level parallelism operates at a level of abstraction that traditional programming education rarely addresses in depth.
Understanding instruction-level parallelism is not merely an academic exercise—it's a practical necessity for anyone serious about performance optimization. Whether you're developing high-performance computing applications, optimizing database queries, processing large datasets, or simply trying to make your software run faster, the principles of ILP directly impact your results. The difference between code that naturally exploits instruction-level parallelism and code that doesn't can be the difference between applications that scale efficiently and those that struggle to utilize modern hardware effectively.
This book bridges the gap between high-level programming concepts and low-level processor architecture, providing you with the knowledge and tools needed to write code that naturally exploits instruction-level parallelism. You'll discover how to identify and eliminate the bottlenecks that prevent processors from achieving maximum throughput, learn to structure algorithms that expose parallelism opportunities, and master the techniques that allow modern processors to execute your code at peak efficiency. By the end of this journey, you'll possess a deep understanding of how instruction-level parallelism works and how to harness its power in practical applications.
The Modern Parallelism Landscape
The computing landscape has evolved dramatically over the past several decades, with parallelism becoming the dominant strategy for achieving performance improvements. However, parallelism manifests at multiple levels, each with distinct characteristics, challenges, and optimization strategies. Understanding where instruction-level parallelism fits within this broader landscape is crucial for appreciating its unique role and importance. The parallelism hierarchy spans from bit-level operations within individual instructions to massive distributed systems processing data across continents, with each level requiring different approaches and considerations.
At the highest level, distributed parallelism involves multiple independent systems working together across networks, often spanning geographic regions. This form of parallelism deals with challenges like network latency, fault tolerance, and data consistency across systems that may be thousands of miles apart. Below this, process-level parallelism involves multiple independent programs running simultaneously on the same system, managed by the operating system's scheduler. Each process operates in its own memory space, providing isolation but requiring explicit communication mechanisms like pipes, sockets, or shared memory segments when coordination is necessary.
Thread-level parallelism represents the form of parallelism most familiar to application developers, involving multiple threads of execution within a single process. Threads share memory space and resources, enabling easier communication but introducing challenges related to synchronization, race conditions, and deadlocks. Modern multi-core processors excel at thread-level parallelism, with each core capable of executing independent threads simultaneously. However, thread-level parallelism requires explicit programming—developers must identify parallelizable work, create threads, manage synchronization, and handle the complexities of concurrent execution.
Instruction-level parallelism operates at a fundamentally different level, focusing on the simultaneous execution of multiple instructions within a single thread. Unlike thread-level parallelism, ILP doesn't require explicit programming—instead, it emerges from the natural structure of sequential code when that code is written in ways that expose parallelism opportunities. The processor's hardware automatically identifies instructions that can execute simultaneously, manages dependencies, and coordinates execution across multiple functional units. This automatic nature makes ILP both powerful and subtle—it can provide significant performance improvements without requiring major changes to programming models, but it also means that many developers remain unaware of its impact on their code's performance.
The relationship between these different levels of parallelism is complex and interdependent. A distributed system might use process-level parallelism to coordinate work across multiple nodes, thread-level parallelism to utilize multiple cores within each node, and instruction-level parallelism to maximize the efficiency of each thread's execution. However, these levels can also compete for resources and attention. For example, excessive thread creation can actually reduce instruction-level parallelism by fragmenting the processor's resources and increasing context switching overhead. Understanding these interactions is crucial for making informed decisions about where to focus optimization efforts.
Modern processor architectures have evolved to support multiple forms of parallelism simultaneously. Simultaneous multithreading (SMT) technologies like Intel's Hyper-Threading allow a single physical core to execute multiple threads concurrently, sharing execution resources between threads to improve overall utilization. This creates interesting interactions between thread-level and instruction-level parallelism—when one thread stalls due to memory access or branch misprediction, the other thread can continue executing, maintaining high utilization of the processor's functional units. However, threads also compete for shared resources like caches, execution units, and branch predictors, creating complex performance trade-offs.
The evolution toward parallelism has been driven by fundamental physical limitations in processor design. For decades, performance improvements came primarily from increasing clock frequencies and improving single-threaded execution efficiency. However, power consumption increases exponentially with frequency, and heat dissipation became a limiting factor. The industry's response was to shift toward parallel architectures—adding more cores, improving instruction-level parallelism, and developing specialized processing units for specific workloads. This shift means that understanding parallelism at all levels has become essential for achieving good performance, rather than being an advanced optimization technique.
The practical implications of this parallelism landscape are significant for software developers. Applications that can effectively utilize multiple levels of parallelism simultaneously often achieve dramatically better performance than those that focus on only one level. For example, a scientific computing application might use distributed parallelism to coordinate work across a cluster, thread-level parallelism to utilize all cores within each node, vector instructions to process multiple data elements simultaneously, and careful algorithm design to expose instruction-level parallelism within each computational kernel. This multi-level approach requires understanding the characteristics and optimization strategies for each form of parallelism.
However, the complexity of modern parallelism also creates challenges for developers. Debugging parallel applications is inherently more difficult than debugging sequential code, as bugs may be timing-dependent and difficult to reproduce. Performance analysis becomes more complex when multiple levels of parallelism interact, making it challenging to identify bottlenecks and optimization opportunities. Additionally, the optimal parallelization strategy often depends on the target hardware architecture, problem size, and data characteristics, requiring developers to understand not just programming techniques but also the underlying hardware capabilities and limitations.
Why Instruction-Level Parallelism Matters
Instruction-level parallelism represents a unique and powerful form of performance optimization because it operates transparently within existing sequential programming models while providing substantial performance benefits. Unlike thread-level parallelism, which requires explicit programming and careful management of shared resources, ILP emerges naturally from well-structured sequential code. This means that understanding and optimizing for instruction-level parallelism can improve performance without the complexity, debugging challenges, and potential race conditions associated with multi-threaded programming. The processor's hardware automatically identifies parallelizable instructions, manages dependencies, and coordinates execution, making ILP an attractive optimization target for developers who want performance improvements without architectural complexity.
The performance impact of instruction-level parallelism can be dramatic, particularly for computationally intensive applications. Modern superscalar processors can theoretically execute multiple instructions per clock cycle—often four to eight instructions simultaneously—when the code structure allows it. However, real-world applications frequently achieve much lower instruction throughput due to dependencies, branch mispredictions, and other factors that limit parallelism. Research studies have shown that optimizing code for better instruction-level parallelism can improve performance by factors of two to five or more, depending on the application domain[1]. These improvements come not from using more computational resources, but from using existing resources more efficiently.
The economic implications of instruction-level parallelism optimization are substantial, particularly in environments where computational efficiency directly impacts costs. In cloud computing environments, where resources are billed based on usage time, applications that execute twice as fast cost half as much to run. For organizations processing large datasets, optimizing for ILP can reduce processing time from hours to minutes, enabling more frequent analysis and faster decision-making. In embedded systems and mobile devices, better instruction-level parallelism can extend battery life by completing tasks more quickly and allowing the processor to enter low-power states sooner. These benefits compound across millions of devices or thousands of server instances, creating significant economic value.
Instruction-level parallelism also provides a foundation for other optimization techniques. Applications that effectively utilize ILP often scale better when additional optimization strategies are applied. For example, code that exposes good instruction-level parallelism typically vectorizes more effectively, as vector instructions can operate on multiple data elements while maintaining the parallel execution of surrounding instructions. Similarly, ILP-optimized code often exhibits better cache behavior, as the reduced execution time and improved instruction scheduling can lead to more predictable memory access patterns. This synergistic effect means that understanding ILP principles enhances the effectiveness of other performance optimization strategies.
The relevance of instruction-level parallelism extends across diverse application domains, each with specific characteristics that make ILP optimization particularly valuable:
- Scientific Computing: Numerical algorithms often contain loops with independent iterations and mathematical operations that can execute in parallel, making them ideal candidates for ILP optimization
- Image and Signal Processing: Pixel-level operations and filter applications naturally expose parallelism opportunities, with each operation potentially executing simultaneously
- Database Systems: Query processing involves scanning, filtering, and aggregating operations that can benefit significantly from instruction-level parallelism
- Compiler and Language Runtime Systems: The performance of development tools directly impacts developer productivity, making ILP optimization valuable for the entire software development ecosystem
Modern processor architectures have invested heavily in instruction-level parallelism capabilities, making understanding these features essential for achieving good performance. Contemporary processors include sophisticated branch predictors that can accurately predict conditional jumps, out-of-order execution engines that can reorder instructions to expose parallelism, and register renaming mechanisms that eliminate false dependencies between instructions. These features represent significant portions of the processor's transistor budget and design complexity, indicating their importance for overall system performance. However, these capabilities can only be effective when the software provides opportunities for parallel execution.
The trend toward specialized processing units and accelerators makes instruction-level parallelism knowledge even more valuable. Graphics processing units (GPUs), digital signal processors (DSPs), and AI accelerators all rely heavily on instruction-level parallelism principles, often implementing these concepts in more explicit and visible ways than traditional CPUs. Understanding ILP provides a foundation for effectively utilizing these specialized processors, as the same principles of dependency analysis, parallel execution, and resource utilization apply across different architectures. As computing continues to diversify across specialized hardware, ILP knowledge becomes increasingly transferable and valuable.
The educational value of studying instruction-level parallelism extends beyond immediate performance benefits. ILP concepts provide deep insights into how modern processors actually work, bridging the gap between high-level programming abstractions and low-level hardware implementation. This understanding helps developers make better decisions about algorithm design, data structure selection, and code organization. It also provides a foundation for understanding more advanced topics like computer architecture, compiler optimization, and parallel algorithm design. Many concepts that seem mysterious at higher levels of abstraction—such as why certain coding patterns perform better than others—become clear when viewed through the lens of instruction-level parallelism.
Perhaps most importantly, instruction-level parallelism represents a sustainable approach to performance optimization. Unlike some optimization techniques that become obsolete as hardware evolves, the fundamental principles of ILP remain relevant across different processor generations and architectures. While specific implementation details may change, the core concepts of dependency analysis, parallel execution, and resource utilization continue to apply. This makes time invested in understanding ILP a long-term asset that continues to provide value as technology evolves. Additionally, because ILP optimization often involves writing cleaner, more structured code with fewer dependencies, it frequently improves code maintainability and readability alongside performance.
Our Approach to Mastering ILP
This book takes a systematic, layered approach to instruction-level parallelism, building from fundamental concepts to advanced optimization techniques through a combination of theoretical understanding and practical application. Rather than treating ILP as an abstract academic topic, we focus on actionable knowledge that you can immediately apply to real-world software development challenges. Each concept is introduced with clear explanations of both the underlying principles and their practical implications, supported by concrete examples, case studies, and hands-on exercises that demonstrate how these principles apply to actual code optimization scenarios.
Our methodology emphasizes the connection between hardware capabilities and software structure, helping you develop an intuitive understanding of how processors execute instructions in parallel. We begin with processor architecture fundamentals, ensuring you understand the hardware context in which instruction-level parallelism operates. This foundation includes detailed coverage of pipeline architectures, superscalar design principles, and the various execution units that enable parallel instruction processing. By understanding the hardware context first, you'll be better equipped to recognize why certain coding patterns enable parallelism while others create bottlenecks that limit performance.
The book progresses through increasingly sophisticated topics, with each chapter building upon concepts introduced in previous sections. We start with basic dependency analysis and hazard identification, teaching you to recognize the fundamental obstacles to parallel execution. From there, we explore the hardware mechanisms that processors use to overcome these obstacles, including out-of-order execution, register renaming, and speculative processing. Finally, we cover advanced optimization techniques, including compiler-based approaches, algorithm design strategies, and specialized architectures that push the boundaries of instruction-level parallelism.
Throughout the book, we maintain a strong emphasis on practical application through multiple complementary approaches:
- Code Examples: Every major concept is illustrated with specific code examples that demonstrate both problematic patterns that limit ILP and optimized versions that expose parallelism opportunities
- Performance Analysis: We provide detailed analysis of how different coding approaches impact instruction-level parallelism, including quantitative measurements where possible
- Case Studies: Real-world applications from various domains illustrate how ILP principles apply to different types of computational problems
- Hands-on Exercises: Practical exercises allow you to apply concepts immediately and develop intuition through direct experience
Our treatment of instruction-level parallelism is comprehensive but accessible, avoiding unnecessary mathematical complexity while maintaining technical accuracy. We recognize that readers come from diverse backgrounds and may have varying levels of experience with computer architecture concepts. Therefore, we provide sufficient background information to make the material accessible to software engineers and computer science students, while also including advanced topics that will challenge experienced practitioners. Key concepts are reinforced through multiple examples and different perspectives, ensuring that readers with different learning styles can grasp the essential principles.
The book integrates multiple tools and techniques for analyzing and optimizing instruction-level parallelism. We cover both theoretical analysis methods—such as dependency graphs and critical path analysis—and practical tools including performance profilers, hardware performance counters, and compiler optimization reports. This multi-faceted approach ensures that you can both understand ILP concepts intellectually and apply them effectively in practice. We also discuss the limitations and trade-offs associated with different optimization approaches, helping you make informed decisions about when and how to apply various techniques.
Special attention is given to the interaction between instruction-level parallelism and other forms of parallelism and optimization. We explore how ILP optimization affects and is affected by thread-level parallelism, vectorization, memory hierarchy optimization, and compiler transformations. This holistic perspective is essential because real-world performance optimization rarely involves optimizing for a single factor in isolation. Understanding these interactions helps you make better decisions about optimization priorities and avoid optimizations that improve one aspect of performance while degrading others.
The book also addresses the practical challenges of ILP optimization in real-world development environments. We discuss how to balance optimization effort with development time constraints, how to maintain code readability and maintainability while optimizing for performance, and how to validate that optimizations actually improve performance in production environments. These practical considerations are often overlooked in academic treatments of the subject but are crucial for successfully applying ILP knowledge in professional software development contexts.
Our approach recognizes that instruction-level parallelism is a rapidly evolving field, with new processor architectures and optimization techniques constantly emerging. Rather than focusing solely on current technologies, we emphasize fundamental principles that remain relevant across different architectures and time periods. This approach ensures that the knowledge you gain from this book will continue to be valuable as hardware and software technologies evolve. We also discuss emerging trends and future directions in ILP research and development, helping you anticipate how these concepts might evolve in coming years.
Prerequisites and Background Knowledge
This book assumes a solid foundation in computer science fundamentals and programming experience, but does not require extensive background in computer architecture or hardware design. The ideal reader has completed undergraduate coursework in data structures, algorithms, and computer systems, or possesses equivalent practical experience through professional software development. You should be comfortable reading and analyzing code in languages like C, C++, or similar systems programming languages, as our examples frequently operate at a level where language-specific performance characteristics matter. Additionally, basic familiarity with assembly language concepts—such as registers, memory addressing, and instruction types—will be helpful, though we provide sufficient background to make the material accessible to those with limited assembly experience.
Mathematical prerequisites are minimal but important for understanding performance analysis and optimization trade-offs. You should be comfortable with basic discrete mathematics, including logarithms, exponential functions, and asymptotic analysis (Big O notation). Some sections involve statistical concepts for analyzing performance measurements and understanding probabilistic behaviors like branch prediction accuracy, but we explain these concepts as they arise. Linear algebra knowledge is helpful for understanding vector processing and SIMD concepts, but is not essential for grasping the core ILP principles. Most importantly, you should be comfortable with quantitative reasoning and analyzing trade-offs between different design alternatives.
Programming experience requirements focus more on depth than breadth across multiple languages. You should have experience with at least one compiled language and understand the relationship between source code and executable instructions. Experience with performance optimization, debugging, or systems programming is valuable but not required—we cover the necessary background as part of our discussion. However, you should be comfortable with concepts like memory management, function calls, loops, and conditional statements at a level where you can reason about their implementation and performance characteristics. Experience with profiling tools or performance analysis is helpful but not essential.
Computer systems knowledge forms an important foundation for understanding instruction-level parallelism concepts. You should understand basic computer organization principles, including:
- Memory Hierarchy: The relationship between registers, cache levels, main memory, and storage, including why memory access patterns affect performance
- Instruction Execution: Basic understanding of how processors fetch, decode, and execute instructions, even if you haven't studied pipeline architectures in detail
- Program Compilation: How source code transforms into executable instructions, including the role of compilers in optimization
- Operating System Concepts: Process and thread management, virtual memory, and how the OS interacts with hardware resources
While prior computer architecture coursework is beneficial, it is not strictly required. We provide comprehensive coverage of the architectural concepts necessary for understanding instruction-level parallelism, starting from basic principles and building to advanced topics. However, readers with architecture background will be able to progress more quickly through foundational material and focus on the optimization and application aspects that form the book's core contribution. If you have studied computer architecture previously, you may find that this book provides a more application-focused perspective on concepts you've encountered in academic contexts.
Software engineering experience, particularly with performance-critical applications, provides valuable context for understanding when and how to apply ILP optimization techniques. Experience with any of the following domains will enhance your ability to apply the concepts covered in this book:
- High-Performance Computing: Scientific computing, numerical analysis, or simulation applications
- Systems Programming: Operating systems, database systems, compilers, or runtime systems
- Real-Time Systems: Embedded systems, game engines, or other applications with strict timing requirements
- Data Processing: Analytics, machine learning, or large-scale data transformation applications
Tool familiarity, while not required, will enhance your ability to apply the concepts practically. Experience with performance profiling tools, debuggers, or compiler optimization flags will help you immediately apply the techniques we discuss. However, we provide guidance on using relevant tools as part of our practical examples and exercises. Similarly, familiarity with version control systems and systematic performance testing approaches will help you apply optimization techniques safely in production environments, but we cover these methodological aspects as part of our discussion of practical optimization workflows.
Perhaps most importantly, this book requires intellectual curiosity about how systems work beneath the surface and willingness to think about performance optimization as a systematic discipline rather than an ad-hoc collection of tricks. Instruction-level parallelism optimization often involves understanding subtle interactions between code structure and hardware behavior, requiring patience and attention to detail. The most successful readers will be those who enjoy understanding not just what optimization techniques work, but why they work and when they should be applied. This mindset, combined with the technical prerequisites outlined above, will enable you to gain maximum value from the concepts and techniques presented in this book.
Notes
Introduction
- 1. J. L. Hennessy and D. A. Patterson, Computer Architecture: A Quantitative Approach, Morgan Kaufmann, 2019
This is the end of the free sample. The full book has 17 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Computer Science and Algorithms knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Computer Science and Algorithms book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Computer Science and Algorithms book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
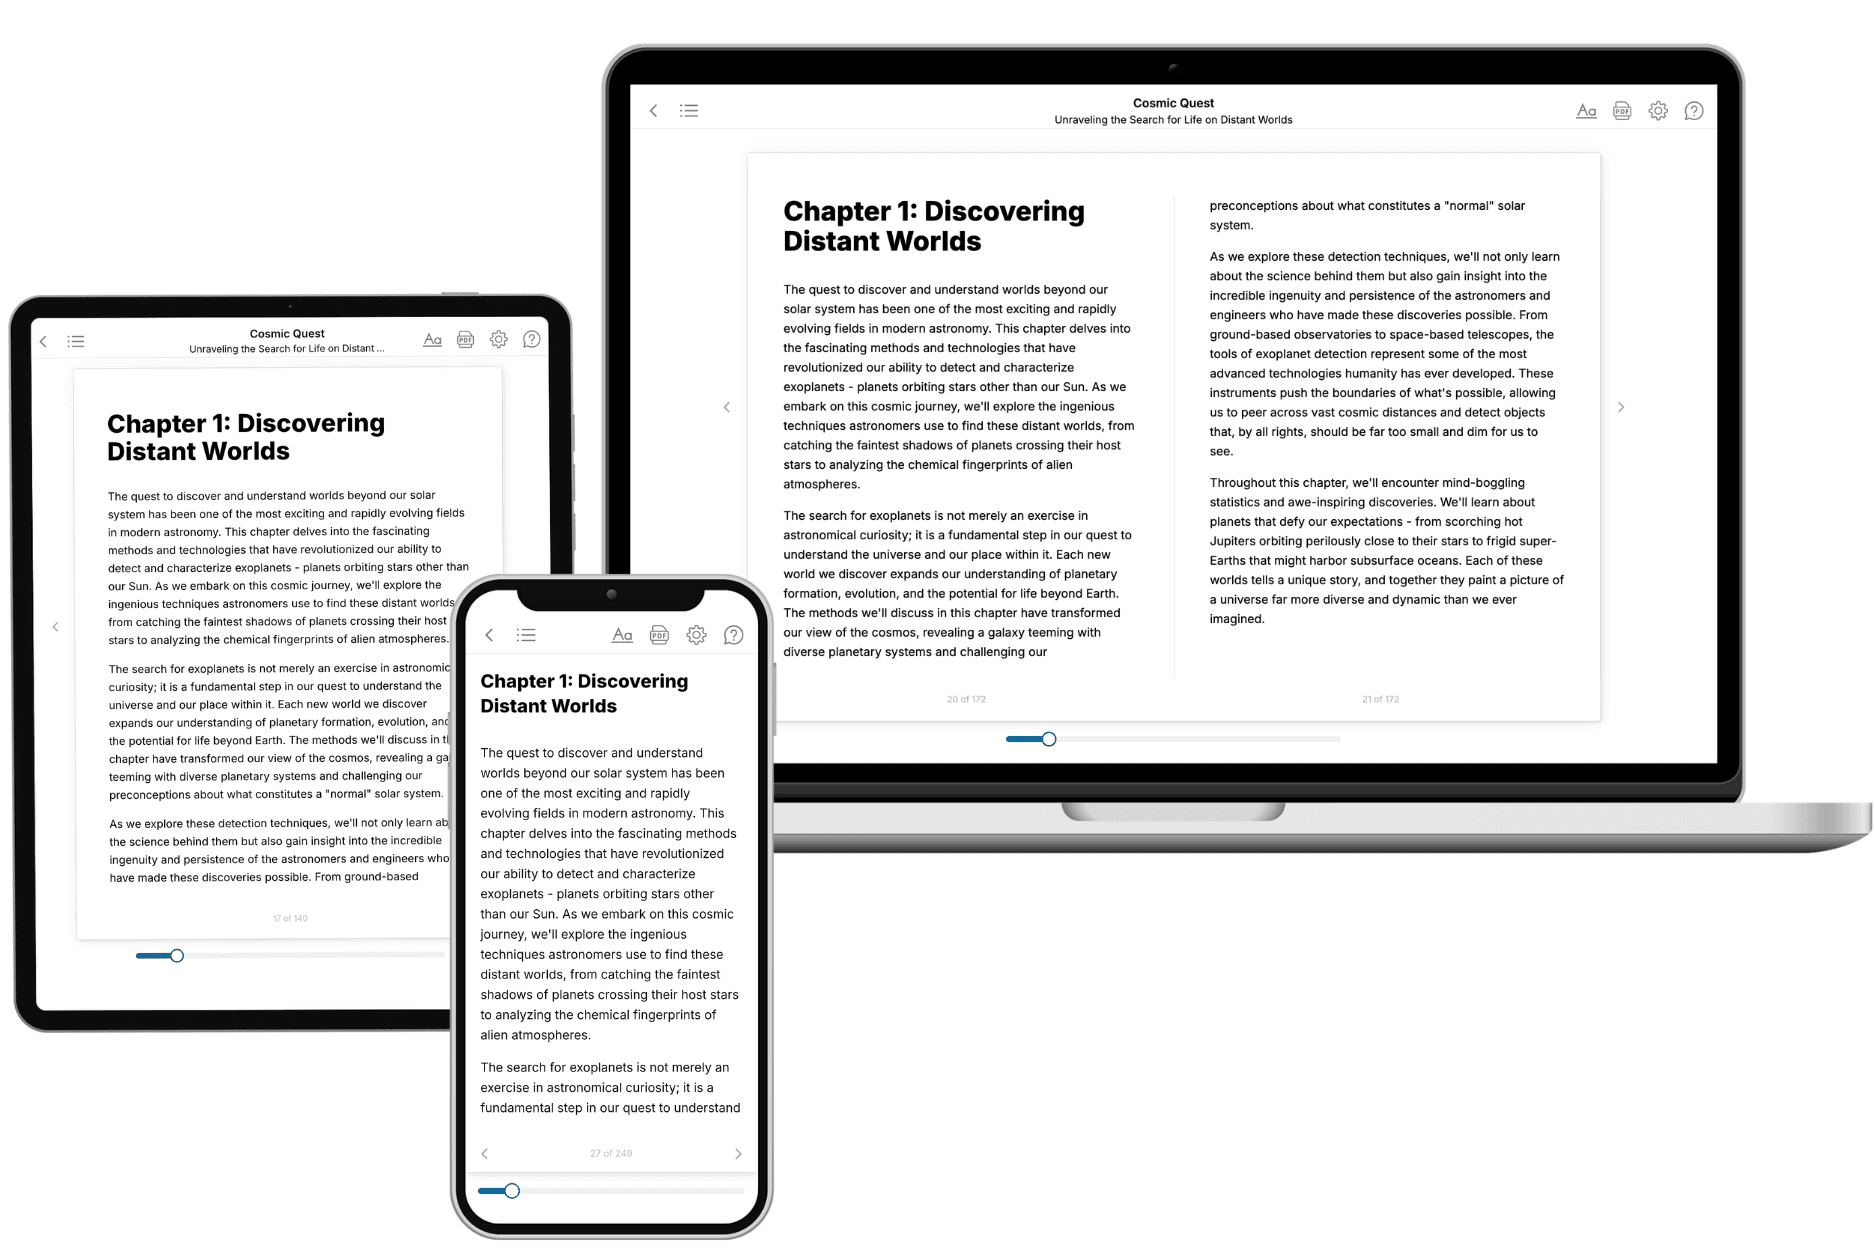
- 3. Get your tailored book
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.