Mastering Huffman Coding
Optimizing Data Compression and Time Complexity in Computer Science
Revolutionize your approach to data compression and algorithm optimization with "Mastering Huffman Coding." This comprehensive guide takes you on a deep dive into the world of Huffman Coding, a powerful technique that sits at the intersection of data compression and time complexity optimization.
269 pages13 chaptersDec 9, 2024Algorithm Analysis
About this book
You'll gain a thorough understanding of Huffman Coding's principles, implementation, and real-world applications. From building efficient data structures to analyzing time complexity, this book equips you with the knowledge to create more streamlined and performant algorithms. Whether you're tackling file compression, network data transfer, or seeking to optimize your code's runtime, "Mastering Huffman Coding" provides you with the tools and insights to excel. By the end of this journey, you'll be able to implement Huffman Coding with confidence, analyze its impact on time complexity, and apply these skills to a wide range of computer science challenges.
Table of contents
- IntroductionThe Importance of Data Compression in Computer Science, Overview of Huffman Coding, Structure of the Book, Prerequisites and Assumed KnowledgeRead below
- Chapter 1: Foundations of Data CompressionIntroduction to Information Theory, The Concept of Entropy, Lossless vs. Lossy Compression, Prefix-Free Codes
- Chapter 2: Huffman Coding BasicsThe Huffman Algorithm, Frequency Analysis, Constructing Huffman Trees, Assigning Codes to Symbols
- Chapter 3: Data Structures for Huffman CodingBinary Trees in Huffman Coding, Priority Queues and Heaps, Hash Tables for Frequency Counting, Bit Manipulation Techniques
- Chapter 4: Implementing Huffman CodingHuffman Encoding Algorithm, Huffman Decoding Algorithm, Serializing Huffman Codes, Error Handling and Edge Cases
- Chapter 5: Time Complexity Analysis of Huffman CodingTime Complexity of Encoding, Time Complexity of Decoding, Complexity of Tree Construction, Overall Performance Considerations
- Chapter 6: Space Complexity and Memory ManagementMemory Usage in Huffman Coding, Efficient Tree Representation, Storing and Accessing Code Tables, Memory Optimization Techniques
- Chapter 7: Optimizing Huffman CodingCanonical Huffman Codes, Adaptive Huffman Coding, Parallel Huffman Coding, Variations and Improvements
- Chapter 8: Applications of Huffman CodingFile Compression Systems, Data Transmission in Networks, Image and Multimedia Compression, Error Correction Codes
- Chapter 9: Comparing Huffman Coding with Other AlgorithmsRun-Length Encoding, Arithmetic Coding, LZW Compression, Performance Trade-offs and Use Cases
- Chapter 10: Advanced Topics in Huffman CodingDynamic Huffman Coding, Two-Pass Huffman Coding, Length-Limited Huffman Coding, Wavelet Trees and Huffman Coding
- Chapter 11: Practical Implementation ConsiderationsChoosing the Right Programming Language, Testing and Debugging Strategies, Performance Profiling and Optimization, Dealing with Scalability Issues
- Chapter 12: Real-World Examples and Case StudiesText Compression in Document Management, Video Streaming and Huffman Coding, DNA Sequence Compression, Wireless Communication Protocols
- Chapter 13: Future Directions and ResearchQuantum Huffman Coding, Machine Learning and Adaptive Compression, Huffman Coding in Big Data Scenarios, Emerging Applications and Challenges
- ConclusionKey Takeaways, The Future of Huffman Coding
- Glossary
- Further Reading
Introduction
In the ever-evolving landscape of computer science, the ability to efficiently manage and process data stands as a cornerstone of technological advancement. As the volume of digital information continues to grow exponentially, the need for effective data compression techniques has become increasingly crucial. Among these techniques, Huffman Coding emerges as a fundamental and powerful method that not only addresses the challenges of data compression but also plays a significant role in optimizing time complexity in various algorithms and applications.
This book, "Mastering Huffman Coding: Optimizing Data Compression and Time Complexity in Computer Science," is designed to provide you with a comprehensive understanding of Huffman Coding, its implementation, and its far-reaching implications in the realm of computer science. Whether you're a computer science student looking to deepen your knowledge of algorithms and data structures, or a professional seeking to enhance your skills in data compression and algorithm optimization, this book will serve as your guide to mastering this essential technique.
Throughout the following chapters, you'll embark on a journey that will take you from the foundational principles of data compression to the intricate details of implementing and optimizing Huffman Coding. You'll discover how this elegant algorithm can be applied to solve real-world problems, improve system performance, and push the boundaries of what's possible in data processing and transmission.
As we delve into the world of Huffman Coding, you'll gain insights into its historical context, theoretical underpinnings, and practical applications. You'll learn how to construct Huffman trees, analyze time and space complexities, and implement the algorithm in various programming languages. Moreover, you'll explore advanced topics and optimizations that will enable you to leverage Huffman Coding to its fullest potential in your projects and research.
By the end of this book, you'll possess a robust understanding of Huffman Coding that will empower you to tackle complex data compression challenges, optimize algorithms, and contribute to the ongoing evolution of computer science. Let's begin this exciting journey into the heart of one of the most influential algorithms in the field of data compression and algorithmic optimization.
The Importance of Data Compression in Computer Science
Data compression stands as a cornerstone in the edifice of modern computer science, playing a pivotal role in shaping the digital landscape we navigate daily. Its importance cannot be overstated, as it touches nearly every aspect of our digital lives, from the images we share on social media to the complex data transmissions that power global communications networks. At its core, data compression is about efficiency – the art and science of representing information in the most compact form possible without losing essential content.
In an era where data is often referred to as the new oil, the ability to efficiently store, process, and transmit vast amounts of information has become a critical factor in technological advancement. The exponential growth of digital data, driven by factors such as the proliferation of mobile devices, the Internet of Things (IoT), and the increasing resolution of digital media, has made data compression more relevant than ever. According to a report by IDC, the global datasphere is projected to grow from 33 zettabytes in 2018 to 175 zettabytes by 2025, a staggering increase that underscores the urgent need for effective compression techniques[1].
Data compression serves multiple crucial functions in the realm of computer science. Firstly, it enables more efficient storage of information. By reducing the size of files and datasets, compression allows for better utilization of storage resources, whether it's on personal devices or in large-scale data centers. This efficiency translates directly into cost savings and improved performance, as smaller data sizes mean faster read and write operations. For instance, in cloud computing environments, where storage costs can be significant, effective compression can lead to substantial reductions in operational expenses.
Secondly, data compression plays a vital role in network communications. In a world where real-time data transfer is increasingly important, the ability to transmit information quickly and efficiently over networks is paramount. Compression reduces the amount of data that needs to be sent, thereby decreasing transmission times and bandwidth requirements. This is particularly crucial in scenarios with limited bandwidth, such as mobile networks or satellite communications. The impact of compression on network performance is so significant that it has become an integral part of many communication protocols and standards.
Furthermore, data compression intersects with other important areas of computer science, enhancing their effectiveness. In the field of information security, for example, compression is often used in conjunction with encryption to improve overall system security. By compressing data before encryption, the amount of information exposed to potential attacks is reduced, and the encryption process itself can become more efficient. Similarly, in the domain of machine learning and artificial intelligence, compression techniques are employed to manage large datasets, enabling more efficient training of models and faster inference times.
The importance of data compression extends beyond mere efficiency gains; it has profound implications for sustainability in technology. As the world grapples with the environmental impact of digital technologies, compression emerges as a key tool in reducing the carbon footprint of data centers and network infrastructure. By minimizing storage requirements and data transfer volumes, compression contributes to lower energy consumption and, consequently, reduced greenhouse gas emissions. A study by the Berkeley Lab estimated that data centers in the United States alone could reduce their energy use by 80% through efficiency measures, including better data management and compression techniques[2].
In the realm of scientific computing and big data analytics, data compression enables researchers and analysts to work with massive datasets that would otherwise be unwieldy or impossible to process. Fields such as genomics, climate modeling, and particle physics generate enormous volumes of data that require sophisticated compression techniques to store and analyze effectively. The ability to compress this data without losing critical information can lead to breakthroughs in scientific understanding and technological innovation.
As we look to the future, the importance of data compression is only set to grow. Emerging technologies such as 5G networks, augmented and virtual reality, and autonomous vehicles will generate and consume data at unprecedented rates, making efficient compression more critical than ever. Moreover, as we push the boundaries of quantum computing and explore new paradigms in data storage and processing, compression techniques will need to evolve to meet these new challenges.
In this context, understanding and mastering data compression techniques like Huffman Coding becomes not just an academic exercise but a practical necessity for anyone working in computer science and related fields. Huffman Coding, with its elegant balance of simplicity and effectiveness, serves as an excellent entry point into the world of data compression. It embodies fundamental principles that underpin more complex compression algorithms and provides a solid foundation for understanding the trade-offs involved in designing efficient data representation schemes.
As you delve deeper into the study of Huffman Coding in the subsequent chapters of this book, keep in mind the broader context of data compression's importance in computer science. The skills and knowledge you gain will not only enhance your understanding of this specific algorithm but will also equip you with valuable insights applicable to a wide range of computational challenges. Whether you're developing mobile applications, designing network protocols, or working on cutting-edge research in data science, a solid grasp of data compression principles will prove invaluable in your journey through the ever-expanding universe of computer science.
Overview of Huffman Coding
Huffman Coding, named after its creator David A. Huffman, stands as a cornerstone in the field of data compression and information theory. Developed in 1952 while Huffman was a Ph.D. student at MIT, this elegant algorithm has withstood the test of time, remaining relevant and widely used even in today's advanced technological landscape. At its core, Huffman Coding is a method for lossless data compression that achieves remarkable efficiency by assigning variable-length codes to input characters, with shorter codes given to more frequent characters.
The fundamental principle behind Huffman Coding is deceptively simple yet profoundly effective. It operates on the premise that not all characters in a dataset occur with equal frequency. By leveraging this inherent inequality in character distribution, Huffman Coding constructs a binary tree structure known as a Huffman tree. This tree serves as the basis for generating optimal prefix-free codes, where no code word is a prefix of another. This property ensures unambiguous decoding, a critical feature that sets Huffman Coding apart from many other compression techniques.
To understand the power of Huffman Coding, consider a simple example. In the English language, the letter 'e' appears much more frequently than the letter 'z'. Traditional fixed-length encoding would assign the same number of bits to both characters. Huffman Coding, however, would assign a shorter code to 'e' and a longer code to 'z'. This variable-length coding scheme results in significant space savings when applied across an entire text, with more frequent characters requiring fewer bits to represent.
The process of Huffman Coding can be broken down into several key steps. First, the algorithm analyzes the input data to determine the frequency of each character. These frequencies are then used to build a priority queue, where each character is treated as a leaf node of the Huffman tree. The algorithm proceeds by repeatedly combining the two nodes with the lowest frequencies to form a new internal node, until a single tree is formed. The paths from the root to each leaf in this final tree define the Huffman codes for each character.
One of the most remarkable aspects of Huffman Coding is its optimality. For a given set of character frequencies, Huffman Coding produces the most efficient prefix-free codes possible. This optimality is guaranteed by the greedy nature of the algorithm, which always makes the locally optimal choice at each step. The result is a globally optimal solution, a property that has been rigorously proven and contributes to the algorithm's enduring popularity.
The time complexity of Huffman Coding is another factor that contributes to its widespread use. The encoding process, which includes building the Huffman tree and generating the codes, has a time complexity of O(n log n), where n is the number of unique characters in the input. This efficiency makes Huffman Coding suitable for a wide range of applications, from small-scale data compression tasks to large-scale systems processing massive amounts of information.
In practice, Huffman Coding finds applications across a diverse array of fields within computer science and beyond. It serves as a fundamental component in many file compression utilities, such as GZIP and PKZIP. In multimedia compression, Huffman Coding is often used in conjunction with other techniques to achieve high compression ratios for images, audio, and video. The algorithm also plays a crucial role in data transmission protocols, helping to optimize bandwidth usage in network communications.
Beyond its direct applications in compression, Huffman Coding has had a profound influence on the development of other algorithms and data structures. The concept of using trees for efficient data representation, as exemplified by Huffman trees, has inspired numerous other tree-based data structures used in various areas of computer science. Moreover, the principles underlying Huffman Coding have contributed to the development of more advanced compression techniques, such as arithmetic coding and adaptive Huffman coding.
As we delve deeper into Huffman Coding throughout this book, you'll gain a comprehensive understanding of its inner workings, implementation details, and practical applications. You'll learn how to construct Huffman trees, generate and manipulate Huffman codes, and analyze the algorithm's performance in various scenarios. This knowledge will not only equip you with a powerful tool for data compression but also provide insights into fundamental concepts in algorithm design, data structures, and information theory.
It's worth noting that while Huffman Coding is a powerful and elegant solution to many compression problems, it is not without limitations. For instance, it requires knowledge of character frequencies in advance, which may not always be available or practical to obtain. Additionally, for sources with very skewed probability distributions, other techniques like arithmetic coding may achieve better compression ratios. Understanding these limitations is crucial for making informed decisions about when and how to apply Huffman Coding in real-world scenarios.
As you progress through this book, you'll discover that mastering Huffman Coding is about more than just learning an algorithm; it's about developing a deeper appreciation for the interplay between data representation, algorithmic efficiency, and information theory. The principles you'll encounter here will serve as a foundation for understanding more complex compression techniques and will enhance your overall problem-solving skills in computer science.
In the chapters that follow, we'll build upon this overview, exploring each aspect of Huffman Coding in detail. From the theoretical foundations to practical implementations, from basic concepts to advanced optimizations, this book will guide you through every facet of this fascinating algorithm. By the end of your journey, you'll possess not just knowledge of Huffman Coding, but a comprehensive understanding of its place in the broader landscape of data compression and algorithm design.
Structure of the Book
"Mastering Huffman Coding: Optimizing Data Compression and Time Complexity in Computer Science" is structured to provide a comprehensive and logical progression through the subject matter. The book is designed to build your understanding from foundational concepts to advanced applications, ensuring that you develop a thorough grasp of Huffman Coding and its broader implications in computer science. Each chapter is carefully crafted to introduce new concepts while reinforcing previously learned material, creating a cohesive learning experience that will deepen your expertise as you progress.
The book begins with this introduction, setting the stage for your journey into the world of Huffman Coding. Following this, Chapter 1, "Foundations of Data Compression," lays the groundwork by exploring the fundamental principles of information theory and data compression. This chapter introduces key concepts such as entropy, lossless and lossy compression, and prefix-free codes, providing the theoretical context necessary for understanding Huffman Coding's place in the broader field of data compression.
Chapter 2, "Huffman Coding Basics," delves into the core algorithm itself. Here, you'll learn about the Huffman algorithm's step-by-step process, from frequency analysis to tree construction and code assignment. This chapter forms the heart of the book, providing a detailed explanation of how Huffman Coding works and why it's so effective. You'll gain insights into the algorithm's inner workings and develop an intuitive understanding of its mechanics.
In Chapter 3, "Data Structures for Huffman Coding," the focus shifts to the practical aspects of implementing Huffman Coding. This chapter explores the various data structures essential for efficient implementation, including binary trees, priority queues, and hash tables. You'll learn how these structures are used in Huffman Coding and gain valuable skills in manipulating complex data structures.
Chapter 4, "Implementing Huffman Coding," takes you through the process of translating the theoretical understanding into practical code. This hands-on chapter provides detailed guidance on implementing both the encoding and decoding processes, as well as addressing important considerations such as code serialization and error handling. By the end of this chapter, you'll have the skills to implement a fully functional Huffman Coding system.
Chapters 5 and 6 focus on the critical aspects of algorithm analysis. "Time Complexity Analysis of Huffman Coding" examines the efficiency of the algorithm in terms of computational time, while "Space Complexity and Memory Management" explores the memory requirements and optimization techniques. These chapters will equip you with the analytical tools to evaluate and optimize Huffman Coding implementations.
As you progress, Chapter 7, "Optimizing Huffman Coding," introduces advanced techniques to enhance the basic algorithm. You'll explore variations such as canonical Huffman codes, adaptive Huffman coding, and parallel implementations, broadening your understanding of how the core principles can be extended and improved.
Chapter 8, "Applications of Huffman Coding," bridges theory and practice by examining real-world uses of the algorithm. From file compression systems to data transmission in networks, this chapter illustrates the wide-ranging impact of Huffman Coding across various domains of computer science and engineering.
To provide context and comparison, Chapter 9, "Comparing Huffman Coding with Other Algorithms," examines how Huffman Coding stacks up against other compression techniques. This comparative analysis will deepen your understanding of the strengths and limitations of Huffman Coding and help you make informed decisions about when to apply it in your own work.
The book then moves into more specialized territory with Chapter 10, "Advanced Topics in Huffman Coding." Here, you'll explore cutting-edge research and developments in the field, including dynamic Huffman coding, length-limited codes, and the intersection of Huffman Coding with other advanced data structures like wavelet trees.
Chapter 11, "Practical Implementation Considerations," addresses the real-world challenges of working with Huffman Coding. This chapter covers important aspects such as choosing the right programming language, testing strategies, performance profiling, and dealing with scalability issues. The insights provided here will be invaluable as you move from theory to practical application in your projects.
To solidify your understanding and provide inspiration for potential applications, Chapter 12, "Real-World Examples and Case Studies," presents detailed examinations of Huffman Coding in action. From text compression in document management systems to its role in wireless communication protocols, these case studies offer a glimpse into the diverse ways Huffman Coding is applied in industry and research.
The main content of the book concludes with Chapter 13, "Future Directions and Research," which looks ahead to emerging trends and potential developments in the field. This forward-looking chapter explores topics such as quantum Huffman coding, the intersection of machine learning with adaptive compression, and the challenges of applying Huffman Coding in big data scenarios.
Following the main chapters, you'll find a comprehensive conclusion that summarizes key takeaways and reflects on the future of Huffman Coding. The book also includes a detailed glossary to help you quickly reference important terms and concepts, as well as a curated list of further reading materials to support your continued learning and exploration of the subject.
Throughout the book, you'll encounter numerous code examples, illustrations, and practical exercises designed to reinforce your learning and help you apply the concepts in real-world scenarios. Each chapter builds upon the previous ones, creating a cohesive narrative that takes you from novice to expert in Huffman Coding and its applications in optimizing time complexity and data compression.
By structuring the book in this way, the aim is to provide you with a comprehensive, practical, and engaging learning experience. Whether you're a student looking to deepen your understanding of algorithms and data structures, or a professional seeking to apply Huffman Coding in your work, this book is designed to meet your needs and elevate your expertise in this crucial area of computer science.
Prerequisites and Assumed Knowledge
Before embarking on your journey through "Mastering Huffman Coding," it's important to understand the foundational knowledge that will help you make the most of this book. While the content is designed to be accessible and comprehensive, having a solid grounding in certain areas of computer science will significantly enhance your learning experience and enable you to grasp the more advanced concepts more readily.
First and foremost, this book assumes an intermediate level of knowledge in algorithms and data structures. You should be comfortable with fundamental concepts such as Big O notation for analyzing time and space complexity, basic sorting and searching algorithms, and common data structures like arrays, linked lists, stacks, and queues. Familiarity with tree structures, particularly binary trees, is especially important given their central role in Huffman Coding. If you've taken an introductory course in algorithms or have practical experience implementing basic data structures, you should be well-prepared for the content in this book.
A strong foundation in programming is also essential. While the book doesn't focus on any specific programming language, the concepts and implementations discussed are often illustrated with code examples. These examples are typically presented in pseudocode or a C-like syntax for clarity and broad applicability. However, you should be able to translate these concepts into your preferred programming language. Proficiency in at least one high-level programming language (such as Python, Java, C++, or JavaScript) will be beneficial for understanding the implementation details and for completing the practical exercises provided throughout the book.
Basic knowledge of discrete mathematics and probability theory will also prove valuable. Huffman Coding relies on concepts from information theory, which in turn draws heavily from these mathematical disciplines. While the book provides explanations for key mathematical concepts as they arise, having a prior understanding of topics such as logarithms, probability distributions, and basic set theory will allow you to focus more on the application of these concepts to Huffman Coding rather than grappling with the mathematical foundations themselves.
Familiarity with binary number systems and bitwise operations is another area that will significantly aid your understanding. Huffman Coding often involves manipulating data at the bit level, so being comfortable with concepts like bit shifting, bitwise AND/OR operations, and binary-to-decimal conversions will be highly beneficial. If you're rusty in this area, don't worry – the book includes refreshers on these topics where necessary, but prior exposure will certainly smooth your learning path.
While not strictly necessary, some background in computer architecture and operating systems can provide helpful context, especially when discussing memory management and optimization techniques. Understanding how data is stored and accessed at the hardware level can give you deeper insights into why certain implementation choices are made in Huffman Coding and other compression algorithms.
It's also worth noting that while this book focuses primarily on Huffman Coding, having a general awareness of other compression techniques can provide valuable perspective. If you've encountered concepts like run-length encoding or are familiar with common compression formats like ZIP or JPEG, you'll find it easier to contextualize Huffman Coding within the broader landscape of data compression.
For those coming from a software development background, experience with version control systems (like Git) and familiarity with software testing practices will be helpful, particularly when working through the implementation chapters and considering real-world applications of Huffman Coding.
If you find that your knowledge in any of these areas is lacking, don't be discouraged. The book is designed to be self-contained and provides explanations and resources to help fill in any gaps in your knowledge. Each chapter builds on the previous ones, gradually introducing more complex concepts while reinforcing fundamental principles.
Additionally, the Further Reading section at the end of the book includes recommendations for supplementary materials that can help strengthen your understanding in these prerequisite areas. If you encounter concepts that are unfamiliar or challenging, these resources can serve as valuable references to support your learning journey.
Remember, learning is an iterative process. As you progress through the book, you may find it helpful to revisit earlier chapters or explore additional resources to reinforce your understanding. The goal is not just to learn about Huffman Coding in isolation, but to develop a holistic understanding of data compression and algorithm optimization within the broader context of computer science.
By starting with this foundation and remaining curious and persistent throughout your study of this book, you'll be well-equipped to master Huffman Coding and apply its principles to a wide range of computational challenges. The knowledge and skills you gain will not only deepen your understanding of this specific algorithm but will also enhance your overall capabilities as a computer scientist or software developer.
As you begin your journey through "Mastering Huffman Coding," approach the material with an open mind and a willingness to engage deeply with the concepts presented. The insights you gain here will serve you well not just in understanding this particular algorithm, but in developing a more sophisticated approach to problem-solving in computer science as a whole. Embrace the challenges, celebrate your progress, and remember that every step forward in your understanding brings you closer to mastering one of the most elegant and influential algorithms in the field of data compression.
This is the end of the free sample. The full book has 13 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Algorithm Analysis knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Algorithm Analysis book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Algorithm Analysis book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
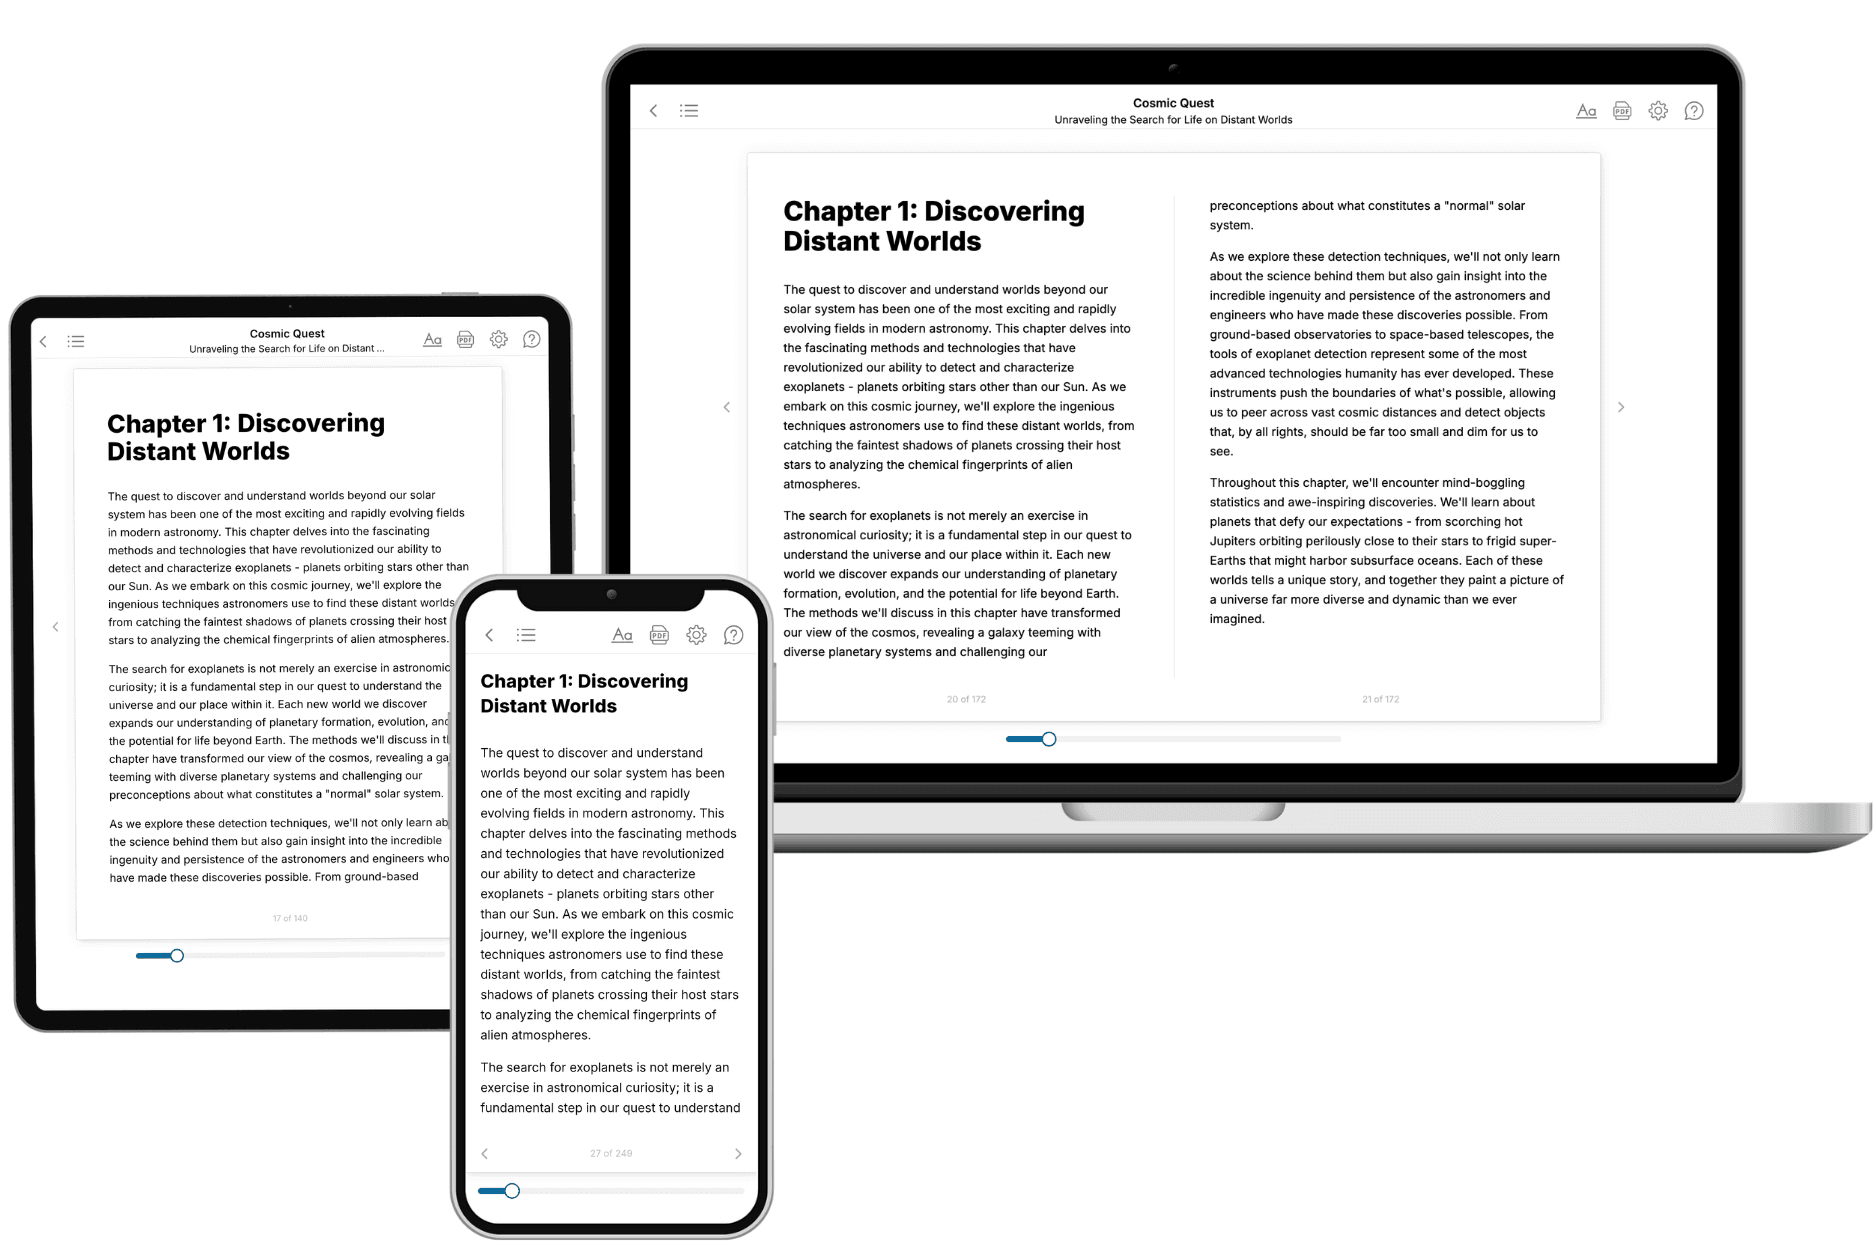
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.