Pinecone Search Mastery
Advanced Techniques for Optimizing Vector Databases and Semantic Search
Struggling to harness the full potential of vector search for your cutting-edge applications?
424 pages23 chaptersEnglishApr 20, 2025Software DevelopmentCreated by Chris
About this book
"Pinecone Search Mastery" is your ultimate guide to conquering the complexities of advanced search systems. This comprehensive resource delves deep into the intricacies of vector databases, offering you practical strategies to optimize query performance, enhance search accuracy, and scale your systems effortlessly. From mastering vector quantization and HNSW indexing to implementing sophisticated embedding pipelines and hybrid search models, this book covers every aspect of Pinecone's powerful capabilities. You'll gain hands-on experience with dimensionality reduction techniques, learn to fine-tune semantic embeddings, and discover how to balance recall and precision for optimal results. Whether you're looking to streamline your search APIs, implement multimodal indexing, or push the boundaries of query optimization, "Pinecone Search Mastery" equips you with the knowledge and tools to elevate your search systems to new heights. Get ready to transform your approach to vector search and unlock unprecedented levels of efficiency and accuracy in your data retrieval processes.
Table of contents
- IntroductionThe Importance of Vector Search in Modern Applications, Overview of Pinecone and Its Capabilities, How This Book Will Enhance Your Search Expertise, Prerequisites and Assumed KnowledgeRead below
- Chapter 1: Vector Database FundamentalsUnderstanding Vector Representations, Similarity Metrics and Distance Functions, Vector Indexing Techniques, Approximate Nearest Neighbor (ANN) Algorithms
- Chapter 2: Pinecone Architecture and Core ConceptsKey Components of Pinecone, Understanding Pinecone Index Types, Pinecone's Data Model and Schema, Overview of Pinecone's API
- Chapter 3: Vector Quantization TechniquesBasics of Vector Quantization, Product Quantization Methods, Scalar Quantization Approaches, Tradeoffs in Vector Quantization
- Chapter 4: HNSW Indexing in DepthConcept and Theory of HNSW, HNSW Index Construction, Search Algorithms in HNSW, Optimizing HNSW for Performance
- Chapter 5: Advanced Similarity MeasuresCosine Similarity in Detail, Euclidean Distance and Its Applications, Dot Product Similarity, Choosing the Right Similarity Measure
- Chapter 6: Dimensionality Reduction StrategiesPrincipal Component Analysis (PCA), t-SNE for Visualization, UMAP: Uniform Manifold Approximation and Projection, Autoencoders for Dimensionality Reduction
- Chapter 7: Working with Sparse VectorsSparse Vector Representations, Indexing Techniques for Sparse Vectors, Hybrid Search with Sparse and Dense Vectors, Optimizing Sparse Vector Operations
- Chapter 8: Query Expansion and RewritingSynonym-based Query Expansion, Contextual Query Expansion, Query Reformulation Techniques, Avoiding Pitfalls in Query Expansion
- Chapter 9: Building Robust Embedding PipelinesText Embedding Techniques, Image Embedding Strategies, Multimodal Embedding Approaches, Optimizing Embedding Pipelines
- Chapter 10: Vector Compression TechniquesScalar Quantization for Compression, Product Quantization Compression, Lossless Compression Methods, Balancing Compression and Accuracy
- Chapter 11: Fine-tuning Semantic EmbeddingsLeveraging Pre-trained Models, Domain-specific Adaptation, Contrastive Learning for Embeddings, Evaluating Embedding Quality
- Chapter 12: Index Sharding and DistributionSharding Strategies for Large Datasets, Implementing Distributed Search, Load Balancing in Distributed Indexes, Managing Consistency Across Shards
- Chapter 13: Advanced Query VectorizationQuery Understanding and Intent Recognition, Context-aware Query Vectorization, Handling Multi-vector Queries, Optimizing Query Vectors for Performance
- Chapter 14: Effective Metadata FilteringDesigning Efficient Metadata Schemas, Optimizing Filter Operations, Combining Filters with Vector Search, Implementing Dynamic Filtering
- Chapter 15: Balancing Recall and PrecisionUnderstanding the Recall-Precision Tradeoff, Tuning Search Parameters for High Recall, Strategies for Improving Precision, Metrics for Evaluating Search Quality
- Chapter 16: Vector Normalization TechniquesL2 Normalization and Its Impact, Alternative Normalization Methods, When and Why to Normalize Vectors, Avoiding Common Normalization Pitfalls
- Chapter 17: Multimodal Indexing StrategiesCreating Joint Embeddings for Multiple Modalities, Designing Modal-specific Indexes, Implementing Cross-modal Retrieval, Overcoming Challenges in Multimodal Search
- Chapter 18: Implementing Incremental UpdatesStrategies for Incremental Index Updates, Managing Consistency During Updates, Optimizing Update Performance, Achieving Real-time Indexing
- Chapter 19: Advanced Clustering TechniquesK-means Clustering for Vector Data, Hierarchical Clustering Approaches, Density-based Clustering with DBSCAN, Applications of Clustering in Search Systems
- Chapter 20: Vector Pruning StrategiesImportance-based Vector Pruning, Clustering-based Pruning Techniques, Adaptive Pruning Strategies, Evaluating the Impact of Pruning on Search Quality
- Chapter 21: Optimizing Query LatencyIndex Structure Optimization, Effective Caching Strategies, Optimizing Query Routing, Hardware Considerations for Low Latency
- Chapter 22: Advanced Relevance TuningIncorporating Multiple Relevance Signals, Implementing Personalized Relevance, Building Feedback Loops for Continuous Improvement, A/B Testing for Relevance Optimization
- Chapter 23: Designing Robust Search APIsBest Practices in Search API Design, Developing a Flexible Query Language, Effective Error Handling and Reporting, API Versioning and Backward Compatibility
- ConclusionFuture Trends in Vector Search, Strategies for Continuous Learning and Improvement
- AppendixPerformance Tuning Checklists, Troubleshooting Common Issues
- Glossary
Introduction
In the rapidly evolving landscape of data science and machine learning, the ability to efficiently search and retrieve information from vast datasets has become a critical challenge. As the volume and complexity of data continue to grow exponentially, traditional search methods are often found wanting, unable to capture the nuanced relationships and semantic meanings inherent in modern data structures. This is where vector search, and more specifically, Pinecone's advanced vector database technology, comes into play, revolutionizing the way we approach information retrieval and analysis.
Vector search represents a paradigm shift in how we conceptualize and implement search functionality. Unlike traditional keyword-based search methods, vector search operates in high-dimensional spaces, where data points are represented as vectors. These vectors capture not just the literal content of the data, but also its contextual and semantic properties. This approach allows for much more nuanced and accurate search results, capable of understanding similarities and relationships that would be impossible to discern through conventional means.
The power of vector search lies in its ability to understand and process complex, multidimensional data representations. In a world where machine learning models are increasingly used to generate rich, contextual embeddings of text, images, and other data types, vector search provides the means to efficiently query and retrieve information based on these sophisticated representations. This capability opens up a wide range of applications, from enhancing recommendation systems and content discovery platforms to powering advanced natural language processing tasks and computer vision applications.
However, with great power comes great complexity. Implementing and optimizing vector search systems at scale presents a unique set of challenges. These include managing high-dimensional data efficiently, handling the computational demands of similarity searches in large datasets, and maintaining search accuracy while optimizing for speed and resource utilization. It is in addressing these challenges that Pinecone has emerged as a leader, providing a robust, scalable, and highly optimized vector database solution.
The Importance of Vector Search in Modern Applications
The significance of vector search in modern applications cannot be overstated. As we move further into the era of big data and artificial intelligence, the ability to efficiently process and retrieve information from vast, complex datasets has become a critical differentiator for businesses and organizations across various sectors. Vector search is not just a technological advancement; it's a fundamental shift in how we interact with and derive value from data.
One of the primary reasons for the growing importance of vector search is its ability to capture and utilize semantic relationships within data. Traditional search methods, which rely heavily on exact matches or simple keyword relevance, often fall short when dealing with nuanced queries or content that requires understanding context. Vector search, on the other hand, operates on the principle of similarity in a high-dimensional space, allowing for much more sophisticated matching between queries and results. This capability is particularly crucial in natural language processing applications, where understanding the intent and context behind a query is often as important as the literal words used[1].
In the realm of recommendation systems, vector search has proven to be a game-changer. By representing user preferences, item characteristics, and contextual information as vectors, these systems can provide highly personalized and relevant recommendations. This level of personalization goes beyond simple collaborative filtering, taking into account complex relationships and similarities that would be difficult or impossible to capture with traditional methods. The result is a more engaging and satisfying user experience, which translates directly to increased user retention and conversion rates for businesses employing these technologies[2].
Another critical application of vector search is in the field of computer vision and image recognition. By converting images into high-dimensional vectors that capture their visual features, vector search enables efficient and accurate image retrieval and similarity matching. This technology powers a wide range of applications, from reverse image search engines to content moderation systems for social media platforms. The ability to quickly find visually similar images or identify specific objects within large image datasets has profound implications for industries ranging from e-commerce to healthcare[3].
In the financial sector, vector search is being leveraged for fraud detection and risk assessment. By representing transactions, user behaviors, and other relevant data points as vectors, financial institutions can more effectively identify anomalies and potential fraudulent activities. The high-dimensional nature of vector representations allows for the capture of subtle patterns and relationships that might be missed by traditional rule-based systems, leading to more accurate and timely detection of suspicious activities[4].
The importance of vector search extends to the realm of scientific research and discovery as well. In fields such as genomics and drug discovery, vector search techniques are being used to analyze vast databases of molecular structures and genetic sequences. By representing complex biological data as vectors, researchers can more efficiently search for similar compounds or genetic patterns, potentially accelerating the discovery of new drugs or the understanding of genetic diseases[5].
As the volume and complexity of data continue to grow exponentially, the importance of vector search in enabling efficient and effective information retrieval and analysis will only increase. Organizations that can effectively leverage this technology will have a significant advantage in their ability to derive insights, make decisions, and create value from their data assets. The scalability and performance offered by specialized vector database solutions like Pinecone are crucial in realizing the full potential of vector search across these diverse and demanding applications.
Overview of Pinecone and Its Capabilities
Pinecone stands at the forefront of vector database technology, offering a powerful and scalable solution designed to meet the demanding requirements of modern vector search applications. As a purpose-built vector database, Pinecone provides a comprehensive set of features and capabilities that enable developers and data scientists to implement high-performance vector search systems with ease and efficiency. This section provides an overview of Pinecone's key capabilities and the advantages it offers over traditional database solutions.
At its core, Pinecone is engineered to handle the unique challenges posed by high-dimensional vector data. Unlike traditional relational databases or even document-oriented NoSQL systems, Pinecone is optimized for the storage, indexing, and retrieval of vector embeddings. This specialization allows Pinecone to achieve remarkable performance in similarity search operations, which are the foundation of many modern machine learning and AI applications. The system employs advanced indexing techniques, such as Hierarchical Navigable Small World (HNSW) graphs, to enable fast and accurate nearest neighbor searches in high-dimensional spaces[6].
One of Pinecone's standout features is its ability to scale seamlessly to handle massive datasets. The distributed architecture of Pinecone allows it to manage billions of vectors across multiple nodes, ensuring high availability and consistent performance even as data volumes grow. This scalability is crucial for applications that need to handle large and growing datasets, such as recommendation systems for e-commerce platforms or content discovery engines for streaming services. Pinecone's ability to distribute indexes across multiple shards and replicate data for fault tolerance ensures that vector search operations remain fast and reliable, even under high load conditions.
Pinecone also excels in its support for real-time updates and queries. Unlike some vector search solutions that require periodic rebuilding of indexes, Pinecone allows for dynamic updates to the vector database. This capability is essential for applications that need to continuously ingest new data or update existing vectors. For instance, in a news recommendation system, the ability to quickly index and make searchable new articles as they are published is crucial for maintaining the relevance and timeliness of recommendations. Pinecone's architecture ensures that such updates can be performed with minimal impact on query performance, maintaining low latency even as the database evolves.
Another key capability of Pinecone is its support for hybrid search, which combines the power of vector similarity search with traditional metadata filtering. This feature allows developers to create more sophisticated search queries that take into account both semantic similarity (represented by vector embeddings) and structured metadata attributes. For example, in an e-commerce application, this could enable searches that consider both the visual similarity of products (represented as image embeddings) and specific product attributes like price range or brand. The ability to seamlessly integrate these different types of search criteria provides a level of flexibility and precision that is difficult to achieve with traditional search technologies.
Pinecone also offers robust support for multi-vector queries, allowing for complex search operations that involve multiple query vectors. This capability is particularly useful in scenarios where a single vector may not be sufficient to capture the full context or intent of a query. For instance, in a multimodal search system that combines text and image inputs, Pinecone can efficiently process queries that involve both text embeddings and image embeddings, returning results that are relevant across multiple dimensions of similarity.
From a developer perspective, Pinecone provides a user-friendly API that abstracts away much of the complexity involved in managing a vector database. The API offers intuitive operations for inserting, updating, and querying vector data, as well as for managing indexes and performing administrative tasks. This ease of use significantly reduces the learning curve and development time required to implement vector search functionality, allowing developers to focus on building innovative applications rather than wrestling with low-level database operations.
Security and compliance are also key considerations in Pinecone's design. The platform offers features such as encryption at rest and in transit, access control mechanisms, and compliance with various data protection regulations. These security measures ensure that sensitive data stored as vector embeddings remains protected, making Pinecone suitable for use in industries with strict data privacy requirements, such as healthcare or finance.
In summary, Pinecone represents a comprehensive solution for vector search, offering a unique combination of performance, scalability, flexibility, and ease of use. Its capabilities address the key challenges faced in implementing vector search at scale, making it a powerful tool for developers and organizations looking to leverage the full potential of vector embeddings in their applications. As we delve deeper into the specific techniques and optimizations in the following chapters, the foundational role of Pinecone in enabling advanced vector search applications will become increasingly apparent.
How This Book Will Enhance Your Search Expertise
"Pinecone Search Mastery: Advanced Techniques for Optimizing Vector Databases and Semantic Search" is designed to be your comprehensive guide to mastering the intricacies of vector search and harnessing the full potential of Pinecone's powerful vector database technology. This book is structured to take you on a journey from the fundamental concepts of vector search to the most advanced techniques for optimizing and scaling vector search systems. Whether you're looking to implement cutting-edge semantic search solutions, enhance the accuracy and performance of your existing search applications, or push the boundaries of what's possible with vector databases, this book will equip you with the knowledge and skills you need.
The book is organized into a logical progression of topics, each building upon the last to create a comprehensive understanding of vector search and Pinecone's capabilities. We begin with the foundational concepts, ensuring that you have a solid grasp of vector representations, similarity metrics, and the basic principles of vector indexing. From there, we delve into the architecture and core concepts of Pinecone, providing you with a deep understanding of how this powerful vector database is structured and how it can be leveraged to its full potential.
As we progress, you'll explore advanced topics such as vector quantization techniques, HNSW indexing, and sophisticated similarity measures. These chapters will give you the theoretical background and practical insights needed to make informed decisions about how to structure and optimize your vector search systems. You'll learn how to balance trade-offs between search accuracy, speed, and resource utilization, and how to choose the right approaches for your specific use cases.
A significant portion of the book is dedicated to practical optimization strategies. You'll learn techniques for dimensionality reduction, working with sparse vectors, and implementing hybrid search models that combine the strengths of both sparse and dense vector representations. These chapters will provide you with a toolkit of approaches for enhancing the efficiency and effectiveness of your search systems, allowing you to handle larger datasets and more complex queries with ease.
The book also covers advanced topics such as query expansion and rewriting, building robust embedding pipelines, and fine-tuning semantic embeddings. These chapters will help you enhance the relevance and recall of your search results, ensuring that your applications can understand and respond to user intent with unprecedented accuracy. You'll learn how to implement sophisticated techniques like contextual query expansion and contrastive learning for embeddings, pushing the boundaries of what's possible with semantic search.
Scalability is a critical concern for many search applications, and this book addresses it head-on. You'll explore techniques for index sharding and distribution, allowing you to scale your vector search systems to handle massive datasets. The book covers strategies for implementing distributed search, load balancing, and managing consistency across shards, giving you the tools you need to build robust, high-performance search systems that can grow with your data.
Throughout the book, we emphasize practical, actionable advice. Each chapter includes concrete examples, code snippets, and best practices that you can apply directly to your own projects. We'll explore real-world use cases and scenarios, helping you understand how to apply these advanced techniques in practical situations. Whether you're working on a recommendation system, a content discovery platform, or a sophisticated data analysis tool, you'll find relevant examples and insights that you can adapt to your specific needs.
The book also addresses critical aspects of search system design and maintenance, such as balancing recall and precision, implementing effective metadata filtering, and designing robust search APIs. You'll learn strategies for continuous monitoring and tuning of your search systems, ensuring that they maintain peak performance even as your data and user needs evolve.
By the time you reach the conclusion of this book, you'll have a comprehensive understanding of vector search technology and Pinecone's capabilities. You'll be equipped with the knowledge and skills to implement state-of-the-art semantic search solutions, optimize your vector databases for maximum performance, and tackle even the most challenging search problems with confidence.
Whether you're an experienced data scientist looking to stay at the cutting edge of search technology, or a machine learning engineer seeking to master the intricacies of vector databases, "Pinecone Search Mastery" will be your definitive guide. This book will not only enhance your search expertise but also empower you to push the boundaries of what's possible with vector search, enabling you to create more intelligent, efficient, and user-friendly applications that can derive unprecedented value from your data.
Prerequisites and Assumed Knowledge
To fully benefit from the advanced concepts and techniques presented in "Pinecone Search Mastery," readers are expected to have a solid foundation in certain areas of data science, machine learning, and software engineering. While the book strives to explain complex topics in a clear and accessible manner, having prior knowledge in specific domains will greatly enhance your ability to understand and apply the advanced techniques discussed. This section outlines the key prerequisites and assumed knowledge for readers of this book.
First and foremost, a strong background in linear algebra is essential. Vector search fundamentally operates in high-dimensional spaces, and many of the concepts and optimizations we'll discuss rely heavily on linear algebraic principles. You should be comfortable with concepts such as vector operations, matrix multiplication, eigenvalues and eigenvectors, and dimensionality reduction techniques like Principal Component Analysis (PCA). Familiarity with the mathematical foundations of distance metrics in vector spaces, such as Euclidean distance and cosine similarity, is also crucial[7].
A solid understanding of probability theory and statistics is another important prerequisite. Many of the algorithms and techniques used in vector search, particularly those related to approximate nearest neighbor search and probabilistic data structures, rely on statistical concepts. Familiarity with probability distributions, statistical sampling methods, and basic concepts of information theory will be beneficial. Additionally, an understanding of statistical measures of search quality, such as precision, recall, and mean average precision (MAP), is important for evaluating and optimizing search systems[8].
Proficiency in at least one programming language commonly used in data science and machine learning is assumed. While the book doesn't focus on any specific programming language, many examples and concepts will be easier to grasp if you have experience with languages such as Python, R, or Julia. Familiarity with scientific computing libraries like NumPy and SciPy, as well as machine learning frameworks such as TensorFlow or PyTorch, will be particularly helpful. Additionally, basic knowledge of software engineering principles, including data structures, algorithms, and API design, is expected.
A foundational understanding of machine learning concepts is crucial. You should be familiar with the basics of supervised and unsupervised learning, including common algorithms like k-means clustering, neural networks, and gradient descent optimization. Knowledge of deep learning architectures, particularly those used for generating embeddings (such as transformers for text or convolutional neural networks for images), will be beneficial. Familiarity with the concept of embeddings and their role in representing high-dimensional data in dense vector spaces is especially important[9].
Experience with database systems and information retrieval concepts is also assumed. While Pinecone offers a specialized solution for vector search, understanding the principles of traditional database management systems, including indexing strategies and query optimization, will provide valuable context. Familiarity with information retrieval concepts such as inverted indexes, TF-IDF, and relevance ranking will help in understanding the advantages and challenges of vector-based approaches compared to traditional text search methods.
Knowledge of distributed systems concepts is beneficial, particularly for the sections dealing with scaling and distributing vector search systems. Understanding concepts such as sharding, load balancing, consistency models, and distributed query processing will help you grasp the challenges and solutions involved in building large-scale vector search applications. Familiarity with cloud computing platforms and containerization technologies like Docker can also be helpful, as these are often used in deploying and scaling vector search systems.
While not strictly necessary, exposure to natural language processing (NLP) and computer vision can provide valuable context for many of the applications and examples discussed in the book. Understanding concepts like word embeddings, sentence encoders, and image feature extraction can help you better appreciate the power and flexibility of vector search in these domains.
Lastly, a general understanding of the challenges and requirements of modern search and recommendation systems is assumed. This includes awareness of issues such as scalability, real-time updates, personalization, and the importance of relevance in search results. Experience with or exposure to large-scale data processing frameworks like Apache Spark or Hadoop can also be beneficial, as these are often used in conjunction with vector search systems for data preparation and processing.
While this list of prerequisites might seem extensive, it's important to note that the book is designed to be accessible to a wide range of readers with varying levels of expertise. Each chapter builds on the concepts introduced in previous sections, and efforts are made to explain complex topics clearly. If you find that you're lacking in some of these areas, don't be discouraged. The book can serve as a motivation to deepen your knowledge in these foundational areas as you explore the exciting world of vector search and Pinecone's capabilities.
Notes
Introduction
- 1. D. Cer and others, Universal sentence encoder. arXiv preprint arXiv:1803.11175, 2018
- 2. M. Grbovic and H. Cheng, "Real-time personalization using embeddings for search ranking at Airbnb," Proceedings of the 24th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining (), 2018
- 3. J. Johnson and others, "Billion-scale similarity search with GPUs," IEEE Transactions on Big Data, 2019
- 4. A. Abdallah and others, "Fraud detection system: A survey," Journal of Network and Computer Applications, 2016
- 5. A. Aliper and others, "Deep learning applications for predicting pharmacological properties of drugs and drug repurposing using transcriptomic data," Molecular pharmaceutics, 2016
- 6. Y. A. Malkov and D. A. Yashunin, "Efficient and robust approximate nearest neighbor search using hierarchical navigable small world graphs," IEEE transactions on pattern analysis and machine intelligence, 2018
- 7. G. Strang, Introduction to linear algebra (Vol. 5), Wellesley, MA: Wellesley-Cambridge Press, 2016
- 8. L. Wasserman, "All of statistics," Springer Science & Business Media, 2013
- 9. I. Goodfellow and others, Deep learning, MIT press, 2016
This is the end of the free sample. The full book has 23 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Software Development knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Software Development book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Software Development book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
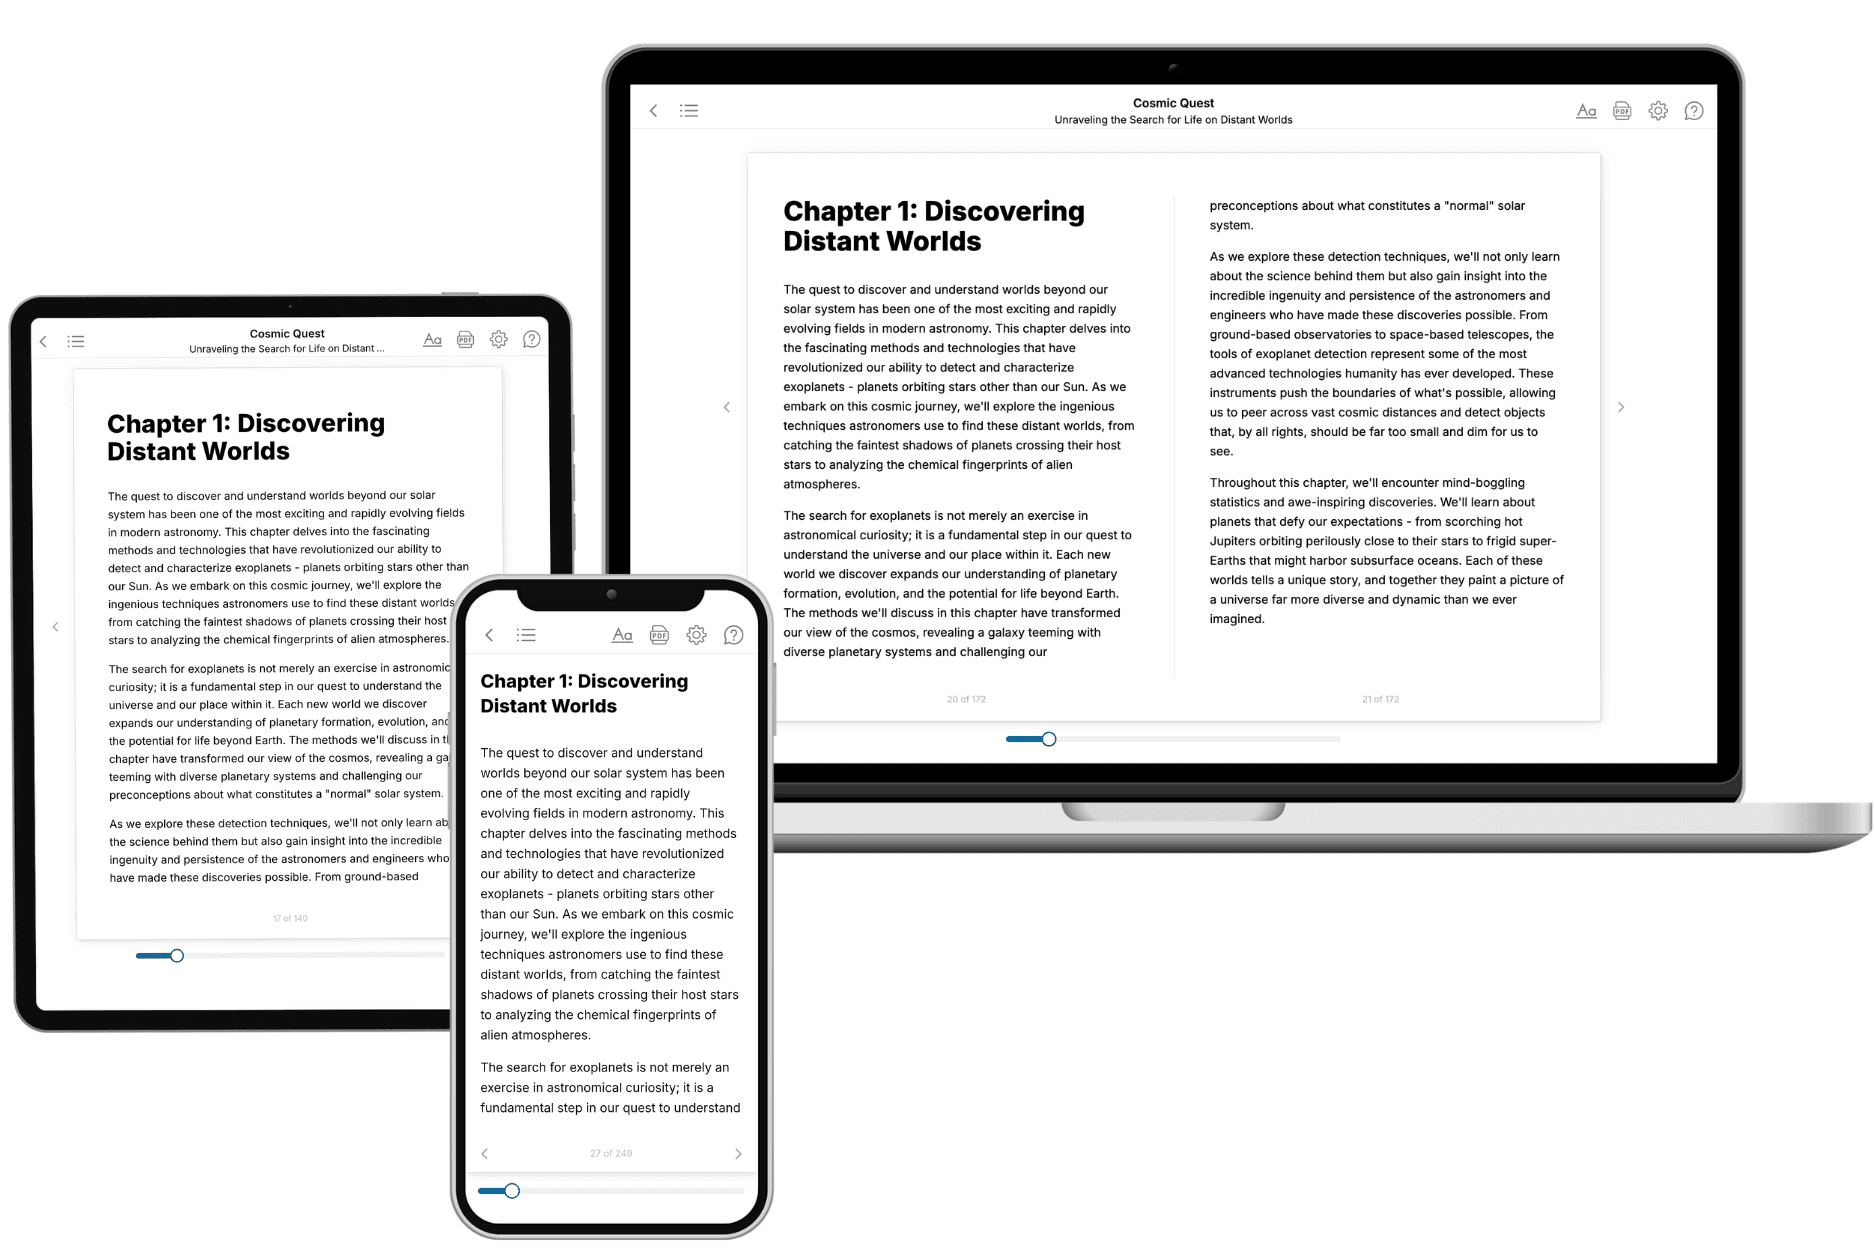
- 3. Get your tailored book
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.