Ray on Kubernetes
Mastering Distributed Machine Learning at Scale
Are you ready to revolutionize your machine learning workflows?
253 pages14 chaptersMay 3, 2025Distributed SystemsCreated by Chris
About this book
Ray on Kubernetes: Mastering Distributed Machine Learning at Scale is your comprehensive guide to harnessing the power of distributed computing for advanced machine learning applications. This book delves deep into the intricacies of combining Ray, a powerful distributed computing framework, with Kubernetes, the industry-standard container orchestration platform. You'll discover how to optimize your ML pipelines, scale your training processes, and streamline your deployments. From distributed hyperparameter tuning to efficient model serving, this book covers the entire spectrum of ML operations on a distributed infrastructure. Packed with practical examples and best practices, you'll learn how to design fault-tolerant systems, implement advanced monitoring techniques, and leverage custom resources for your specific ML needs. Whether you're looking to accelerate your model training, enhance your data processing capabilities, or build robust ML architectures, this book provides the knowledge and tools you need to excel. By the end of this journey, you'll have mastered the art of distributed machine learning, enabling you to tackle complex ML challenges with confidence and efficiency. Get ready to elevate your ML game to unprecedented heights with Ray on Kubernetes.
Table of contents
- IntroductionThe Need for Distributed Machine Learning, Ray: A Framework for Distributed Computing, Kubernetes: Container Orchestration for ML, Book Structure and How to Use ItRead below
- Chapter 1: Foundations of Ray and KubernetesRay Architecture and Core Concepts, Kubernetes Components for ML Workloads, Synergies Between Ray and Kubernetes, Setting Up Your Development Environment
- Chapter 2: Resource Management and AllocationUnderstanding Kubernetes Resource Types, Ray Cluster Resource Management, Efficient Resource Allocation Strategies, Implementing Autoscaling for ML Workloads
- Chapter 3: Distributed Training TechniquesData Parallelism with Ray, Model Parallelism Strategies, Distributed SGD Implementation, Leveraging the Ray Train API
- Chapter 4: Hyperparameter Optimization at ScaleIntroduction to Ray Tune, Search Algorithms for Hyperparameter Tuning, Distributed Hyperopt with Ray, Integrating Hyperparameter Tuning with Kubernetes
- Chapter 5: Distributed Data ProcessingWorking with Ray Datasets, Efficient Data Ingestion Techniques, Distributed Data Preprocessing, Scalable Feature Engineering
- Chapter 6: Building ML PipelinesDesigning ML Pipeline Components, Ray Workflow for Pipeline Orchestration, Kubernetes Operators for ML Pipelines, Monitoring and Debugging Pipelines
- Chapter 7: Model Serving and InferenceIntroduction to Ray Serve, Model Deployment Strategies, Scaling Inference Services, Integrating Ray Serve with Kubernetes
- Chapter 8: Distributed Reinforcement LearningIntroduction to Ray RLlib, Implementing RL Algorithms with RLlib, Scaling RL Environments on Kubernetes, Distributed Training for RL Models
- Chapter 9: Monitoring and DebuggingUtilizing the Ray Dashboard, Kubernetes Monitoring for ML Workloads, Implementing Distributed Logging, Advanced Debugging Techniques
- Chapter 10: Fault Tolerance and High AvailabilityRay's Fault Tolerance Mechanisms, Kubernetes Resilience Features, Implementing Checkpointing Strategies, Designing Recovery Mechanisms
- Chapter 11: Security ConsiderationsKubernetes Security Best Practices, Securing Ray Clusters, Implementing Network Policies, Managing Secrets in ML Workflows
- Chapter 12: Advanced Topics and OptimizationsLeveraging Kubernetes Custom Resources, GPU Optimization Techniques, Distributed TensorFlow with Ray, PyTorch Integration and Best Practices
- Chapter 13: Real-world Case StudiesLarge-scale NLP Model Training, Distributed Computer Vision Pipeline, Building a Scalable Recommendation System, Time Series Forecasting at Scale
- Chapter 14: Future Trends and ConclusionEmerging Technologies in Distributed ML, Ray Ecosystem Roadmap, Evolution of Kubernetes for ML, Final Thoughts and Next Steps
- AppendixRay Cheat Sheet, Essential Kubernetes Commands for ML
Introduction
Welcome to the cutting-edge world of distributed machine learning with Ray on Kubernetes. As you embark on this journey to master advanced machine learning techniques, you're about to discover how the synergy between Ray and Kubernetes can revolutionize your approach to building scalable, efficient, and robust ML systems. This introduction will set the stage for your exploration, providing a comprehensive overview of the challenges in modern machine learning that necessitate distributed computing solutions, an introduction to Ray as a powerful framework for distributed computing, and a primer on Kubernetes as the industry-standard container orchestration platform for managing complex ML workloads.
The landscape of machine learning is evolving at an unprecedented pace. As models become more complex, datasets grow larger, and the demand for real-time predictions increases, the limitations of traditional computing approaches become increasingly apparent. The need for distributed systems that can harness the power of multiple machines working in concert has never been more critical. This book is designed to equip you with the knowledge and skills to navigate this new terrain, leveraging the combined strengths of Ray and Kubernetes to build ML systems that can scale to meet the demands of even the most ambitious projects.
Throughout this book, you'll delve into practical examples, best practices, and advanced techniques that will enable you to design, implement, and optimize distributed ML workflows. From efficient resource allocation and distributed training to hyperparameter tuning at scale and robust model serving, each chapter will build upon the last, providing you with a comprehensive toolkit for tackling real-world ML challenges. By the end of this journey, you'll have gained not just theoretical knowledge, but hands-on experience in creating ML infrastructures that can handle the complexities of modern data science and AI applications.
As we progress through the chapters, you'll discover how to overcome common bottlenecks in ML pipelines, implement fault-tolerant systems, and leverage advanced monitoring techniques to ensure the health and performance of your distributed applications. Whether you're looking to accelerate model training times, enhance data processing capabilities, or build more responsive and scalable ML services, the combination of Ray and Kubernetes offers a powerful solution that this book will help you master.
So, prepare to elevate your ML game to unprecedented heights. The world of distributed machine learning awaits, and with Ray on Kubernetes as your guide, you're about to embark on an exciting journey that will transform the way you approach large-scale ML problems. Let's begin by exploring the fundamental concepts and motivations behind distributed machine learning, setting the stage for the advanced techniques and architectures we'll be exploring throughout this book.
The Need for Distributed Machine Learning
In the rapidly evolving landscape of machine learning and artificial intelligence, the demand for more sophisticated models, larger datasets, and faster processing has outpaced the capabilities of traditional computing paradigms. This exponential growth in complexity and scale has given rise to distributed machine learning, a paradigm shift that addresses the limitations of single-machine processing and opens up new possibilities for tackling previously intractable problems. The need for distributed ML stems from several key factors that have become increasingly prominent in recent years.
First and foremost is the sheer volume of data that modern ML applications must process. With the advent of big data, datasets have grown from gigabytes to terabytes and even petabytes in size. This explosion in data volume presents both an opportunity and a challenge. On one hand, larger datasets can lead to more accurate models and deeper insights. On the other hand, processing such vast amounts of data on a single machine becomes impractical, if not impossible, due to memory limitations and processing time constraints. Distributed ML addresses this challenge by enabling data to be split across multiple machines, allowing for parallel processing and significantly reducing the time required to train models on large datasets.
Secondly, the complexity of ML models has increased dramatically. Deep learning models, in particular, have grown from simple neural networks with a few layers to massive architectures with billions of parameters. Training these models requires enormous computational resources that far exceed the capabilities of even the most powerful single machines. Distributed ML allows these complex models to be split across multiple GPUs or even multiple machines, enabling training that would otherwise be infeasible. This capability has been crucial in advancing fields such as natural language processing, computer vision, and reinforcement learning, where state-of-the-art models often require distributed training to achieve their impressive results.
Another driving factor behind the need for distributed ML is the increasing demand for real-time or near-real-time predictions in production environments. Many modern applications, from recommendation systems to autonomous vehicles, require ML models to make predictions with extremely low latency. Distributed ML architectures enable these systems to scale horizontally, distributing the inference workload across multiple machines to handle high volumes of requests concurrently. This scalability is essential for maintaining performance under varying loads and ensuring that ML-powered applications can meet the demands of their users.
The need for faster experimentation and iteration in ML research and development has also contributed to the rise of distributed ML. In competitive industries and research environments, the ability to quickly test hypotheses, tune hyperparameters, and evaluate model performance can be a significant advantage. Distributed ML frameworks enable parallel experimentation, allowing data scientists and researchers to explore multiple model configurations simultaneously and accelerate the pace of innovation. This capability is particularly valuable in fields where the state of the art is advancing rapidly, and staying ahead of the curve requires constant iteration and improvement.
Furthermore, the increasing complexity of ML workflows has necessitated more sophisticated orchestration and management tools. Modern ML pipelines often involve multiple stages, from data preprocessing and feature engineering to model training, evaluation, and deployment. Managing these complex workflows across distributed resources requires specialized tools and frameworks that can handle task scheduling, resource allocation, and fault tolerance. Distributed ML platforms provide the infrastructure to manage these workflows efficiently, ensuring that resources are used optimally and that failures in one part of the system don't compromise the entire pipeline.
The need for reproducibility and collaboration in ML projects has also driven the adoption of distributed ML practices. As ML models become more complex and are developed by larger teams, ensuring that experiments can be reproduced and that different components of a system can be developed independently becomes crucial. Distributed ML frameworks often provide tools for versioning, tracking experiments, and managing dependencies, facilitating collaboration among team members and ensuring that results can be reliably reproduced across different environments.
Additionally, the heterogeneity of computing resources in modern ML environments has made distributed computing approaches increasingly necessary. Many organizations have a mix of CPUs, GPUs, and specialized AI accelerators spread across on-premises data centers and cloud environments. Distributed ML frameworks provide the flexibility to leverage these diverse resources effectively, allowing organizations to make the most of their existing infrastructure while also taking advantage of cloud resources for burst capacity or specialized hardware.
The economic considerations of scaling ML operations have also played a role in driving the adoption of distributed ML. While the cost of computing resources has generally decreased over time, the computational requirements of state-of-the-art ML models have grown even faster. Distributed ML offers a way to manage these costs more effectively by enabling more efficient resource utilization and providing the flexibility to scale resources up or down based on demand. This elasticity is particularly valuable in cloud environments, where organizations can avoid the capital expenses associated with building and maintaining large-scale on-premises infrastructure.
Lastly, the increasing importance of edge computing in ML applications has created new challenges that distributed ML is uniquely positioned to address. As more ML models are deployed on edge devices, from smartphones to IoT sensors, there's a growing need for frameworks that can manage the distribution of models, coordinate training across edge devices, and aggregate insights from distributed data sources. Distributed ML provides the tools and architectures to build these edge-to-cloud ML systems, enabling new applications that can leverage the power of ML while respecting privacy constraints and minimizing data transfer.
In conclusion, the need for distributed machine learning has arisen from a confluence of factors: the growth in data volume and model complexity, the demand for real-time processing and low-latency predictions, the need for faster experimentation and iteration, the complexity of modern ML workflows, the importance of reproducibility and collaboration, the heterogeneity of computing resources, economic considerations, and the rise of edge computing. As these trends continue to shape the field of machine learning, distributed approaches will become increasingly essential for organizations and researchers looking to push the boundaries of what's possible with ML. The following sections will introduce you to Ray and Kubernetes, two powerful tools that, when combined, provide a robust foundation for building distributed ML systems that can address these challenges and unlock new possibilities in the world of AI and data science.
Ray: A Framework for Distributed Computing
Ray stands at the forefront of distributed computing frameworks, offering a powerful and flexible solution for scaling machine learning workloads across clusters of machines. Developed at the University of California, Berkeley, Ray was designed from the ground up to address the unique challenges of distributed computing in the context of machine learning and artificial intelligence. Its architecture and features make it an ideal choice for building and deploying large-scale ML applications, from complex training pipelines to real-time serving systems.
At its core, Ray provides a unified interface for distributed computing that abstracts away much of the complexity typically associated with writing distributed applications. This abstraction allows developers to write code that can seamlessly scale from running on a single machine to running across a cluster of hundreds or thousands of nodes. Ray achieves this through a combination of a distributed task scheduler, a distributed object store, and a set of libraries tailored for common ML tasks.
One of Ray's key strengths is its ability to handle both task-parallel and actor-based computations. Task-parallel computations are ideal for embarrassingly parallel workloads, where a large number of independent tasks can be executed concurrently. This is particularly useful for data preprocessing, feature engineering, and certain types of model training. Actor-based computations, on the other hand, allow for stateful computations and are well-suited for implementing complex algorithms or managing shared resources across a distributed system. This dual model of computation gives Ray the flexibility to efficiently handle a wide range of ML workloads.
Ray's distributed object store is another critical component that sets it apart from other distributed computing frameworks. The object store allows for efficient sharing of large datasets and model parameters across nodes in a cluster. It uses a combination of shared memory and distributed memory to minimize data transfer and maximize performance. This is particularly important in ML workloads, where large datasets and model parameters often need to be accessed by multiple workers simultaneously.
One of the most powerful features of Ray is its ecosystem of libraries built on top of its core distributed computing framework. These libraries address specific needs in the ML workflow and include:
- Ray Tune: A library for distributed hyperparameter tuning, which allows data scientists to efficiently search large hyperparameter spaces across multiple machines.
- Ray Train: A library for distributed model training, supporting popular ML frameworks like TensorFlow, PyTorch, and scikit-learn.
- Ray Serve: A scalable model serving library that allows for easy deployment of ML models as REST APIs or gRPC services.
- Ray RLlib: A library for reinforcement learning that provides a collection of RL algorithms and environments that can be easily scaled across a cluster.
- Ray Datasets: A library for distributed data processing, enabling efficient handling of large datasets across a cluster.
Ray's architecture is designed with fault tolerance in mind, a critical feature for long-running distributed ML workloads. The system can automatically recover from node failures, restarting tasks and reconstructing lost objects as necessary. This resilience ensures that ML experiments and production workloads can continue running even in the face of hardware failures or other issues that might arise in a distributed environment.
Another significant advantage of Ray is its support for heterogeneous computing resources. Ray can efficiently utilize a mix of CPUs and GPUs, and even specialized AI accelerators, allocating tasks to the most appropriate hardware based on their requirements. This flexibility is particularly valuable in modern ML environments, where different stages of a pipeline may have very different computational needs.
Ray also provides robust support for dynamic scaling, allowing clusters to grow or shrink based on workload demands. This elasticity is especially useful in cloud environments, where it can lead to significant cost savings by ensuring that resources are only used when needed. Ray's autoscaler can work with various cloud providers and cluster managers, including Kubernetes, which we'll explore in more detail later in this book.
The performance characteristics of Ray make it particularly well-suited for ML workloads. Its low-latency task scheduling and efficient data sharing mechanisms enable it to handle the fine-grained parallelism often required in ML applications. This allows for efficient implementation of complex algorithms like distributed SGD, asynchronous parameter servers, and population-based training.
Ray's Python API is another factor contributing to its popularity in the ML community. Python has become the de facto language for many data science and ML applications, and Ray's seamless integration with the Python ecosystem allows developers to leverage their existing skills and tools. This integration extends to popular ML libraries like NumPy, Pandas, scikit-learn, TensorFlow, and PyTorch, making it easy to incorporate Ray into existing ML workflows.
The extensibility of Ray is worth noting as well. Its modular design allows developers to create custom task schedulers, object stores, and other components to suit specific needs. This extensibility has led to a growing ecosystem of third-party libraries and tools built on top of Ray, further expanding its capabilities and applicability to a wide range of ML problems.
As we delve deeper into Ray throughout this book, you'll gain hands-on experience with its various components and learn how to leverage its capabilities to build scalable ML systems. From distributed training and hyperparameter tuning to building robust serving architectures, Ray will serve as a foundational tool in your journey to mastering distributed machine learning. In the next section, we'll introduce Kubernetes, the container orchestration platform that complements Ray's distributed computing capabilities, providing a robust infrastructure for deploying and managing Ray clusters at scale.
Kubernetes: Container Orchestration for ML
Kubernetes has emerged as the de facto standard for container orchestration, playing a crucial role in the deployment and management of distributed systems, including machine learning workloads. Originally developed by Google and now maintained by the Cloud Native Computing Foundation, Kubernetes provides a robust platform for automating the deployment, scaling, and management of containerized applications. Its features and architecture make it an ideal complement to Ray for building scalable and resilient ML infrastructures.
At its core, Kubernetes is designed to abstract away the complexities of managing a distributed system, allowing developers and operators to focus on defining the desired state of their applications rather than the nitty-gritty details of how to achieve that state. This declarative approach to system management aligns well with the needs of ML workflows, which often require complex orchestration of multiple components, from data preprocessing and model training to serving and monitoring.
One of the key concepts in Kubernetes is the pod, which is the smallest deployable unit in the Kubernetes ecosystem. A pod can contain one or more containers that are guaranteed to be co-located on the same host machine and can share resources. This concept maps well to ML workloads, where you might have a primary container running a Ray worker or server, along with sidecar containers for logging, monitoring, or specialized ML tasks.
Kubernetes provides several abstractions that are particularly useful for ML workloads:
- Deployments: Allow you to declaratively define the desired state of your application, including the number of replicas, update strategy, and resource requirements. This is useful for managing stateless components of ML pipelines, such as preprocessing workers or inference servers.
- StatefulSets: Provide guarantees about the ordering and uniqueness of pods, which is crucial for stateful applications like distributed databases or parameter servers in ML systems.
- Jobs and CronJobs: Enable the execution of batch processes and scheduled tasks, which are often used in ML pipelines for data ingestion, periodic model retraining, or evaluation tasks.
- Services: Provide stable network endpoints for accessing pods, allowing for easy load balancing and service discovery within the cluster. This is essential for building scalable ML serving architectures.
- ConfigMaps and Secrets: Allow for the separation of configuration from code, enabling easy management of environment-specific settings and sensitive information like API keys or database credentials.
Kubernetes' scheduling capabilities are particularly relevant for ML workloads, which often have specific resource requirements. The Kubernetes scheduler can intelligently place pods on nodes based on resource availability, hardware requirements (such as GPUs), and custom constraints. This is crucial for optimizing the utilization of expensive ML hardware and ensuring that workloads are distributed efficiently across the cluster.
The platform's support for auto-scaling is another feature that makes it well-suited for ML applications. Kubernetes can automatically adjust the number of pods running based on CPU utilization, memory usage, or custom metrics. This capability is invaluable for handling variable workloads, such as serving ML models that may experience sudden spikes in traffic or managing batch processing jobs with fluctuating resource demands.
Kubernetes' extensibility is a key factor in its adoption for ML workloads. The platform supports custom resources and operators, allowing for the definition of domain-specific abstractions and automation. This has led to the development of ML-specific extensions like Kubeflow, which provides a suite of tools for ML operations on Kubernetes. These extensions can simplify common ML tasks such as distributed training, hyperparameter tuning, and model serving.
The platform's approach to networking is also beneficial for ML applications. Kubernetes provides a software-defined networking layer that allows pods to communicate with each other seamlessly, regardless of which nodes they're running on. This simplifies the deployment of distributed ML frameworks like Ray, as workers can easily discover and communicate with each other within the cluster.
Kubernetes' robust support for storage orchestration is another feature that's particularly relevant for ML workloads. The platform can dynamically provision storage volumes and attach them to pods as needed. This is crucial for managing large datasets and persisting model artifacts in distributed ML pipelines. Kubernetes supports a wide range of storage backends, from local disks to cloud-based object stores, providing flexibility in how data is stored and accessed.
The platform's approach to security is also worth noting, especially given the sensitive nature of many ML applications. Kubernetes provides features for network policy enforcement, role-based access control (RBAC), and secrets management. These capabilities allow for the creation of secure ML environments where access to data and resources can be tightly controlled.
Kubernetes' support for rolling updates and rollbacks is another feature that's particularly useful in ML contexts. This allows for the seamless update of ML models and pipelines without downtime, and provides the ability to quickly revert to a previous version if issues are detected. This capability is crucial for maintaining the reliability of ML systems in production environments.
The platform's robust logging and monitoring capabilities are essential for managing complex ML workflows. Kubernetes integrates with a wide range of observability tools, allowing for the collection and analysis of metrics, logs, and traces from all components of an ML system. This observability is crucial for debugging issues, optimizing performance, and ensuring the health of distributed ML applications.
As we progress through this book, you'll learn how to leverage Kubernetes' features in conjunction with Ray to build robust, scalable ML infrastructures. From deploying Ray clusters on Kubernetes to managing complex ML pipelines and serving architectures, Kubernetes will serve as the foundation upon which we'll build our distributed ML systems. In the next section, we'll outline the structure of this book and provide guidance on how to make the most of the material presented.
Book Structure and How to Use It
This book is designed to provide you with a comprehensive understanding of how to leverage Ray and Kubernetes for distributed machine learning. The structure of the book follows a logical progression, starting with foundational concepts and gradually moving towards more advanced topics and real-world applications. Each chapter builds upon the knowledge gained in previous chapters, culminating in a holistic understanding of distributed ML architectures and practices.
The book is divided into several key sections, each focusing on a crucial aspect of distributed machine learning with Ray and Kubernetes:
- Foundations: This section covers the core concepts of Ray and Kubernetes, providing you with a solid understanding of their architectures, components, and how they synergize to create powerful ML infrastructures.
- Resource Management: Here, you'll learn about efficient resource allocation strategies, understanding how to optimize the use of computational resources across your distributed system.
- Distributed Training: This section delves into various techniques for distributed model training, including data parallelism, model parallelism, and leveraging Ray's distributed training APIs.
- Hyperparameter Optimization: You'll explore how to perform large-scale hyperparameter tuning using Ray Tune and integrate these workflows with Kubernetes.
- Data Processing: This part covers distributed data processing techniques using Ray Datasets and efficient data ingestion strategies.
- ML Pipelines: Here, you'll learn how to build end-to-end ML pipelines, orchestrating complex workflows across distributed resources.
- Model Serving: This section focuses on deploying and scaling ML models for inference using Ray Serve and Kubernetes.
- Advanced Topics: The final sections cover advanced subjects such as distributed reinforcement learning, monitoring and debugging distributed systems, ensuring fault tolerance, and addressing security considerations.
To make the most of this book, it's recommended that you have a solid foundation in Python programming and machine learning concepts. Familiarity with basic containerization concepts and cloud computing principles will also be beneficial. However, even if you're new to some of these areas, the book provides enough context and explanation to help you grasp the core ideas.
As you progress through the book, it's highly encouraged that you follow along with the provided code examples and exercises. Setting up a development environment with access to a Kubernetes cluster (either locally using tools like Minikube or on a cloud platform) will allow you to gain hands-on experience with the concepts discussed. Many cloud providers offer free tiers or credits that can be used for learning purposes.
Each chapter builds on the previous ones, but the book is also designed to allow you to focus on specific areas of interest. If you're already familiar with certain concepts, you can skip ahead to more advanced topics. However, it's recommended to at least skim through earlier chapters to ensure you haven't missed any important foundational concepts.
Throughout the book, you'll find callouts and notes highlighting important concepts, potential pitfalls, and best practices. Pay special attention to these as they often contain valuable insights drawn from real-world experience. Additionally, each chapter concludes with a summary of key points and suggestions for further reading, allowing you to deepen your understanding of specific topics.
The book also includes several case studies and real-world examples in later chapters. These are designed to illustrate how the concepts and techniques discussed throughout the book can be applied to solve complex ML problems at scale. Studying these examples and thinking about how they might apply to your own projects will help solidify your understanding and spark ideas for your own distributed ML architectures.
As you work through the book, it's important to experiment and explore beyond the provided examples. The field of distributed ML is rapidly evolving, and the ability to adapt and apply these concepts to new situations is crucial. Don't hesitate to modify the examples, combine different techniques, or explore the documentation of Ray and Kubernetes for additional features and capabilities not covered in depth in this book.
Remember that mastering distributed machine learning is an iterative process. You may need to revisit certain concepts or chapters as you gain more experience and encounter new challenges in your projects. The book is designed to serve as a reference that you can return to as you continue to develop your skills in this field.
Lastly, stay curious and keep exploring. The combination of Ray and Kubernetes opens up a vast landscape of possibilities for distributed ML. As you progress through this book, you'll gain the knowledge and skills to navigate this landscape, but there's always more to learn and discover. Engage with the Ray and Kubernetes communities, explore research papers, and stay updated with the latest developments in the field to continue growing your expertise beyond what's covered in these pages.
With this structure and approach, you're well-equipped to embark on your journey into the world of distributed machine learning with Ray and Kubernetes. The following chapters will provide you with the knowledge, tools, and practical experience to tackle complex ML challenges at scale, opening up new possibilities for innovation and discovery in your ML projects. Let's begin this exciting journey into the future of machine learning infrastructure.
This is the end of the free sample. The full book has 14 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Distributed Systems knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Distributed Systems book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Distributed Systems book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
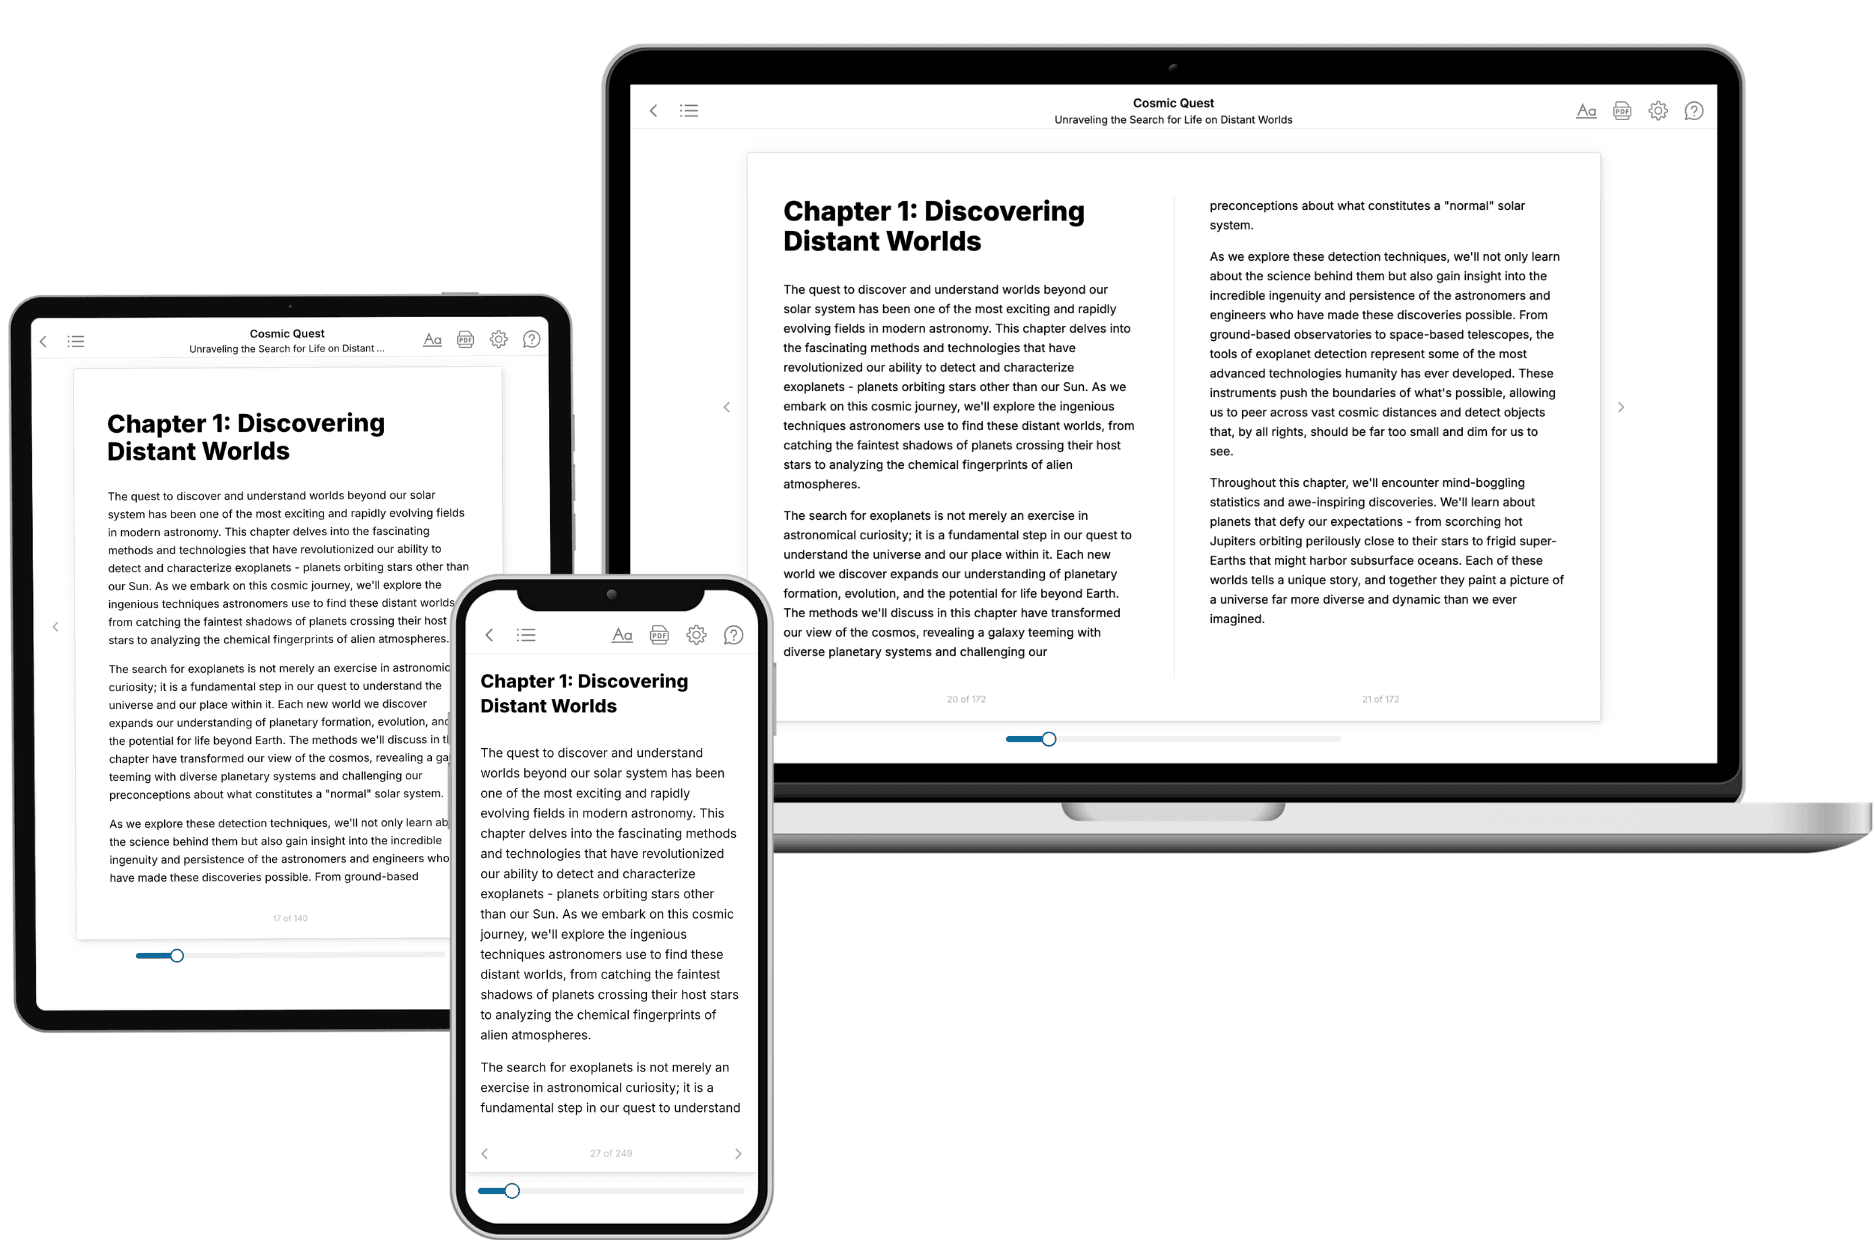
- 3. Get your tailored book
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.