Super-Resolution Techniques Using PyTorch
SRCNN, residual networks and GANs for image enhancement
What if you could transform blurry, low-resolution images into crystal-clear, high-definition versions automatically?
207 pages10 chaptersDec 26, 2025AI and Machine Learning
About this book
Super-resolution technology makes this possible, and PyTorch makes it accessible. This book guides you through building production-ready super-resolution models from the ground up. You'll start with the fundamental concepts of how neural networks enhance image quality, then progress through implementing classic architectures like SRCNN and modern approaches using residual networks and generative adversarial networks. Each chapter combines theory with practical PyTorch code, showing you exactly how to prepare datasets, design architectures, train models efficiently, and optimize them for real-world deployment. Whether you're enhancing medical imaging, improving video quality, or scaling images for web applications, you'll learn the techniques professionals use to deliver exceptional results. By the end, you'll have the skills to architect custom super-resolution solutions tailored to your specific needs.
Table of contents
- IntroductionWhy Super-Resolution Matters Today, What You'll Learn in This Book, How to Use This Book Effectively, Prerequisites and SetupRead below
- Chapter 1: Fundamentals of Super-ResolutionUnderstanding Image Resolution and Quality, The Super-Resolution Problem, Overview of Super-Resolution Approaches
- Chapter 2: Deep Learning Foundations for Super-ResolutionConvolutional Neural Networks Explained, PyTorch Essentials for Image Processing, Building Blocks: Layers and Modules
- Chapter 3: Data Preparation and Dataset ManagementFinding and Preparing Training Datasets, Data Augmentation Strategies, Building Efficient DataLoaders in PyTorch
- Chapter 4: SRCNN: Your First Super-Resolution ModelUnderstanding SRCNN Architecture, Implementing SRCNN in PyTorch, Training and Evaluating SRCNN
- Chapter 5: Residual Networks for Enhanced PerformanceThe Power of Residual Connections, Building ResNet-Based Super-Resolution Models, Dense Connections and DenseNet Variants
- Chapter 6: Loss Functions and Training StrategiesPixel-Level Loss Functions, Perceptual and Feature-Based Losses, Optimization Techniques and Learning Schedules
- Chapter 7: Generative Adversarial Networks for Super-ResolutionGAN Fundamentals and Architecture, Implementing SRGAN in PyTorch, Training GANs Effectively and Stably
- Chapter 8: Evaluating Super-Resolution QualityTechnical Metrics: PSNR, SSIM, and Beyond, Perceptual Quality Assessment, Benchmarking Against Standard Datasets
- Chapter 9: Model Optimization and DeploymentQuantization for Efficient Inference, Pruning and Knowledge Distillation, Deploying Models to Production Environments
- Chapter 10: Advanced Techniques and Real-World ApplicationsMulti-Scale and Progressive Super-Resolution, Video Super-Resolution Challenges, Domain-Specific Applications and Fine-Tuning
- ConclusionKey Takeaways and Next Steps, Future Directions in Super-Resolution Research
- Appendix: Quick Reference and ResourcesPyTorch API Quick Reference, Essential Code Snippets, Further Reading and Research Papers
Introduction
Every day, billions of images flow through our digital world—from smartphone photos to medical scans, from satellite imagery to streaming video. Yet many of these images suffer from a fundamental limitation: insufficient resolution. A security camera captures a crucial moment but the details are too blurry to identify. A medical scan lacks the clarity needed for accurate diagnosis. An old family photograph holds precious memories but appears pixelated when enlarged. Super-resolution technology addresses these challenges by using deep learning to reconstruct high-quality, detailed images from their low-resolution counterparts. This isn't simple upscaling or interpolation—it's intelligent reconstruction that recovers details that traditional methods cannot.
The field of super-resolution has evolved dramatically over the past decade. Early approaches relied on mathematical interpolation techniques like bicubic upsampling, which could only guess at missing information by averaging nearby pixels. These methods produced blurry, unrealistic results that failed to capture the complexity of real-world images. The breakthrough came with deep learning, particularly convolutional neural networks, which learned to recognize patterns and textures from thousands of example images. Modern super-resolution models can now generate remarkably realistic details, transforming a 256×256 pixel image into a crisp 1024×1024 version that looks natural and authentic. This capability has opened doors to applications that were previously impossible or impractical.
PyTorch has emerged as the framework of choice for developing super-resolution models, and for good reason. Its intuitive design philosophy mirrors how developers naturally think about neural networks, making complex architectures easier to conceptualize and implement. Unlike frameworks that hide implementation details behind layers of abstraction, PyTorch gives you direct control over every aspect of your model while still providing powerful high-level tools when you need them. This balance between flexibility and convenience makes PyTorch ideal for both research experimentation and production deployment. Throughout this book, you'll discover how PyTorch's dynamic computation graphs, extensive library of pre-built components, and seamless GPU acceleration enable you to build sophisticated super-resolution systems efficiently.
This book takes a practical, hands-on approach to super-resolution. You won't just read about theoretical concepts—you'll implement working models, train them on real datasets, and optimize them for deployment. Each chapter builds on the previous one, starting with fundamental concepts and progressing to advanced techniques used in production systems. The code examples are complete and runnable, not fragments that leave you guessing about missing pieces. You'll learn not just what works, but why it works, and more importantly, when to apply different techniques based on your specific requirements. Whether your goal is enhancing medical images, improving video quality, or building consumer applications, this book provides the foundation you need.
Why Super-Resolution Matters Today
The demand for high-resolution imagery has never been greater, yet the constraints of physics, hardware, and bandwidth often prevent us from capturing images at the resolution we need. Consider smartphone photography: manufacturers constantly push for better cameras, but sensor size is limited by device thickness, and larger sensors consume more power. Super-resolution offers an elegant solution—capture images at a practical resolution, then intelligently enhance them to match or exceed what larger, more expensive sensors would produce. This approach has become so effective that major smartphone manufacturers now incorporate super-resolution algorithms directly into their camera pipelines, delivering stunning results that would have required professional equipment just years ago.
Medical imaging represents another critical application where super-resolution delivers tangible benefits. MRI and CT scans involve trade-offs between resolution, scan time, and patient radiation exposure. Higher resolution scans provide more diagnostic information but take longer and may expose patients to more radiation. Super-resolution enables radiologists to work with lower-resolution scans that are faster and safer to acquire, then enhance them computationally to reveal the fine details needed for accurate diagnosis. Research has shown that super-resolution can improve the detection of small tumors, subtle fractures, and other critical features that might be missed in lower-resolution images[1]. This technology literally saves lives by making advanced diagnostics more accessible and safer.
Surveillance and security systems face unique challenges that super-resolution helps address. Security cameras must monitor large areas continuously, often under poor lighting conditions and bandwidth constraints. Recording high-resolution video from dozens or hundreds of cameras simultaneously requires enormous storage capacity and network bandwidth. Most systems compromise by recording at lower resolutions, but this creates problems when investigators need to identify faces, read license plates, or examine other fine details. Super-resolution allows security systems to store compact, low-resolution footage, then enhance specific frames or regions of interest when needed. This approach reduces infrastructure costs while maintaining the ability to extract critical details during investigations.
The entertainment and media industry has embraced super-resolution for content restoration and enhancement. Film studios use these techniques to restore classic movies, transforming grainy archival footage into pristine high-definition versions suitable for modern displays. Streaming services apply super-resolution to reduce bandwidth requirements—they can transmit lower-resolution video that's enhanced on the viewer's device, delivering high-quality experiences while consuming less data. Video game developers use super-resolution to render games at lower internal resolutions for better performance, then upscale the output to match display resolution. NVIDIA's DLSS (Deep Learning Super Sampling) technology demonstrates this approach, enabling games to run at higher frame rates without sacrificing visual quality[2].
Satellite and aerial imagery applications benefit enormously from super-resolution capabilities. Earth observation satellites face fundamental constraints: higher resolution requires larger, more expensive optics and generates massive amounts of data that must be transmitted to ground stations. Super-resolution enables satellites to capture images at moderate resolution, then enhance them computationally to reveal details about crop health, urban development, environmental changes, and other phenomena. This technology makes satellite imagery more accessible to researchers, governments, and organizations that lack the resources for the highest-resolution commercial imagery. The same principles apply to drone photography, where weight and power constraints limit camera capabilities.
E-commerce and retail platforms use super-resolution to improve product imagery and customer experience. Online shoppers want to examine products closely before purchasing, but high-resolution product photos consume significant storage and slow page loading times. Super-resolution allows retailers to store and serve moderately-sized images that load quickly, then enhance them when customers zoom in for detailed views. This approach improves both user experience and conversion rates. Additionally, retailers can enhance user-generated content—customer photos taken with various devices—to maintain consistent image quality across their platforms. This capability becomes increasingly important as visual search and augmented reality features become standard in shopping applications.
The scientific research community relies on super-resolution for applications ranging from astronomy to microscopy. Astronomers use these techniques to extract more information from telescope observations, revealing fainter objects and finer details in distant galaxies. Microscopy researchers apply super-resolution to overcome the diffraction limits of optical systems, enabling them to observe cellular structures and processes at unprecedented scales. Materials scientists use it to analyze microscopic images of materials, identifying defects and structures that inform manufacturing processes. In each case, super-resolution extends the effective capabilities of expensive scientific instruments, making research more productive and accessible. These applications demonstrate that super-resolution isn't just about making images look better—it's about extracting information that would otherwise remain hidden.
What You'll Learn in This Book
This book provides a comprehensive journey through super-resolution technology, starting with fundamental concepts and progressing to production-ready implementations. You'll begin by understanding what makes super-resolution challenging and why deep learning succeeds where traditional methods fail. The early chapters establish essential knowledge about image processing, convolutional neural networks, and PyTorch fundamentals. You'll learn how images are represented digitally, what resolution actually means, and how neural networks can learn to reconstruct missing details. These foundations ensure you understand not just how to implement models, but why they work and how to troubleshoot when they don't.
The core chapters guide you through implementing progressively sophisticated super-resolution architectures. You'll start with SRCNN, the pioneering deep learning approach that demonstrated neural networks could outperform traditional methods. Building this relatively simple model teaches you the complete workflow: preparing datasets, defining architectures, implementing training loops, and evaluating results. From there, you'll advance to residual networks, which use skip connections to train much deeper models that achieve superior quality. You'll implement these architectures from scratch in PyTorch, understanding each component's purpose and how they work together. The hands-on approach ensures you gain practical skills, not just theoretical knowledge.
Advanced chapters explore cutting-edge techniques that push super-resolution quality to new levels. You'll learn about generative adversarial networks (GANs) and how they produce remarkably realistic results by training a generator network to fool a discriminator network. Implementing SRGAN will teach you how to handle the unique challenges of adversarial training, including mode collapse, training instability, and balancing multiple loss functions. You'll discover perceptual loss functions that optimize for human visual perception rather than pixel-perfect accuracy, producing images that look more natural even if they differ slightly from ground truth. These advanced techniques represent the current state of the art in super-resolution research.
The book dedicates substantial attention to practical concerns that determine whether models succeed in production. You'll learn comprehensive evaluation strategies that go beyond simple metrics like PSNR (Peak Signal-to-Noise Ratio). While PSNR measures pixel-level accuracy, it doesn't always correlate with perceived quality—images with lower PSNR sometimes look better to human observers. You'll implement perceptual metrics like LPIPS (Learned Perceptual Image Patch Similarity) that better predict human judgments. Understanding these evaluation approaches helps you make informed decisions about model selection and optimization trade-offs. You'll also learn to benchmark your models against standard datasets, enabling meaningful comparisons with published research.
Model optimization and deployment receive thorough coverage because even the best model is useless if it's too slow or resource-intensive for your application. You'll learn quantization techniques that reduce model size and accelerate inference by using lower-precision arithmetic. The book demonstrates pruning methods that remove unnecessary network connections, creating smaller models with minimal quality loss. You'll explore knowledge distillation, where a compact "student" model learns to mimic a larger "teacher" model's behavior. These optimization techniques are essential for deploying super-resolution on mobile devices, embedded systems, or in latency-sensitive applications. You'll see concrete examples of the speed and size improvements these methods achieve.
Real-world applications and domain-specific considerations appear throughout the book. You'll learn how video super-resolution differs from single-image enhancement, exploiting temporal information across frames to improve quality and consistency. The book covers multi-scale approaches that handle various upscaling factors with a single model, and progressive enhancement techniques that build up resolution gradually. Domain-specific chapters address challenges in medical imaging, satellite imagery, and other specialized applications where standard approaches may fail. You'll learn fine-tuning strategies that adapt pre-trained models to new domains with limited training data, a crucial skill for practical applications.
By the end of this book, you'll possess a complete toolkit for super-resolution development. You'll understand the theoretical foundations well enough to read and implement research papers. You'll have practical experience building, training, and optimizing multiple architectures. You'll know how to evaluate models rigorously and make informed decisions about architecture choices, loss functions, and optimization strategies. Most importantly, you'll have the confidence to tackle real-world super-resolution challenges, whether that means enhancing medical images, improving video quality, or building consumer applications. The skills you develop here transfer to other computer vision tasks, making you a more capable machine learning practitioner overall.
How to Use This Book Effectively
This book is designed for active learning—reading alone won't make you proficient at super-resolution. Each chapter includes complete, runnable code examples that you should execute and experiment with. Don't just copy and paste the code; type it yourself, run it, observe the results, then modify it to see what happens. Try changing hyperparameters, swapping loss functions, or adjusting architectures. This experimentation builds intuition that reading cannot provide. When something doesn't work as expected, that's a learning opportunity. Debug the issue, understand what went wrong, and you'll develop problem-solving skills that serve you throughout your career. The book's examples are starting points for exploration, not endpoints to memorize.
The chapters follow a logical progression, with each building on concepts and code from previous ones. If you're new to super-resolution or PyTorch, work through the book sequentially from beginning to end. The early chapters establish foundations that later chapters assume you understand. Skipping ahead may leave you confused about terminology, architectural patterns, or implementation details. However, if you're already experienced with deep learning and PyTorch, you might skim the foundational chapters and focus on super-resolution-specific content. The book's structure accommodates both approaches—beginners get comprehensive coverage, while experienced practitioners can navigate directly to advanced topics.
Each chapter follows a consistent structure designed to maximize learning efficiency:
- Conceptual introduction: Explains the theory and motivation behind techniques before diving into implementation
- Practical implementation: Provides complete PyTorch code with detailed explanations of each component
- Training and evaluation: Demonstrates how to train models and assess their performance
- Troubleshooting guidance: Addresses common problems and how to resolve them
- Practical considerations: Discusses when to use each technique and what trade-offs to expect
The code examples use consistent conventions and patterns throughout the book, making it easier to understand and adapt them. All examples assume you're working in a Python environment with PyTorch installed. The code is written for clarity rather than maximum brevity—variable names are descriptive, and complex operations are broken into understandable steps. Comments explain non-obvious decisions and highlight important details. When you adapt this code for your projects, you can optimize for performance or conciseness, but the book prioritizes understanding. Each code example is self-contained enough to run independently, though some reference utility functions defined in earlier chapters.
Practical exercises appear throughout the book, challenging you to apply what you've learned. These aren't trivial "change this parameter" tasks—they require genuine problem-solving and often have multiple valid solutions. Some exercises ask you to implement variations of techniques discussed in the text. Others present real-world scenarios and ask you to design appropriate solutions. The most valuable learning often comes from struggling with these exercises, so resist the temptation to immediately seek solutions. Spend time thinking through the problem, attempting implementations, and debugging issues. This struggle builds the problem-solving skills that distinguish competent practitioners from those who merely follow tutorials.
The book includes references to research papers and additional resources for readers who want deeper understanding of specific topics. These references aren't just decoration—they're carefully selected to provide valuable context and advanced information. When a chapter introduces a technique from a research paper, the reference enables you to read the original work and understand the full context, including experiments and results not covered in this book. Following these references transforms you from a practitioner who implements existing techniques into one who can evaluate new research and incorporate cutting-edge methods into your work. Building this habit of consulting primary sources accelerates your professional development.
Consider creating a personal project that you develop alongside reading this book. Choose an application that genuinely interests you—perhaps enhancing photos from a specific camera, improving scanned documents, or upscaling video game textures. As you learn new techniques, apply them to your project. This approach provides motivation, reinforces learning, and results in a portfolio piece that demonstrates your capabilities. Your project doesn't need to be novel or groundbreaking; the goal is to apply techniques in a context that matters to you. By the book's end, you'll have both theoretical knowledge and a concrete implementation that showcases your skills. This combination proves far more valuable than either alone when seeking employment or consulting opportunities.
Prerequisites and Setup
This book assumes you have intermediate programming experience, particularly with Python. You should be comfortable with Python syntax, object-oriented programming concepts, and common libraries like NumPy. If you can write classes, understand list comprehensions, and work with NumPy arrays, you have sufficient Python knowledge. The book doesn't teach Python fundamentals—it focuses on super-resolution and PyTorch. If your Python skills are rusty, spend time reviewing before diving into this material. Specifically, ensure you understand decorators, context managers, and generator functions, as PyTorch uses these Python features extensively. Strong Python foundations make learning PyTorch significantly easier.
You should have foundational knowledge of machine learning and deep learning concepts. This means understanding what neural networks are, how they learn through backpropagation, and basic training concepts like loss functions, optimizers, and gradient descent. You don't need to be an expert—the book explains super-resolution-specific concepts in detail—but you should recognize terms like "convolutional layer," "activation function," and "overfitting." If these concepts are unfamiliar, consider working through an introductory deep learning course or book before tackling super-resolution. Andrew Ng's Machine Learning course or the fast.ai Practical Deep Learning course provide excellent foundations. Understanding these basics allows you to focus on super-resolution techniques rather than struggling with fundamental concepts.
Familiarity with basic image processing concepts helps but isn't strictly required. The book explains image-specific concepts as they arise, but prior exposure to topics like color spaces, convolution operations, and image quality metrics accelerates your learning. If you've worked with image data in any capacity—even simple tasks like loading, displaying, and manipulating images with libraries like PIL or OpenCV—you'll find the material more accessible. The book assumes you understand that images are represented as multi-dimensional arrays and that operations on these arrays affect the visual appearance. If you've never worked with image data programmatically, spend some time experimenting with basic image manipulation before starting this book.
Setting up your development environment correctly is crucial for following along with the book's examples. You'll need Python 3.8 or later—the code examples use features from recent Python versions. Install PyTorch following the official instructions at pytorch.org, selecting the appropriate version for your system and whether you have GPU support. GPU acceleration dramatically speeds up training, but isn't absolutely required for learning—you can run smaller experiments on CPU. You'll also need several supporting libraries:
- torchvision: Provides datasets, transforms, and pre-trained models
- NumPy: Essential for numerical operations and array manipulation
- Pillow: Image loading and basic manipulation
- matplotlib: Visualization and plotting results
- scikit-image: Additional image processing utilities and metrics
GPU access significantly improves your learning experience by enabling faster experimentation. Training super-resolution models on CPU is painfully slow—what takes minutes on a GPU might take hours on CPU. If you don't have a local GPU, consider cloud options like Google Colab, which provides free GPU access with some limitations, or paid services like AWS, Google Cloud, or Paperspace. Even a modest GPU like an NVIDIA GTX 1060 or RTX 2060 suffices for the book's examples. The code examples include checks for GPU availability and automatically use GPU when available, falling back to CPU otherwise. This flexibility means you can start learning immediately, then migrate to GPU when you're ready for more intensive training.
Organize your workspace to facilitate learning and experimentation. Create a dedicated directory for the book's code and datasets. Structure it logically with subdirectories for each chapter, datasets, trained models, and results. Use version control (Git) to track your changes and experiments—this habit proves invaluable when you want to revisit earlier versions or understand what modifications led to specific results. Consider using Jupyter notebooks for exploratory work and Python scripts for final implementations. Notebooks excel at interactive development and visualization, while scripts are better for training runs and reproducible experiments. The book's examples work in both environments, so choose based on your preferences and workflow.
Dataset storage requires planning because image datasets can be large. The book uses several standard datasets including DIV2K, Set5, Set14, and BSD100. DIV2K alone contains 800 high-resolution training images totaling several gigabytes. Ensure you have at least 50GB of free storage for datasets and model checkpoints. Download datasets once and store them in a consistent location that your code references. The book provides utilities for downloading and organizing datasets, but you'll need adequate storage and a reliable internet connection. If storage is limited, you can work with smaller subsets of datasets for learning purposes, though final model training benefits from complete datasets.
Finally, cultivate the right mindset for learning this material. Super-resolution combines multiple complex domains—deep learning, computer vision, and software engineering. You won't master everything immediately, and that's expected. When you encounter confusing concepts or bugs in your code, view them as learning opportunities rather than obstacles. The most effective learning happens when you struggle with problems, form hypotheses, test them, and gradually build understanding. Don't expect to understand everything on first reading—some concepts only click after you've implemented them, debugged issues, and seen results. Patience and persistence matter more than innate ability. The developers who excel at super-resolution aren't necessarily the smartest—they're the ones who keep experimenting, learning from failures, and gradually building expertise through consistent practice.
This is the end of the free sample. The full book has 10 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the AI and Machine Learning knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- AI and Machine Learning book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your AI and Machine Learning book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
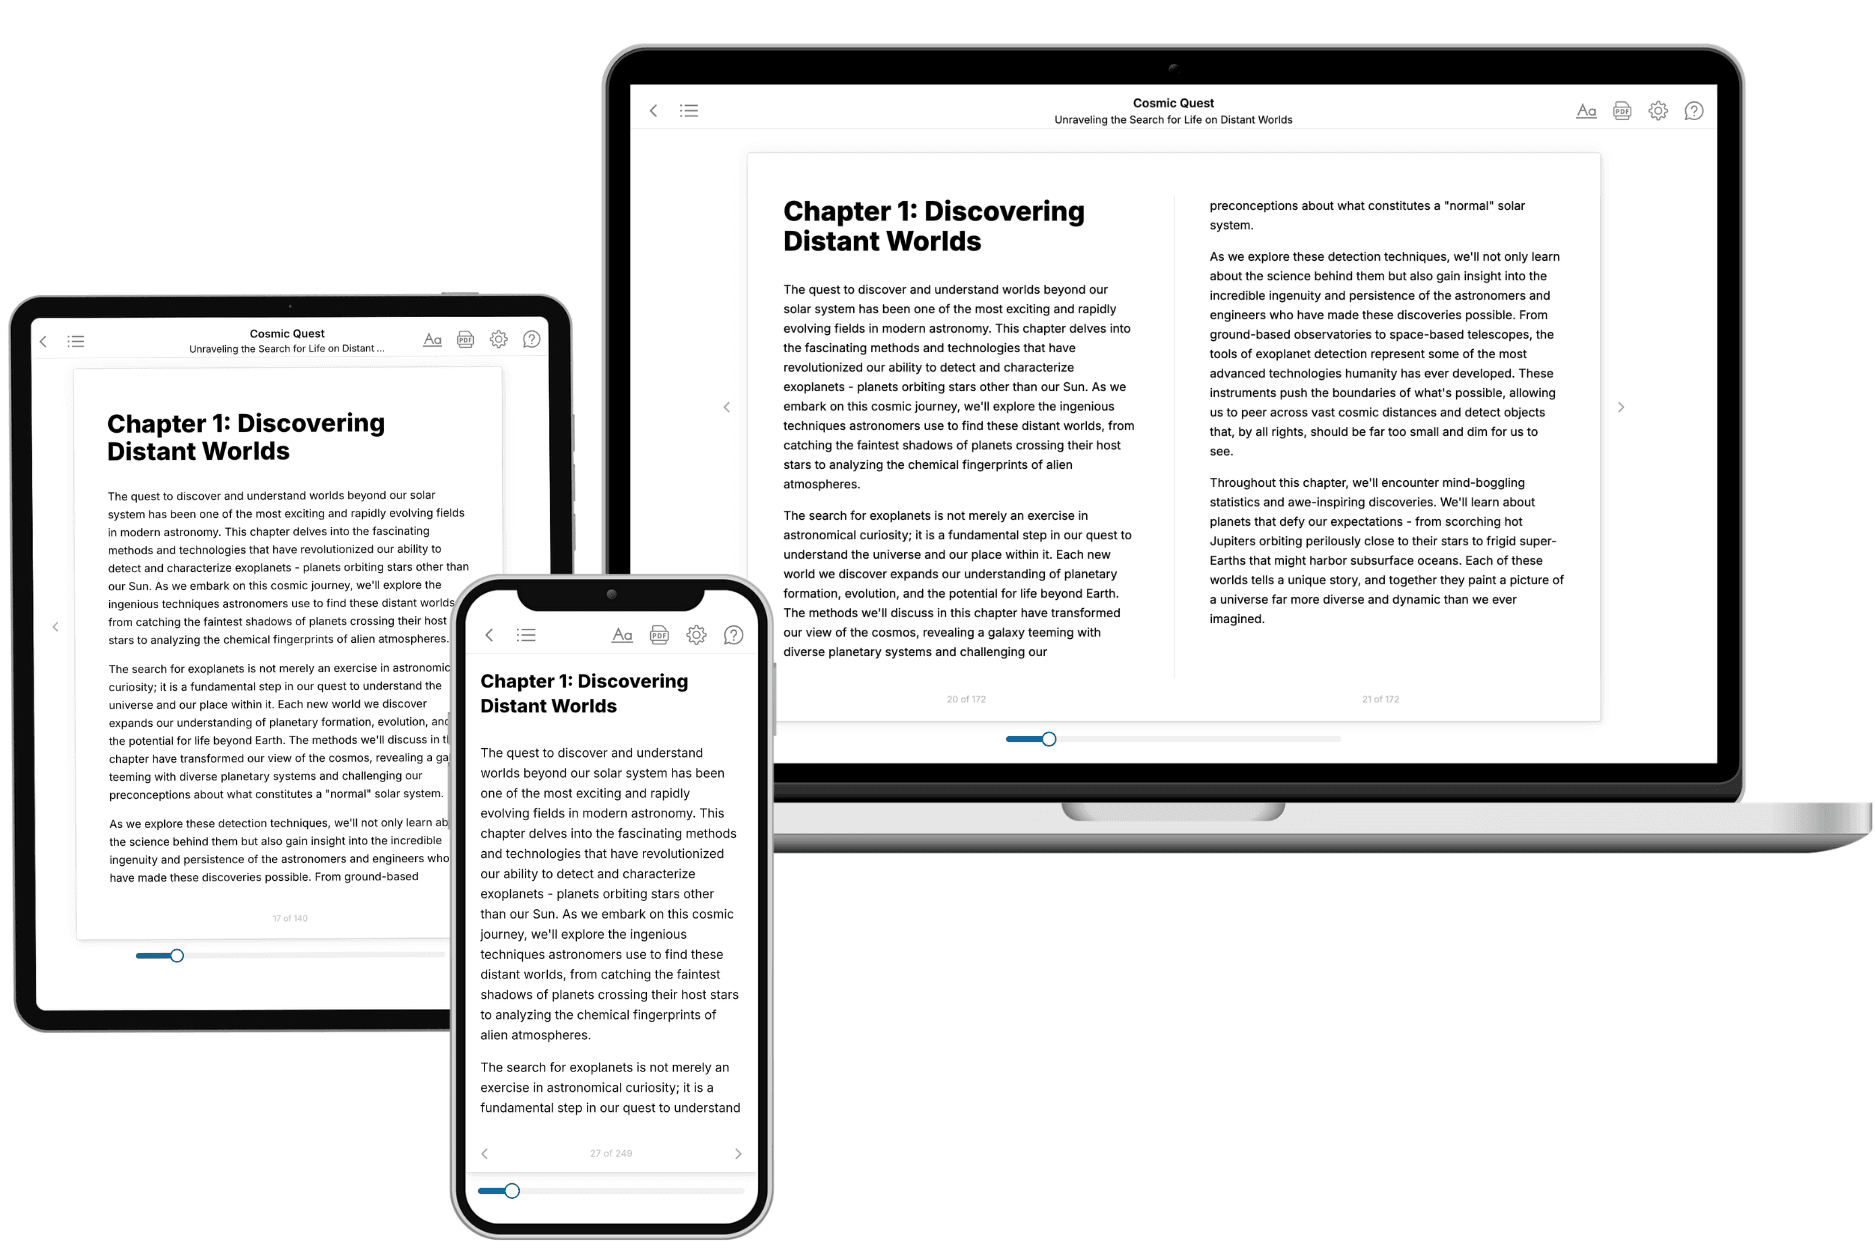
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.