Supervised Learning Algorithms
Master Decision-Making with Machine Learning
Master the fundamentals of supervised learning algorithms and gain the skills to solve real-world decision problems.
191 pages9 chaptersFeb 3, 2026Machine Learning
About this book
You'll progress from understanding core concepts like training and testing data to implementing and evaluating sophisticated models. This book bridges the gap between theory and practice, showing you how to select the right algorithm for your problem, prepare your data effectively, and validate your results rigorously. Through clear explanations and practical examples, you'll learn why certain algorithms work better for specific scenarios, how to avoid common pitfalls like overfitting, and how to combine multiple models for superior performance. Whether you're building predictive systems, classification models, or regression solutions, this comprehensive guide equips you with the knowledge and confidence to make informed decisions about algorithm selection and implementation.
Table of contents
- IntroductionWhy Supervised Learning Matters, How to Use This Book, What You Need to KnowRead below
- Chapter 1: Fundamentals of Supervised LearningThe Supervised Learning Paradigm, Understanding Labeled Data, Training and Testing: The Core Workflow
- Chapter 2: Regression AlgorithmsLinear Regression: The Foundation, Polynomial Regression and Non-Linear Relationships, Ridge and Lasso Regression
- Chapter 3: Classification AlgorithmsLogistic Regression for Binary Classification, Decision Trees: Interpretable and Powerful, Naive Bayes: Probabilistic Classification
- Chapter 4: Distance-Based and Kernel MethodsK-Nearest Neighbors: Simple Yet Effective, Support Vector Machines: Finding Optimal Boundaries, Kernel Tricks and Non-Linear Separation
- Chapter 5: Ensemble MethodsBagging and Bootstrap Aggregating, Random Forests: Powerful Ensemble Learning, Boosting and Gradient Boosting
- Chapter 6: Data Preparation and Feature EngineeringCleaning and Handling Missing Data, Scaling and Normalization, Creating and Selecting Meaningful Features
- Chapter 7: Managing Overfitting and UnderfittingThe Bias-Variance Tradeoff, Regularization Strategies, Cross-Validation for Robust Evaluation
- Chapter 8: Model Evaluation and ValidationMetrics for Regression Models, Metrics for Classification Models, Understanding Confusion Matrices and ROC Curves
- Chapter 9: Choosing the Right AlgorithmAnalyzing Your Problem, Comparing Algorithm Characteristics, Practical Selection Guidelines
- ConclusionKey Takeaways, Your Next Steps in Machine Learning
- Glossary
Introduction
Machine learning has transformed from an academic curiosity into a fundamental technology that powers countless applications you interact with daily. From email spam filters that protect your inbox to recommendation systems that suggest your next favorite movie, supervised learning algorithms work behind the scenes to make intelligent decisions based on patterns learned from data. These algorithms represent one of the most practical and widely-deployed branches of artificial intelligence, offering solutions to problems that would be impossible to solve with traditional rule-based programming. Understanding how these algorithms work and when to apply them has become an essential skill for anyone working with data or building intelligent systems.
The power of supervised learning lies in its ability to learn from examples rather than explicit instructions. Instead of programming every possible rule for identifying spam emails, you provide the algorithm with thousands of examples of spam and legitimate messages, and it discovers the patterns that distinguish them. This learning-from-examples approach scales to problems of remarkable complexity, from predicting customer behavior to diagnosing medical conditions to forecasting financial markets. The algorithms themselves range from elegantly simple methods like linear regression to sophisticated ensemble techniques that combine dozens of models. Each algorithm brings unique strengths, weaknesses, and assumptions that make it suitable for particular types of problems.
This book provides you with a comprehensive foundation in supervised learning algorithms, focusing on practical understanding and real-world application. You'll learn not just how these algorithms work mathematically, but more importantly, when to use each one, how to prepare your data effectively, and how to evaluate whether your model is truly learning meaningful patterns or simply memorizing noise. The journey from raw data to a reliable predictive model involves numerous decisions and potential pitfalls. By the end of this book, you'll have the knowledge and confidence to navigate these challenges, select appropriate algorithms for your specific problems, and build models that generalize well to new, unseen data. Whether you're predicting continuous values with regression or categorizing data with classification, you'll understand the fundamental principles that underpin successful supervised learning applications.
Why Supervised Learning Matters
Supervised learning algorithms solve a fundamental challenge that appears across virtually every industry and domain: making accurate predictions or decisions based on historical patterns. Unlike unsupervised learning, which explores data without predefined outcomes, supervised learning works with labeled examples where the correct answer is known. This makes it particularly powerful for problems where you have historical data with known outcomes and want to predict future results. The supervised approach mirrors how humans often learn—through examples and feedback—making it intuitive to understand and explain to stakeholders who need to trust your model's decisions.
The practical applications of supervised learning span an extraordinary range of real-world problems. In healthcare, algorithms predict patient readmission risk, enabling hospitals to allocate resources more effectively and intervene before complications arise. Financial institutions use supervised learning to assess credit risk, detecting patterns in applicant data that correlate with loan repayment behavior. E-commerce platforms predict customer lifetime value, helping businesses optimize marketing spend by focusing on high-value prospects. Manufacturing companies forecast equipment failures, scheduling maintenance before costly breakdowns occur. Each of these applications shares a common structure: historical data with known outcomes trains a model that then predicts outcomes for new cases.
The economic impact of supervised learning continues to grow as organizations recognize its value in automating complex decision-making processes. Consider a customer service department that manually categorizes thousands of support tickets daily. A well-trained classification algorithm can perform this task in milliseconds with accuracy that matches or exceeds human performance, freeing employees to focus on complex cases requiring human judgment. Similarly, a retail company predicting demand for thousands of products across hundreds of locations would need an army of analysts to do manually what regression algorithms accomplish automatically. The scalability of supervised learning—its ability to make millions of predictions consistently and rapidly—creates value that compounds as data volumes grow.
Beyond pure automation, supervised learning enables entirely new capabilities that weren't previously feasible. Medical imaging systems now detect subtle patterns in X-rays and MRIs that even experienced radiologists might miss, not because the algorithm is inherently smarter, but because it has learned from millions of images—far more than any individual could examine in a lifetime. Fraud detection systems identify suspicious transaction patterns by analyzing billions of historical transactions, recognizing combinations of factors that would be impossible for humans to monitor in real-time. These applications don't just replicate human decision-making more efficiently; they extend human capabilities by processing scales of data and detecting patterns that exceed our cognitive limitations.
The interpretability and accountability of supervised learning make it particularly valuable in regulated industries and high-stakes decisions. Because supervised models learn from labeled historical data, you can evaluate their performance objectively using held-out test sets. You can measure exactly how often a model makes correct predictions, analyze which types of cases it handles well or poorly, and compare different algorithms quantitatively. This transparency contrasts sharply with black-box decision-making processes that rely on intuition or undocumented expertise. When a loan application is denied or a medical diagnosis is suggested, stakeholders increasingly demand explanations grounded in data and measurable performance metrics that supervised learning provides.
The accessibility of supervised learning tools has democratized machine learning, enabling practitioners without advanced mathematics backgrounds to build effective models. Modern libraries and frameworks abstract away much of the mathematical complexity, allowing you to focus on problem formulation, data preparation, and model evaluation—the aspects that typically determine success or failure. However, this accessibility comes with responsibility. Understanding the fundamental principles behind these algorithms—their assumptions, limitations, and failure modes—separates practitioners who build reliable, production-ready systems from those who create fragile models that fail when deployed. This book equips you with that essential understanding.
Perhaps most importantly, supervised learning serves as the foundation for understanding more advanced machine learning techniques. The concepts you'll master here—training and testing splits, overfitting and underfitting, bias-variance tradeoffs, cross-validation, and performance metrics—apply across virtually all machine learning domains. Deep learning, reinforcement learning, and semi-supervised approaches all build upon these fundamentals. By developing a solid grounding in supervised learning, you're not just learning specific algorithms; you're building a conceptual framework that will serve you throughout your machine learning journey, regardless of which specialized areas you eventually pursue.
How to Use This Book
This book is structured to build your understanding progressively, starting with fundamental concepts and advancing toward sophisticated techniques and practical decision-making frameworks. Each chapter focuses on a specific aspect of supervised learning, with concepts introduced in a logical sequence that builds on previous material. You'll gain the most value by working through the chapters in order, especially if you're new to supervised learning. However, if you have some background, you can use the detailed table of contents to jump to specific algorithms or techniques that address your immediate needs. Each chapter is designed to be relatively self-contained while still connecting to the broader narrative.
The book balances three essential elements: conceptual understanding, mathematical foundations, and practical application. You'll learn what each algorithm does, why it works the way it does, and when to apply it to real problems. Mathematical explanations are included where they illuminate understanding, but the focus remains on building intuition rather than rigorous proofs. When equations appear, they're accompanied by plain-language explanations and concrete examples. The goal is to develop your ability to reason about algorithms and make informed decisions, not to memorize formulas. If you find a mathematical section challenging, focus on understanding the concept it represents—you can always return to the details later.
Throughout the book, you'll encounter practical examples that demonstrate how concepts apply to real-world scenarios. These examples are designed to be specific and concrete rather than abstract or generic. For instance, when discussing classification algorithms, you'll see how they apply to specific problems like email spam detection, customer churn prediction, or medical diagnosis. When exploring regression techniques, you'll examine applications like house price prediction, sales forecasting, and demand estimation. These examples serve multiple purposes: they make abstract concepts tangible, they illustrate the types of problems each algorithm handles well, and they provide templates you can adapt to your own projects.
To maximize your learning, consider implementing the algorithms and techniques as you read about them. While this book doesn't include code listings—focusing instead on concepts and principles that transcend any particular programming language or library—the knowledge you gain here translates directly to implementation. After reading about linear regression, try implementing it on a simple dataset. After learning about cross-validation, apply it to evaluate your models. This hands-on practice transforms passive reading into active learning, revealing nuances and challenges that only become apparent through implementation. The conceptual understanding you build here will make your implementations more thoughtful and your debugging more effective.
Pay particular attention to the sections on data preparation, overfitting management, and model evaluation. These topics often receive less attention than algorithm details in introductory materials, yet they typically determine whether your models succeed or fail in practice. A sophisticated algorithm applied to poorly prepared data will underperform a simple algorithm with well-engineered features. A model that hasn't been properly validated may appear successful in development but fail catastrophically in production. The chapters dedicated to these topics provide frameworks and techniques that apply regardless of which specific algorithms you ultimately choose. Consider these sections essential reading, even if you're tempted to skip ahead to more exciting algorithm descriptions.
The book includes several recurring elements designed to reinforce learning and highlight important points:
- Key concepts are emphasized in bold when first introduced, helping you identify the essential vocabulary and ideas
- Practical guidelines appear throughout, offering actionable advice for applying concepts to real problems
- Common pitfalls are explicitly identified, helping you avoid mistakes that frequently trip up practitioners
- Comparison frameworks help you understand when to choose one approach over another
- Examples and case studies illustrate concepts with specific, concrete scenarios
As you progress through the book, you'll notice that later chapters increasingly emphasize decision-making and judgment rather than just technical knowledge. The early chapters focus on understanding individual algorithms and techniques. The middle chapters explore how to prepare data and manage common challenges. The later chapters help you develop the judgment to choose appropriate algorithms, combine techniques effectively, and evaluate results critically. This progression mirrors the actual development of expertise in supervised learning: you start by learning tools, then learn to use them properly, and finally develop the wisdom to know which tools to apply in which situations. Your goal should be to reach that final stage—not just knowing how algorithms work, but understanding when and why to use them.
Consider keeping a learning journal as you work through this book. After each chapter, write a brief summary of the key concepts in your own words, note questions that arose, and identify how the material might apply to problems you're interested in solving. This active reflection deepens understanding and helps you connect abstract concepts to your specific context. When you encounter a challenging concept, try explaining it to someone else—even if that someone is an imaginary audience. The act of articulating ideas in your own words reveals gaps in understanding and solidifies knowledge. These metacognitive practices transform reading from passive consumption into active learning, significantly improving retention and application.
What You Need to Know
This book assumes you have foundational knowledge in computer science and basic familiarity with programming concepts. You should be comfortable with fundamental programming constructs like variables, functions, loops, and conditional statements. You don't need expertise in any particular programming language, but you should understand how to translate algorithmic descriptions into code. If you've completed introductory computer science courses or have practical programming experience, you have sufficient background. The book focuses on concepts and principles rather than implementation details, making the material accessible regardless of your preferred programming language or machine learning library.
A working understanding of basic mathematics is essential for grasping supervised learning algorithms. You should be comfortable with algebra, including working with equations, variables, and functions. Familiarity with basic statistics—concepts like mean, variance, and probability—will help you understand how algorithms make predictions and how we evaluate their performance. You'll encounter some calculus concepts, particularly when discussing optimization and gradient-based methods, but the book emphasizes intuition over rigorous mathematical proofs. If you can understand what a derivative represents (the rate of change of a function) and what it means to minimize a function, you have sufficient mathematical background. When more advanced mathematics appears, it's accompanied by intuitive explanations and visual analogies.
Basic linear algebra knowledge will enhance your understanding, though it's not strictly required for following the main concepts. Many supervised learning algorithms operate on vectors and matrices, and understanding these structures helps you grasp how algorithms process data. You should know what vectors and matrices are, understand basic operations like matrix multiplication, and recognize that data is often represented as matrices where rows represent examples and columns represent features. If you've taken an introductory linear algebra course or worked with multi-dimensional arrays in programming, you have adequate preparation. The book explains linear algebra concepts when they're essential to understanding an algorithm, but doesn't assume advanced knowledge.
No prior machine learning experience is required, though some exposure to basic concepts will help you progress more quickly. If you've heard terms like training data, features, and predictions but aren't entirely sure what they mean, this book will clarify them. If you've never encountered machine learning before, the early chapters provide all the foundational concepts you need. The book is specifically designed for intermediate learners—those who have foundational technical skills but are new to supervised learning or want to deepen their understanding beyond surface-level familiarity. If you've experimented with machine learning libraries but want to understand what's happening beneath the API calls, this book bridges that gap.
Practical experience working with data will help you appreciate the challenges and techniques discussed throughout the book. If you've worked with datasets in any capacity—analyzing data in spreadsheets, querying databases, or processing data files—you'll recognize the data quality issues and preparation challenges that supervised learning practitioners face. Understanding concepts like missing values, outliers, and data types provides context for the data preparation techniques covered in later chapters. However, if your data experience is limited, the book provides sufficient explanation to understand these challenges. The key is recognizing that real-world data is messy and requires careful handling before algorithms can learn from it effectively.
You should approach this book with realistic expectations about what supervised learning can and cannot accomplish. Supervised learning is powerful but not magical—it finds patterns in historical data and applies them to new cases. It cannot predict outcomes that have no relationship to the input features, learn from data that doesn't contain relevant patterns, or make reliable predictions far outside the range of training examples. Understanding these limitations is as important as understanding the algorithms' capabilities. The book explicitly addresses common misconceptions and helps you develop realistic expectations about what supervised learning can achieve in different scenarios. This balanced perspective will serve you well when evaluating whether supervised learning is appropriate for a particular problem.
Finally, you should bring curiosity and willingness to think critically about algorithms and their applications. Supervised learning involves numerous decisions—which algorithm to use, how to prepare data, which features to include, how to evaluate performance—and there are rarely single correct answers. Different practitioners might make different reasonable choices for the same problem. The book provides frameworks and guidelines for making these decisions, but developing good judgment requires practice and reflection. Approach each concept with questions: Why does this algorithm work this way? When would it fail? How does it compare to alternatives? What assumptions does it make? This critical thinking transforms knowledge into understanding and prepares you to handle novel situations that don't match textbook examples exactly.
If you find that you're missing some of the assumed background knowledge, don't be discouraged. The book is written to be as accessible as possible while maintaining technical accuracy. When mathematical concepts appear, they're explained in context with intuitive descriptions. When programming knowledge is assumed, it's at a conceptual level rather than requiring specific syntax or libraries. If you encounter a concept that's unfamiliar, you have several options: research it briefly to fill the gap, continue reading to see if context clarifies it, or make a note to return to it later. Many concepts become clearer as you see them applied in different contexts throughout the book. The goal is to build understanding progressively, and occasional gaps in background knowledge shouldn't prevent you from gaining substantial value from the material.
This is the end of the free sample. The full book has 9 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Machine Learning knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Machine Learning book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Machine Learning book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
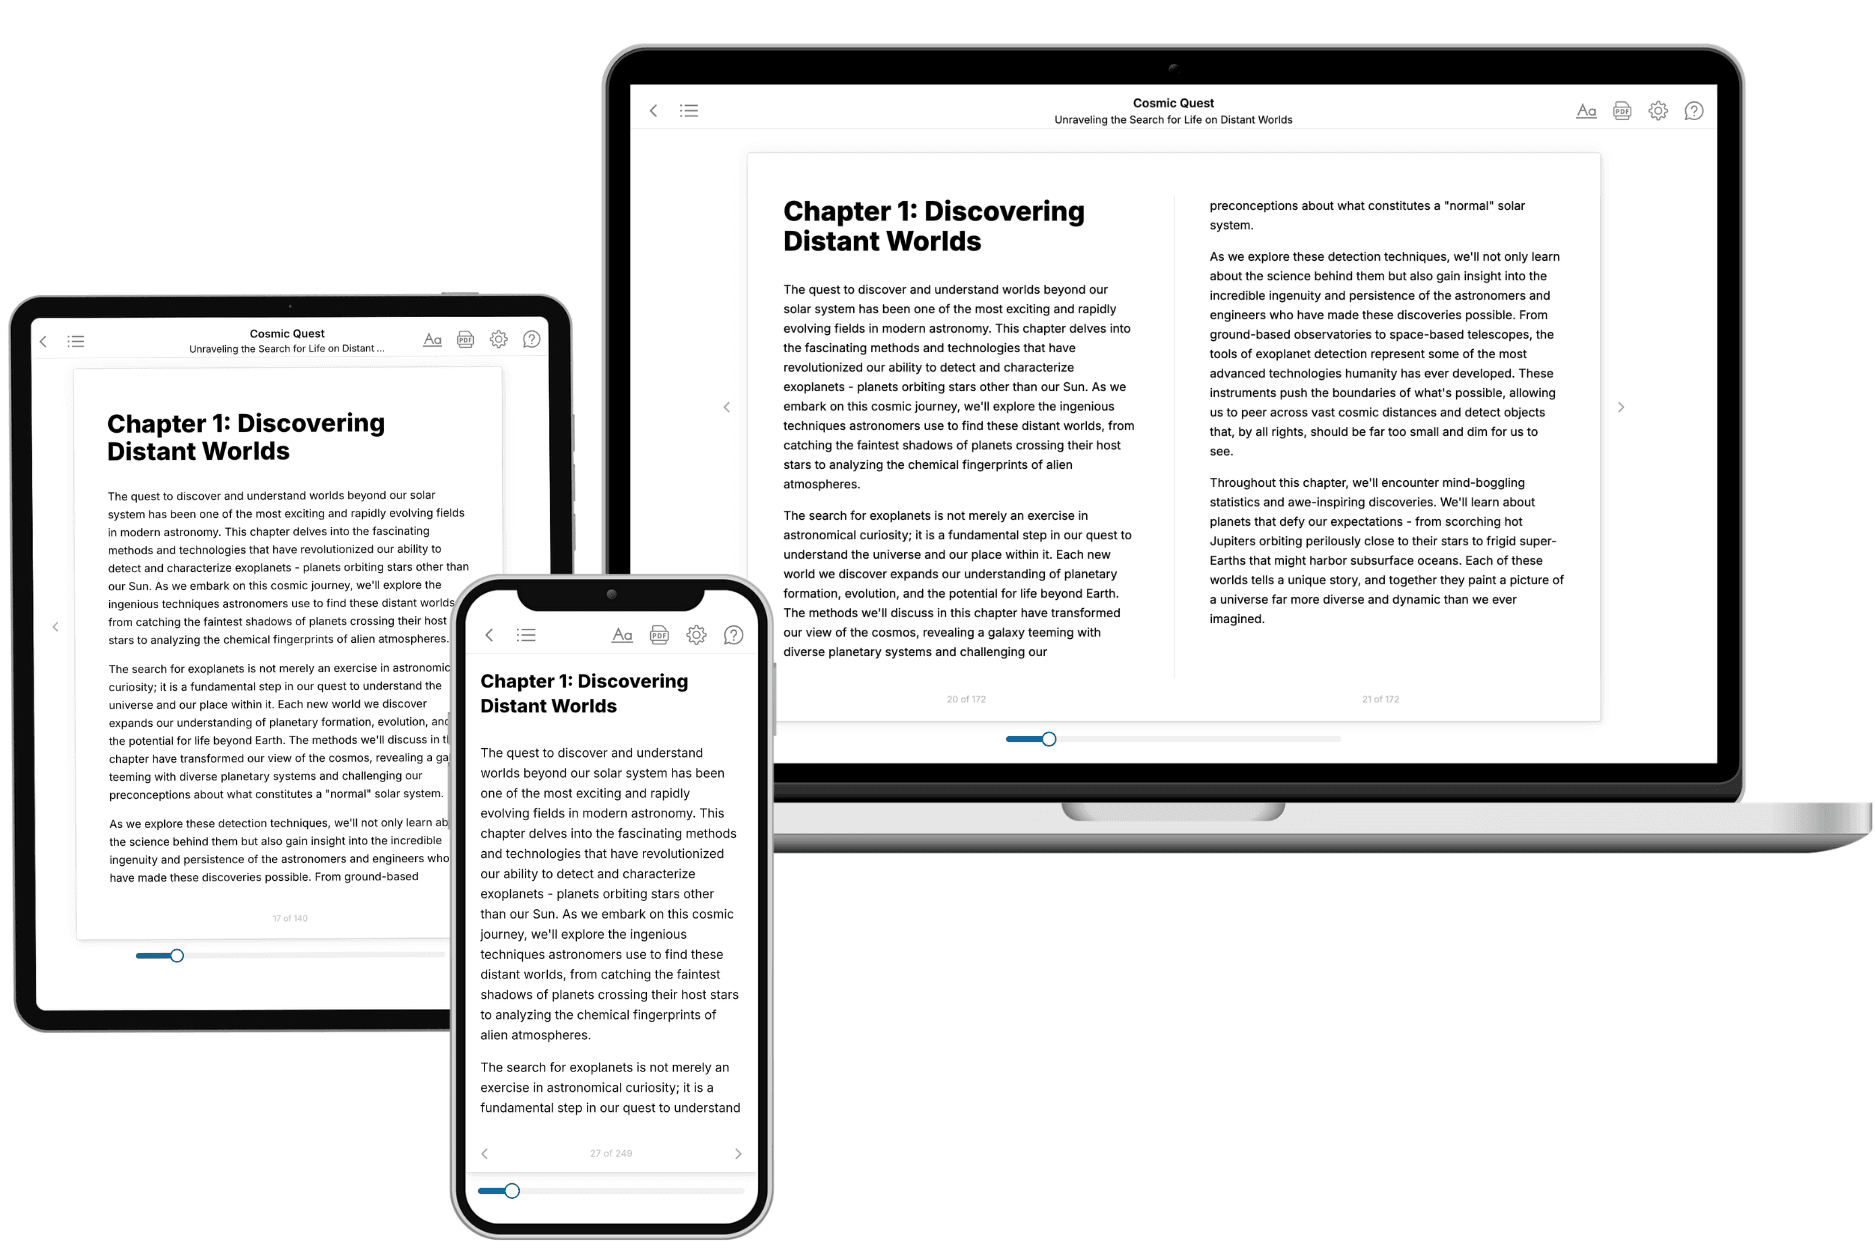
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.