Unsupervised Learning Unlocked
Master Clustering, Dimensionality Reduction, and Pattern Discovery Without Labels
You'll gain practical mastery of unsupervised machine learning by understanding how to extract meaningful insights from unlabeled data.
207 pages11 chaptersJul 16, 2026Unsupervised Learning
About this book
This book walks you through the core algorithms—clustering, dimensionality reduction, and anomaly detection—with clear explanations of when and why to use each technique. You'll learn the mathematical foundations without getting lost in complex notation, explore real-world applications across customer segmentation, image analysis, and recommendation systems, and discover how to evaluate your models when ground truth labels don't exist. Each chapter combines theory with hands-on examples, showing you how to preprocess data, select appropriate algorithms, tune hyperparameters, and interpret results. Whether you're preparing data for supervised learning or building standalone unsupervised systems, this book equips you with the knowledge and confidence to tackle complex pattern discovery challenges in your own projects.
Table of contents
- IntroductionWhy Unsupervised Learning Matters, How This Book Is Organized, What You Need to Know Before StartingRead below
- Chapter 1: Fundamentals of Unsupervised LearningSupervised vs. Unsupervised Learning, Types of Unsupervised Learning Problems, Real-World Applications and Use Cases
- Chapter 2: Data Preparation and Feature EngineeringCleaning and Handling Missing Data, Feature Scaling and Normalization, Feature Selection and Engineering, Exploratory Data Analysis for Unsupervised Learning
- Chapter 3: Introduction to ClusteringCore Clustering Concepts and Distance Metrics, Common Clustering Challenges, Choosing the Right Clustering Approach
- Chapter 4: K-Means and Partitioning MethodsHow K-Means Works, Implementing K-Means in Practice, Limitations and Variations of K-Means, Real-World K-Means Applications
- Chapter 5: Hierarchical Clustering MethodsAgglomerative and Divisive Clustering, Understanding Dendrograms and Linkage Criteria, Implementing Hierarchical Clustering, When to Use Hierarchical Over K-Means
- Chapter 6: Density-Based ClusteringDBSCAN and Density-Based Approaches, Tuning DBSCAN Parameters, Density Clustering for Anomaly Detection
- Chapter 7: Dimensionality Reduction TechniquesUnderstanding the Curse of Dimensionality, Principal Component Analysis (PCA) Fundamentals, Implementing and Interpreting PCA, PCA Applications in Data Compression and Visualization
- Chapter 8: Advanced Dimensionality Reduction Methodst-SNE and UMAP for Visualization, Autoencoders and Deep Learning Approaches, Comparing Dimensionality Reduction Techniques
- Chapter 9: Evaluating Unsupervised ModelsInternal Validation Metrics, External Validation and Domain Knowledge, Silhouette Score and Davies-Bouldin Index, Model Selection and Hyperparameter Tuning
- Chapter 10: Practical Projects and Case StudiesCustomer Segmentation Project, Image Clustering and Analysis, Anomaly Detection in Time Series Data
- Chapter 11: Advanced Topics and Future DirectionsSemi-Supervised and Self-Supervised Learning, Ensemble Methods for Unsupervised Learning, Scaling Unsupervised Learning to Big Data
- ConclusionKey Takeaways and Next Steps, Resources for Continued Learning
Introduction
Most machine learning courses start with labeled data. You get a spreadsheet with a column that tells you the answer, and your job is to build a model that learns to predict that answer for new examples. It feels clean, structured, and satisfying. But the real world rarely works that way. Most of the data that exists in the world has no labels attached to it. There are no neat columns telling you which customers are loyal, which transactions are fraudulent, or which images belong together. The data just sits there, waiting for someone to find the patterns hiding inside it.
That is exactly what unsupervised learning is for. Instead of learning from labeled examples, unsupervised algorithms explore the structure of data on their own. They find natural groupings, compress information into simpler forms, and surface patterns that no human explicitly defined. This makes unsupervised learning one of the most powerful and flexible tools in the machine learning toolkit. It is also one of the most underappreciated, often treated as a preprocessing step rather than a discipline worth mastering in its own right.
This book changes that. Whether you want to segment customers, reduce the dimensionality of a complex dataset, detect anomalies in system logs, or simply understand your data better before building a supervised model, the techniques covered here will give you a solid foundation and practical skills. The goal is not just to explain how these algorithms work mathematically, but to help you develop the intuition to know when to use them, how to tune them, and how to interpret what they find. By the end, you will be equipped to tackle real-world pattern discovery challenges with confidence.
A quick note on approach: this book balances theory with practice. Each major concept is explained clearly, with enough mathematical grounding to understand what is happening under the hood, but without drowning in notation. Every algorithm is paired with concrete examples, implementation guidance, and discussion of real-world tradeoffs. You will see code, you will see data, and you will see the kinds of messy situations that arise when you move from textbook examples to actual projects.
Why Unsupervised Learning Matters
Consider the scale of unlabeled data in the world today. Every day, billions of images are uploaded to the internet without structured annotations. Millions of customer transactions occur without anyone manually tagging them as normal or suspicious. Genomic sequencing produces enormous datasets where the biological meaning of most patterns is still unknown. Labeling even a small fraction of this data requires significant human effort, domain expertise, and time. Unsupervised learning offers a way to extract value from all of it, without waiting for labels that may never come.[1]
Beyond the sheer volume of unlabeled data, unsupervised learning matters because it can reveal structure that humans would never think to look for. When a supervised model is trained to predict a specific outcome, it only learns what is relevant to that outcome. Unsupervised methods have no such constraint. They can surface unexpected groupings, hidden correlations, and emergent patterns that no one anticipated. This exploratory power makes them invaluable for scientific discovery, business intelligence, and any domain where the questions themselves are still being formed.
Unsupervised learning also plays a critical supporting role in supervised machine learning pipelines. Dimensionality reduction techniques like PCA can dramatically improve the performance of downstream classifiers by removing noise and redundant features. Clustering can generate synthetic labels for semi-supervised learning when only a small amount of labeled data is available. Anomaly detection can flag data quality issues before they corrupt a training set. In this sense, mastering unsupervised learning makes you a better machine learning practitioner overall, not just in the specific scenarios where labels are absent.
The business impact of unsupervised learning is substantial and growing. Customer segmentation, one of the most common applications, allows companies to tailor marketing, pricing, and product recommendations to distinct groups of users. A retail company that discovers five distinct customer personas through clustering can design five targeted campaigns instead of one generic one, often with dramatically better conversion rates. Fraud detection systems use anomaly detection to flag unusual transactions in real time. Recommendation engines use collaborative filtering, a form of unsupervised pattern matching, to drive a significant share of revenue at companies like Netflix and Amazon.[2]
There is also a deeper intellectual reason to care about unsupervised learning. It is closer to how human cognition actually works. Humans do not learn everything from explicit feedback. Infants learn to recognize faces, objects, and speech patterns long before anyone labels them. The brain constantly organizes sensory input into categories, finds regularities, and builds internal models of the world without supervision. Unsupervised learning algorithms are, in a sense, an attempt to replicate this kind of self-organizing intelligence in software. Understanding these methods gives you insight not just into machine learning, but into the nature of learning itself.
Finally, unsupervised learning is becoming more central to the frontier of AI research. Self-supervised learning, which uses the structure of data itself to generate training signals, powers many of the most impressive recent advances in natural language processing and computer vision. Models like GPT and BERT are trained on massive amounts of unlabeled text using self-supervised objectives. Understanding the foundations of unsupervised learning is therefore not just useful for today's practical applications. It is essential preparation for understanding where the field is heading.
Key insight: Unsupervised learning is not a fallback for when you lack labels. It is a distinct and powerful approach to understanding data that complements supervised methods and, in many cases, enables discoveries that labeled approaches simply cannot make.
The techniques you will learn in this book are already in production at companies of every size, from startups using K-means to segment their first thousand users to large enterprises running distributed clustering pipelines on billions of records. The gap between understanding these methods conceptually and being able to apply them effectively is what this book is designed to close.
How This Book Is Organized
This book is structured to take you from foundational concepts to practical mastery in a logical progression. Each chapter builds on the previous ones, but the chapters are also designed to be useful as standalone references once you have read through the book once. If you already have some familiarity with a topic, you can skip ahead and return to earlier chapters when you need to fill in gaps.
The book is organized into four broad phases. The first phase covers the foundations: what unsupervised learning is, how it differs from supervised learning, and how to prepare your data for it. The second phase dives deep into clustering algorithms, covering the three major families in detail. The third phase covers dimensionality reduction, from the classic PCA to modern deep learning approaches. The fourth phase addresses evaluation, practical projects, and advanced topics that point toward the future of the field.
Here is a chapter-by-chapter overview of what you will find:
- Chapter 1: Fundamentals of Unsupervised Learning. This chapter establishes the conceptual framework. You will learn the difference between supervised and unsupervised learning, the main categories of unsupervised problems (clustering, dimensionality reduction, density estimation, and anomaly detection), and a survey of real-world applications to ground the rest of the book.
- Chapter 2: Data Preparation and Feature Engineering. Unsupervised algorithms are highly sensitive to data quality and feature representation. This chapter covers cleaning missing data, scaling features, engineering new features, and conducting exploratory data analysis before applying any algorithm.
- Chapter 3: Introduction to Clustering. Before diving into specific algorithms, this chapter builds the conceptual vocabulary for clustering: distance metrics, similarity measures, the challenges of high-dimensional spaces, and a framework for choosing the right clustering approach for a given problem.
- Chapter 4: K-Means and Partitioning Methods. K-means is the most widely used clustering algorithm. This chapter explains how it works, how to implement it, how to choose the number of clusters, and where it breaks down. Variations like K-means++ and mini-batch K-means are also covered.
- Chapter 5: Hierarchical Clustering Methods. Hierarchical clustering builds a tree of clusters rather than a flat partition. This chapter covers agglomerative and divisive approaches, how to read and use dendrograms, and when hierarchical methods outperform K-means.
- Chapter 6: Density-Based Clustering. DBSCAN and related algorithms find clusters of arbitrary shape and naturally identify outliers. This chapter covers the algorithm, parameter tuning, and applications in anomaly detection.
- Chapter 7: Dimensionality Reduction Techniques. This chapter introduces the curse of dimensionality and covers PCA in depth, including the mathematical intuition, implementation, and practical applications in compression and visualization.
- Chapter 8: Advanced Dimensionality Reduction Methods. t-SNE and UMAP are the go-to tools for visualizing high-dimensional data. Autoencoders bring deep learning into the picture. This chapter compares these methods and explains when to use each one.
- Chapter 9: Evaluating Unsupervised Models. Without ground truth labels, evaluation requires different strategies. This chapter covers internal metrics like silhouette score and Davies-Bouldin index, external validation approaches, and practical model selection workflows.
- Chapter 10: Practical Projects and Case Studies. Three end-to-end projects bring everything together: customer segmentation, image clustering, and anomaly detection in time series data. Each project walks through the full pipeline from raw data to actionable insights.
- Chapter 11: Advanced Topics and Future Directions. The final chapter covers semi-supervised and self-supervised learning, ensemble methods for unsupervised tasks, and strategies for scaling these techniques to large datasets.
Throughout the book, code examples are written in Python using widely adopted libraries including scikit-learn, numpy, pandas, and matplotlib. Where deep learning approaches are discussed, PyTorch and TensorFlow/Keras examples are provided. All code is designed to be readable and runnable, not just illustrative.
Each chapter also includes a set of practical takeaways and, where appropriate, common pitfalls to avoid. These are drawn from real-world experience with these algorithms and are designed to save you from the mistakes that are easy to make when you first apply these methods to your own data.
If you are working through the book as a learning exercise, the recommended path is linear: read from Chapter 1 through Chapter 11 in order. If you are using the book as a reference while working on a specific project, the chapter overviews above should help you navigate directly to what you need. The practical projects in Chapter 10 are particularly useful as templates you can adapt to your own datasets.
What You Need to Know Before Starting
This book is written for intermediate learners. That means it assumes you have some background in machine learning and programming, but it does not assume you are an expert. The goal is to meet you where you are and build from there, explaining concepts clearly without over-simplifying them or burying them in unnecessary complexity.
Here is a clear breakdown of what background knowledge will help you get the most out of this book:
- Python programming. You should be comfortable writing Python code, working with functions and classes, and using libraries like
numpyandpandasfor data manipulation. You do not need to be an expert, but you should be able to read and modify code examples without significant difficulty. - Basic machine learning concepts. You should understand what training and test sets are, what overfitting means, and the general idea of how supervised learning algorithms like linear regression or decision trees work. You do not need deep expertise in supervised learning, but familiarity with the basic workflow will help.
- Foundational mathematics. Linear algebra concepts like vectors, matrices, and dot products appear throughout the book, especially in the dimensionality reduction chapters. Basic statistics (mean, variance, distributions) and some calculus intuition are also helpful. The book explains the math it uses, but having seen these concepts before will make the explanations easier to follow.
- Data handling experience. You should have some experience loading, exploring, and cleaning datasets in Python. Familiarity with
pandasDataFrames and basicmatplotliborseabornplotting will make the code examples much more accessible.
If you are missing some of these prerequisites, do not worry. The book is written to be as self-contained as possible. Mathematical concepts are explained when they are introduced, and code examples are annotated to make them readable even if you are not deeply familiar with every library. That said, if you find yourself struggling with the Python code or the linear algebra in the dimensionality reduction chapters, it may be worth spending a few hours reviewing those topics before continuing.
What you do not need is prior experience with unsupervised learning specifically. This book starts from the beginning with these techniques. You also do not need a background in deep learning to follow most of the book. The autoencoder section in Chapter 8 introduces neural network concepts, but it is written to be accessible even if you have only a passing familiarity with how neural networks work.
On the software side, the examples in this book were developed and tested with Python 3.9 and above. The key libraries used are:
scikit-learn(version 1.2 or higher) for clustering, dimensionality reduction, and evaluation metricsnumpyandpandasfor data manipulationmatplotlibandseabornfor visualizationscipyfor hierarchical clustering and statistical functionsumap-learnfor UMAP dimensionality reductiontensorfloworpytorchfor autoencoder examples in Chapter 8
You can install the core dependencies with a single command:
pip install scikit-learn numpy pandas matplotlib seaborn scipy umap-learnFor the deep learning examples, install either TensorFlow or PyTorch according to your preference and hardware setup. Instructions for GPU-enabled installations are available on the official documentation pages for each library.
One mindset note before you begin: unsupervised learning requires a different way of thinking than supervised learning. In supervised learning, you have a clear objective function and a clear way to measure success. In unsupervised learning, success is often more ambiguous. A clustering result might be technically valid by one metric but meaningless in the context of your actual problem. A dimensionality reduction might preserve global structure beautifully while distorting local neighborhoods. Learning to navigate this ambiguity, to combine algorithmic outputs with domain knowledge and business context, is one of the most important skills this book will help you develop.
The best way to learn these techniques is to apply them to data you care about. As you work through each chapter, think about datasets from your own work or interests where these methods might apply. The concepts will stick much better when they are connected to real problems you want to solve. By the time you finish this book, you should not just understand unsupervised learning in the abstract. You should be ready to open a dataset, choose an appropriate approach, implement it, evaluate the results, and explain what you found to someone who has never heard of K-means or PCA. That is the goal, and everything in this book is designed to get you there.
This is the end of the free sample. The full book has 11 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Unsupervised Learning knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Unsupervised Learning book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Unsupervised Learning book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
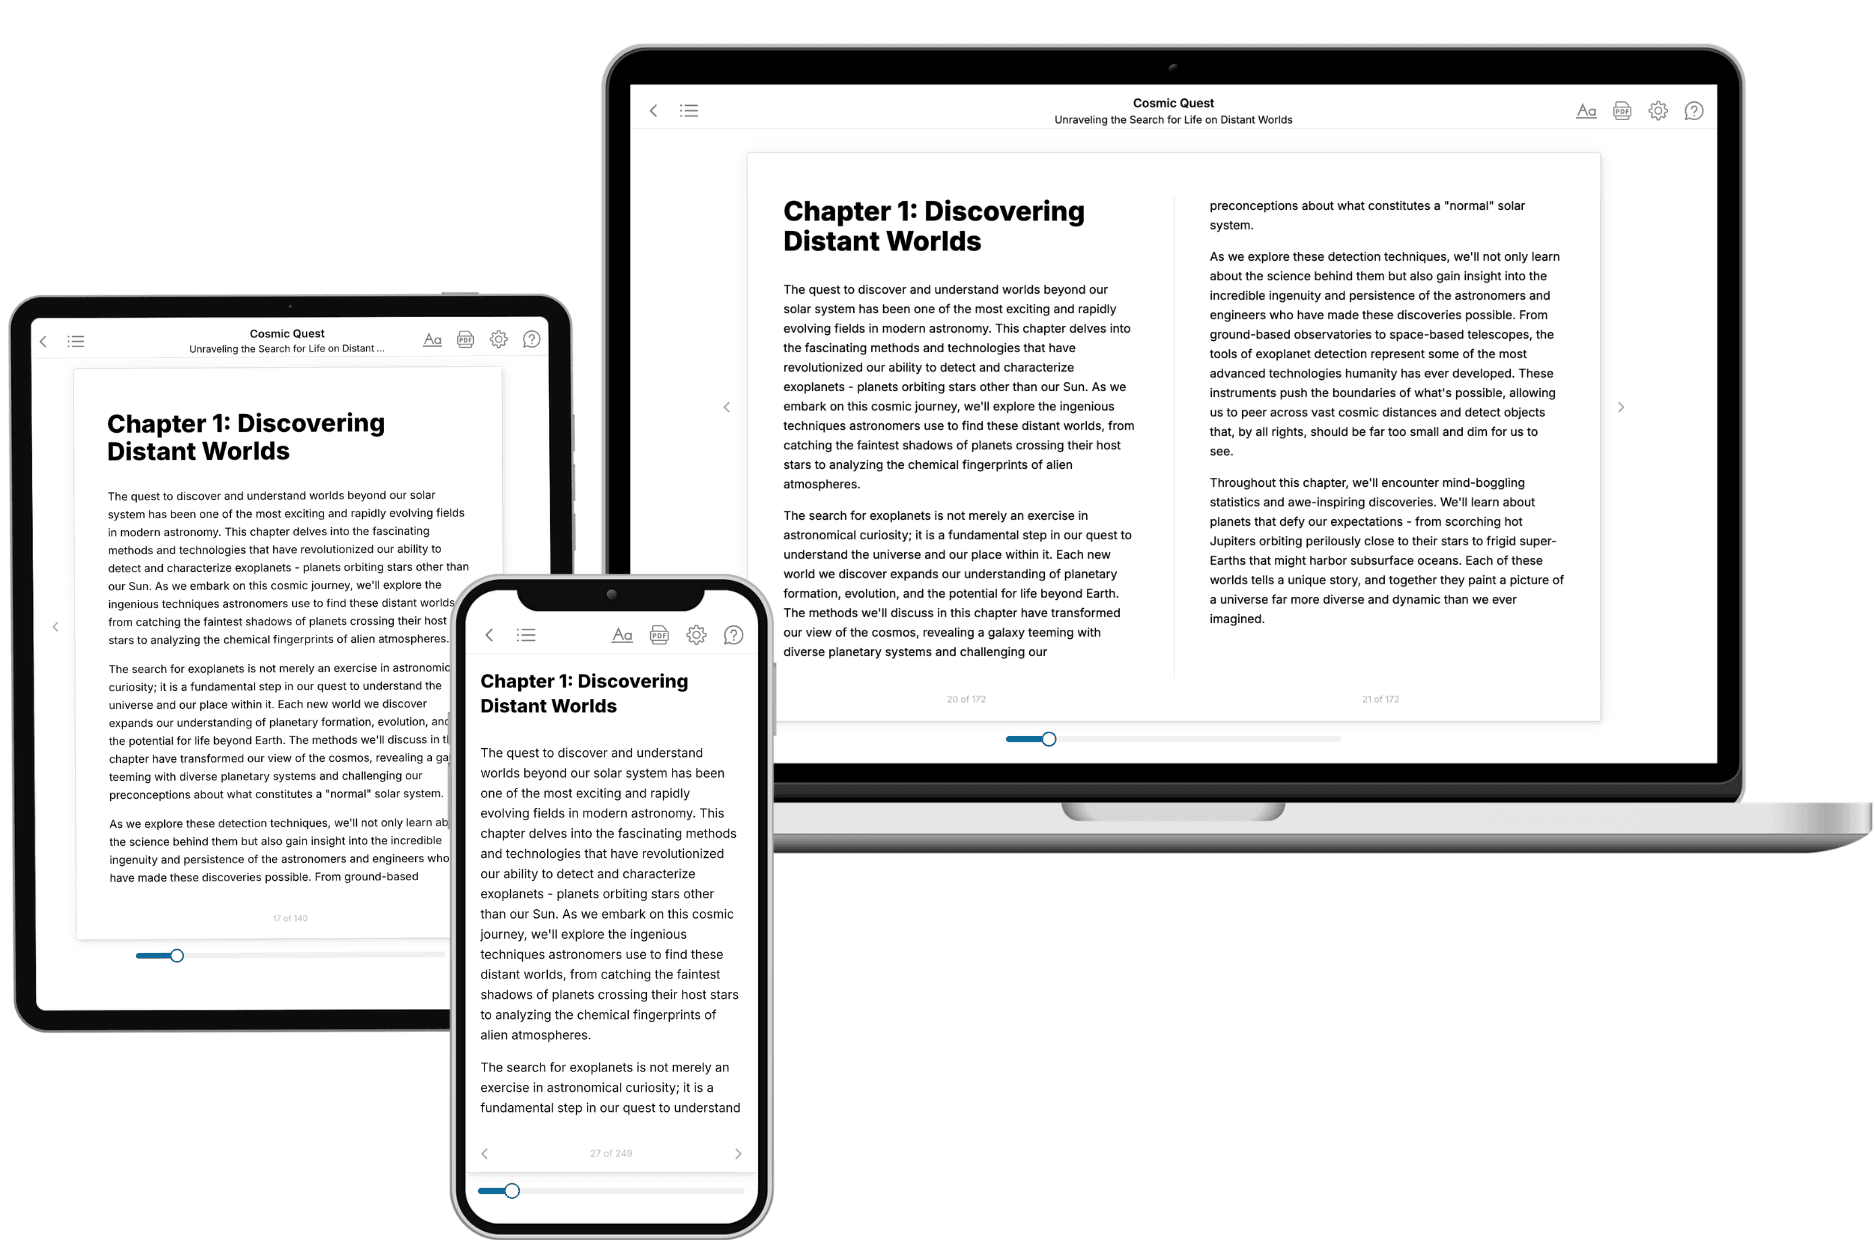
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.