Statistical Learning Theory Essentials
Master the Mathematics Behind Machine Learning and Data Analysis
Elevate your analytical capabilities by mastering the mathematical principles that power modern machine learning and statistical analysis.
191 pages9 chaptersAug 14, 2026Machine Learning
About this book
This comprehensive guide bridges the gap between theoretical foundations and practical application, equipping you with the knowledge to make informed decisions about model selection, complexity control, and performance evaluation. You'll develop a deep understanding of how algorithms learn from data, why some models generalize better than others, and how to apply rigorous statistical principles to your own projects. Through clear explanations, intuitive examples, and practical insights, you'll gain the confidence to evaluate competing approaches, diagnose model problems, and optimize your analytical workflows. Whether you're building predictive models, analyzing complex datasets, or advancing your technical expertise, this book provides the essential framework for thinking critically about learning systems and making principled choices in your statistical work.
Table of contents
- IntroductionWhy Statistical Learning Theory Matters, What You'll Learn in This Book, How to Use This BookRead below
- Chapter 1: Foundations of Statistical LearningThe Learning Problem: From Data to Predictions, Empirical Risk and True Risk, Hypothesis Spaces and Model Classes
- Chapter 2: The Bias-Variance TradeoffDecomposing Prediction Error, Understanding Bias: Systematic Errors in Learning, Understanding Variance: Sensitivity to Training Data, Practical Implications of the Tradeoff
- Chapter 3: Model Complexity and GeneralizationMeasuring Model Capacity, VC Dimension: A Fundamental Measure of Complexity, Rademacher Complexity and Empirical Process Theory
- Chapter 4: Regularization and Overfitting ControlPrinciples of Regularization, L1 and L2 Regularization: Ridge and Lasso, Early Stopping and Structural Regularization, Choosing the Right Regularization Strategy
- Chapter 5: Loss Functions and Risk MinimizationFundamentals of Loss Functions, Loss Functions for Regression, Loss Functions for Classification
- Chapter 6: Validation and Model AssessmentTrain-Test Splitting and Data Leakage, Cross-Validation: Honest Performance Estimation, Choosing and Interpreting Performance Metrics, Statistical Significance in Model Comparison
- Chapter 7: Kernel Methods and Feature SpacesThe Kernel Trick: Implicit Feature Spaces, Common Kernel Functions and Their Properties, Support Vector Machines and Margin Maximization
- Chapter 8: Ensemble Methods and Combining LearnersWhy Ensembles Work: Diversity and Averaging, Bagging and Boosting: Reducing Bias and Variance, Stacking and Meta-Learning
- Chapter 9: Applying Theory to PracticeA Principled Model Selection Workflow, Diagnosing and Fixing Common Learning Problems, Real-World Considerations: Imbalance, Noise, and Scale
- ConclusionKey Takeaways and Core Principles, Continuing Your Learning Journey
- Glossary of Key Terms
Introduction
A model that scores 98% accuracy on its training data but fails completely on new examples is not a good model. It is a memorization machine. Understanding why that failure happens, and more importantly, how to prevent it, is exactly what statistical learning theory is built to explain. The gap between performance on known data and performance on unknown data is not a quirk or a bug. It is the central problem of machine learning, and it has a rigorous mathematical structure that can be studied, measured, and controlled.
Statistical learning theory is the branch of mathematics and statistics that asks a deceptively simple question: under what conditions can a machine learn from data and generalize reliably to new situations? The answers to that question are not just academic. They determine whether a fraud detection system flags real fraud or drowns in false alarms, whether a medical diagnosis model works on patients from a different hospital, and whether a recommendation engine improves with more data or simply overfits to noise. The theory gives you the vocabulary and the tools to reason about these outcomes before they happen.
This book is built for learners who already have some mathematical footing, perhaps linear algebra, basic probability, and some exposure to machine learning, and who want to understand the deeper principles that connect all of it. The goal is not to survey every algorithm that exists. The goal is to build a coherent mental framework: one that lets you look at any learning problem and ask the right questions about data, complexity, error, and generalization. That framework, once internalized, changes how you approach every modeling decision you make.
The chapters ahead move from foundational concepts through increasingly applied territory. Along the way, you will encounter formal ideas like Empirical Risk, VC Dimension, Rademacher Complexity, and Generalization Bounds, but always in service of practical understanding. Each concept is introduced because it solves a real problem or explains a real phenomenon. The mathematics is here to clarify, not to intimidate.
Why Statistical Learning Theory Matters
Most practitioners learn machine learning through tools: libraries, APIs, and tutorials that abstract away the underlying mathematics. That approach gets you started quickly, but it leaves a gap. When a model behaves unexpectedly, when accuracy is high but real-world performance is poor, or when two models seem equivalent but one generalizes far better, the tools do not tell you why. Statistical learning theory fills that gap. It provides the explanatory layer beneath the code.
Consider a concrete example. Suppose you train a polynomial regression model on 20 data points. A degree-2 polynomial fits reasonably well. A degree-19 polynomial fits perfectly, passing through every single point. On the training data, the degree-19 model wins by every metric. But on new data, it oscillates wildly and produces absurd predictions. This is Overfitting, and it is not just a practical annoyance. It is a mathematically predictable consequence of using a model whose capacity far exceeds what the data can support. The theory tells you exactly why this happens and gives you tools to measure the risk before you deploy.
The same logic applies in the opposite direction. A model that is too simple, say a straight line fitted to data with a clear curve, will consistently miss the true pattern regardless of how much data you collect. This is Underfitting, and it reflects a different kind of failure: the model's Hypothesis Space does not contain anything close to the true relationship. Theory helps you diagnose this too, and it tells you that adding more data will not fix a model that is fundamentally too constrained.
Beyond diagnosis, theory enables principled decision-making. When you choose between L1 Regularization and L2 Regularization, you are not just picking a hyperparameter. You are making a structural choice about what kinds of solutions you prefer and what assumptions you are making about the problem. When you design a Cross-Validation scheme, you are making a decision about how to estimate True Risk from finite data. Understanding the theory behind these choices means you can adapt them intelligently to new situations rather than copying a recipe that may not fit.
There is also a practical argument for theory that often goes unspoken: it saves time. Practitioners who understand the Bias-Variance Decomposition know immediately whether to collect more data, simplify their model, or add regularization when performance is poor. Those who do not understand it often cycle through random changes, hoping something works. Theory is not slower than intuition. Over a career, it is considerably faster.
Finally, the field of machine learning is moving quickly, and new architectures and methods appear constantly. What does not change is the underlying mathematics of generalization. A practitioner who understands PAC Learning, Generalization Bounds, and the role of model capacity can evaluate a new method on first principles, rather than waiting for someone else to run the benchmarks. That kind of independent judgment is increasingly valuable as the landscape grows more complex.
The goal of statistical learning theory is not to make machine learning more complicated. It is to make the right choices obvious, and the wrong choices visible before they cause damage.
Statistical learning theory also matters because it is honest about uncertainty. It does not promise that a model will work. It provides bounds, conditions, and guarantees that hold under specified assumptions. That honesty is a feature, not a limitation. A field that can state precisely when and why its methods fail is a field that can be trusted, improved, and applied responsibly.
What You'll Learn in This Book
The book is organized around a progression of ideas that build on each other. Each chapter introduces a new layer of the framework, and by the end, all the pieces connect into a unified picture of how learning from data works. Here is a map of the terrain ahead.
The first chapter establishes the foundations. It defines the learning problem precisely: what data is, what a hypothesis is, and what it means for a model to generalize. Two concepts anchor everything that follows. Empirical Risk is the average loss on your training data, the thing your optimizer actually minimizes. True Risk is the expected loss on all possible data, the thing you actually care about. The gap between them is the source of almost every problem in machine learning, and understanding that gap is the starting point for everything else.
Chapter 2 introduces the Bias-Variance Decomposition, one of the most useful analytical tools in all of machine learning. It breaks down prediction error into three components:
- Bias: the systematic error from a model that is too simple to capture the true pattern
- Variance: the error from a model that is too sensitive to the specific training data it saw
- Irreducible Error: the noise in the data that no model can eliminate
Understanding how these three components interact is essential for diagnosing model problems and making informed decisions about model complexity.
Chapter 3 goes deeper into model complexity by introducing formal measures of capacity. VC Dimension quantifies how many data points a model class can shatter, meaning classify correctly in every possible labeling. Rademacher Complexity provides a more refined, data-dependent measure of how well a model class can fit random noise. Both concepts lead to Generalization Bounds: mathematical guarantees on how far Empirical Risk can stray from True Risk, given enough data.
Chapter 4 covers regularization, the practical toolkit for controlling overfitting. You will learn how L2 Regularization (Ridge) and L1 Regularization (Lasso) work, why they produce different kinds of solutions, and how Elastic Net combines their strengths. The chapter also covers Early Stopping as a form of implicit regularization in iterative training. Each technique is connected back to the theoretical framework so you understand not just how to apply it, but why it works.
Chapter 5 examines Loss Functions and their role in shaping what a model learns. The choice of loss function is a modeling decision with real consequences. Cross-Entropy Loss and Hinge Loss are not interchangeable, and neither is the choice between squared error and Huber Loss for regression. The chapter explains how Surrogate Loss functions make optimization tractable while preserving the right learning incentives.
Chapter 6 addresses validation and model assessment, the practical side of estimating True Risk from finite data. It covers Cross-Validation in depth, explains the dangers of Data Leakage, and discusses how to choose and interpret performance metrics honestly. This chapter is where theory meets the day-to-day workflow of building models.
Chapters 7 and 8 extend the framework into two powerful families of methods. Chapter 7 covers the Kernel Trick and Support Vector Machines, showing how linear methods can be extended to nonlinear problems by implicitly mapping data into high-dimensional feature spaces. Chapter 8 covers ensemble methods, explaining why Bagging reduces Variance, why Boosting reduces Bias, and how Stacking combines multiple learners into a more powerful system.
The final chapter ties everything together into a practical Model Selection Workflow. It walks through how to diagnose common learning problems using Learning Curves, how to handle Class Imbalance and noisy data, and how to make principled decisions at every stage of a real project. This is where the theory becomes a working toolkit.
How to Use This Book
This book is designed to be read sequentially, at least on a first pass. The concepts build on each other in a deliberate order. Bias and Variance are easier to understand once you have a clear picture of Empirical Risk and True Risk. Regularization makes more sense once you understand VC Dimension and why model capacity matters. Trying to jump directly to ensemble methods without the earlier foundation is possible, but you will miss the explanatory thread that makes the techniques feel inevitable rather than arbitrary.
That said, the book is also structured to support non-linear use once you have read it through once. Each chapter is self-contained enough to serve as a reference. If you are working on a project and need to revisit Cross-Validation or think through a regularization choice, you can return to the relevant chapter without re-reading everything before it. The Glossary at the end collects all canonical terms in one place for quick lookup.
Here is a suggested approach depending on your starting point:
- If you are new to the theory but experienced with machine learning practice: Read Chapters 1 through 3 carefully. These chapters will reframe things you already do intuitively in precise mathematical terms. The payoff comes quickly once the vocabulary clicks.
- If you are comfortable with the basics and want to go deeper: Focus on Chapters 3, 5, and 7. VC Dimension, Loss Functions, and Kernel Methods are where the theory gets most interesting and where the connections to practice are richest.
- If you are preparing for a project or competition: Start with Chapter 6 on validation and Chapter 9 on the Model Selection Workflow. Then work backward to the theory chapters that explain the choices you are making.
- If you are studying for an exam or interview: The Glossary and the opening sections of each chapter give you the key definitions. The worked examples throughout give you the intuition to explain concepts clearly.
Throughout the book, mathematical notation is introduced carefully and used consistently. The canonical terms listed in the Glossary are always written the same way, so you can build a reliable mental map of the concepts. When a new term appears for the first time, it is set in bold and defined in context. You do not need to memorize every formula, but you should aim to understand what each formula is measuring and why that measurement matters.
The examples in this book are chosen to be concrete and specific. Abstract definitions are always followed by a scenario, a calculation, or a comparison that makes the idea tangible. When a concept has a common misapplication, that misapplication is named and explained. Learning what a concept does not mean is often as important as learning what it does mean. For instance, a high VC Dimension does not automatically mean a model will overfit. It means the model has the capacity to overfit, and whether it does depends on the amount of data and the regularization applied.
One practical note on mathematics: some sections include formal inequalities and probability bounds. These are included because they are genuinely useful, not for decoration. If a section feels dense, the recommended approach is to read the surrounding prose first, understand the intuition, and then return to the formal statement. The formal version will make more sense once you know what it is trying to say. Skipping the math entirely is an option, but you will lose some of the precision that makes the theory actionable.
Cross-references appear throughout the book when a concept from one chapter is relevant to another. These references point to the concept by name rather than by chapter number, so you always know what you are being directed toward. For example, when the chapter on ensemble methods refers back to the Bias-Variance Decomposition, it names that concept explicitly. This keeps the connections visible and reinforces the idea that the book is building a single coherent framework, not a collection of separate topics.
Finally, a word on pace. Statistical learning theory rewards slow reading more than fast reading. A paragraph that defines Rademacher Complexity in three sentences is doing a lot of work. Reading it twice, or pausing to think through an example, is not a sign of struggle. It is the right way to engage with material that is genuinely dense with meaning. The concepts here have taken researchers decades to develop and refine. Giving them a few extra minutes of attention is a reasonable investment.
The most productive way to use this book is not to finish it quickly. It is to finish it with a framework you can actually use, one that changes how you think about every modeling problem you encounter afterward.
Statistical learning theory is not a set of rules to follow. It is a way of thinking about learning systems that makes the invisible visible. Once you see the structure of generalization, the tradeoffs in model complexity, and the mathematics of risk, you cannot unsee it. That shift in perspective is what this book is designed to produce, and it starts on the very next page.
This is the end of the free sample. The full book has 9 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Machine Learning knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Machine Learning book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Machine Learning book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
- 3. Get your tailored book
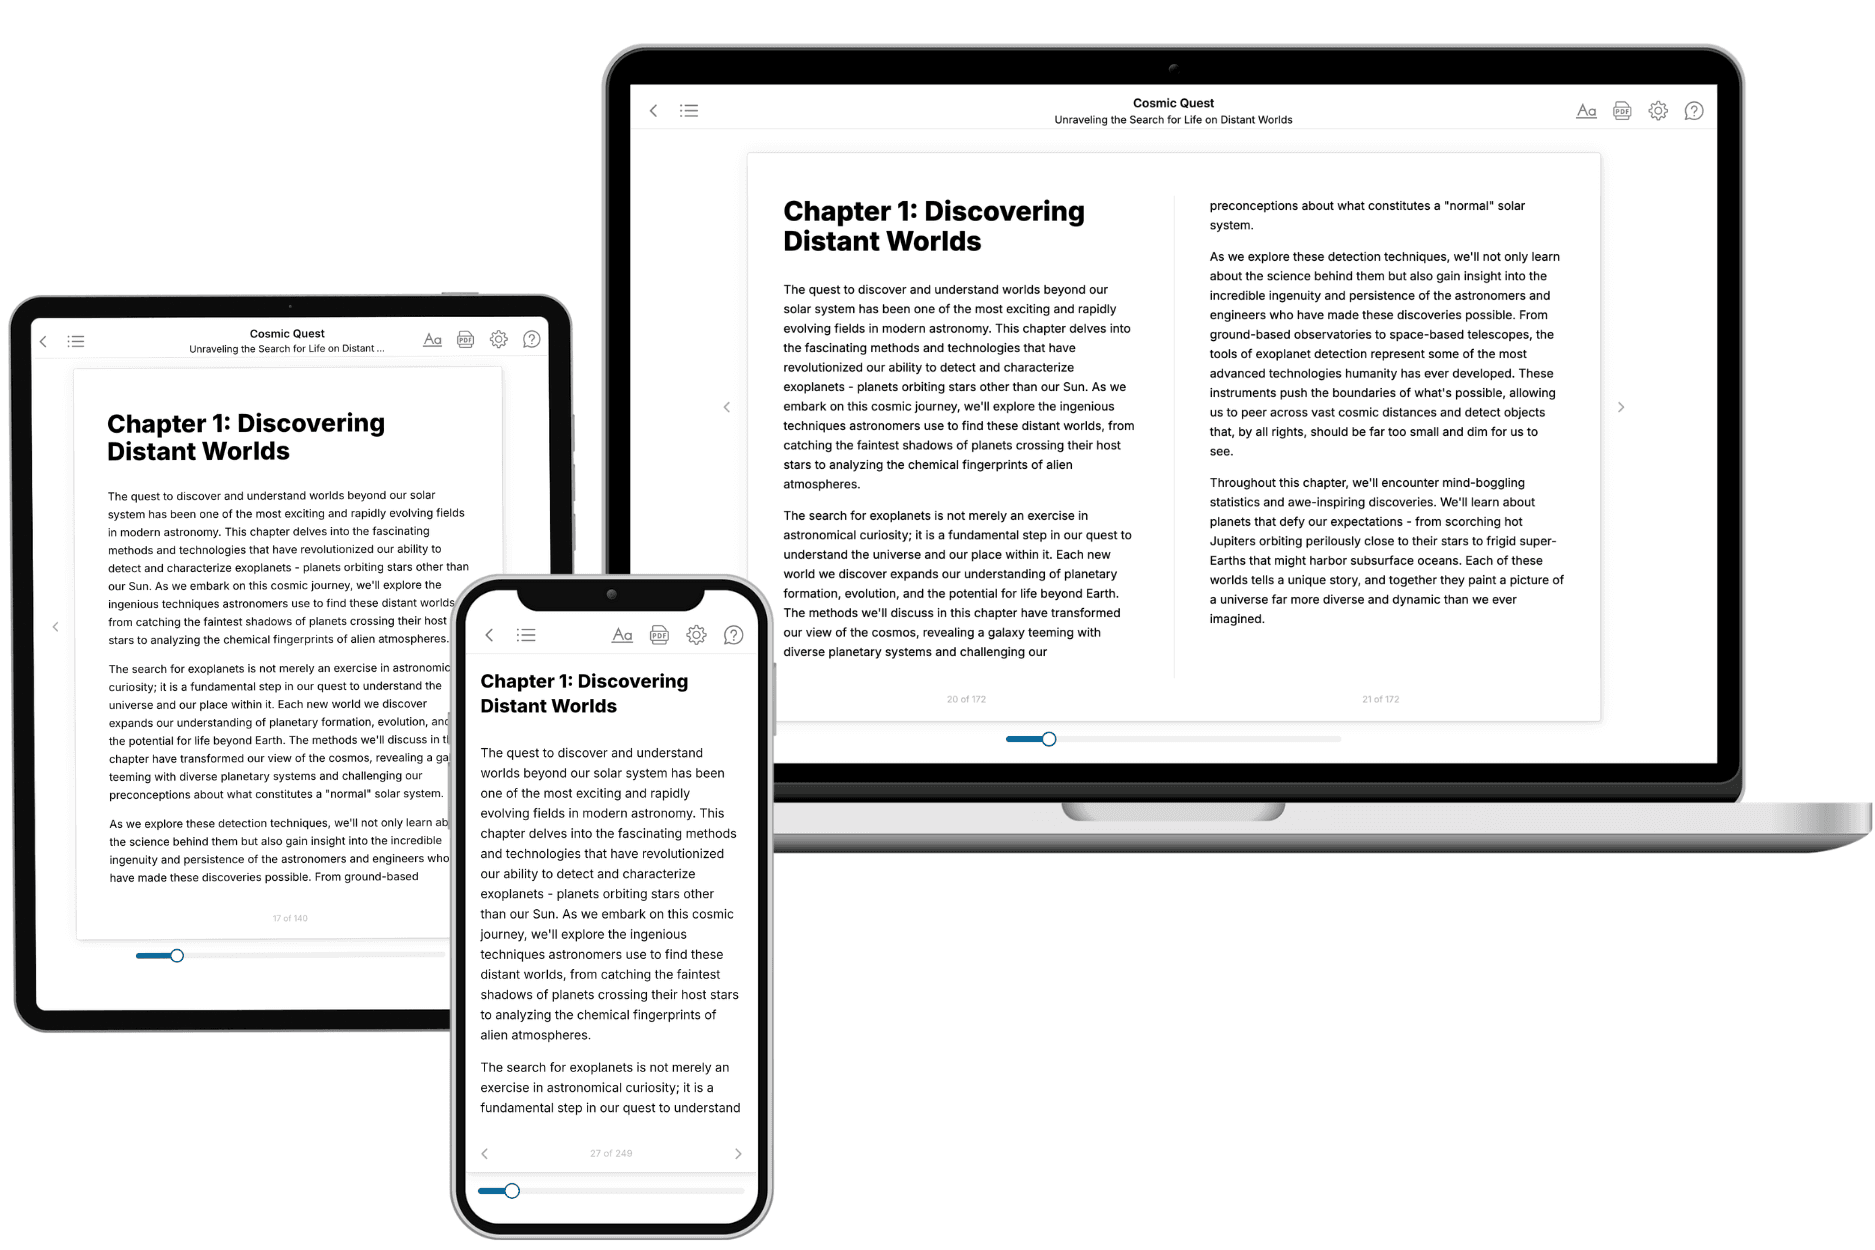
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.