Genome Annotation Essentials
From Raw Sequences to Functional Insights
Master the critical skill of transforming raw genomic sequences into actionable biological knowledge.
222 pages10 chaptersJun 8, 2026Genomics
About this book
This comprehensive guide takes you from understanding basic annotation concepts to implementing sophisticated annotation pipelines in real-world research. You'll learn how computational tools identify genes and regulatory elements, discover why manual curation remains irreplaceable, and explore how comparative genomics validates your findings. Through practical examples and clear explanations, you'll gain the expertise to evaluate annotation quality, troubleshoot common challenges, and stay current with emerging technologies. Whether you're analyzing a newly sequenced genome or refining existing annotations, this book equips you with the knowledge and strategies to extract maximum biological insight from genomic data. Perfect for researchers, bioinformaticians, and students ready to move beyond sequence databases into genuine genomic interpretation.
Table of contents
- IntroductionWhy Genome Annotation Matters, The Annotation Landscape Today, What You'll Learn in This BookRead below
- Chapter 1: Fundamentals of Genome AnnotationDefining Genome Annotation, Types of Annotation: Structural and Functional, The Annotation Workflow Overview
- Chapter 2: Sequence Preparation and Quality AssessmentFrom Raw Reads to Assembled Sequences, Evaluating Sequence Quality and Completeness, Preprocessing and Masking Repetitive Elements
- Chapter 3: Gene Prediction and IdentificationAb Initio Gene Prediction Methods, Evidence-Based Gene Prediction, Combining Multiple Prediction Approaches
- Chapter 4: Functional Annotation and CharacterizationHomology Searches and Sequence Similarity, Identifying Protein Domains and Motifs, Assigning Biological Pathways and Functions
- Chapter 5: Comparative Genomics and ValidationLeveraging Comparative Genomics, Identifying Orthologs and Paralogs, Experimental Validation Strategies
- Chapter 6: Annotation Pipelines and ToolsDesigning Effective Annotation Pipelines, Major Annotation Tools and Platforms, Automation and Tool Integration
- Chapter 7: Quality Control and Manual CurationQuality Control Metrics and Standards, The Art and Science of Manual Curation, Detecting and Correcting Annotation Errors
- Chapter 8: Data Standards and FormatsGFF and GTF: Standard Annotation Formats, Other Important Genomic Data Formats, Managing and Sharing Annotated Genomes
- Chapter 9: Emerging Technologies and Future DirectionsLong-Read Sequencing and Annotation, Single-Cell and Spatial Genomics, Artificial Intelligence and Machine Learning in Annotation
- Chapter 10: Practical Applications and Case StudiesAnnotating Microbial Genomes, Annotating Plant Genomes, Annotating Human and Complex Genomes
- ConclusionKey Takeaways and Best Practices, Staying Current in a Rapidly Evolving Field
- Glossary
- Further Reading and Resources
Introduction
Every genome sequencing project begins with the same fundamental challenge: a long string of A, T, G, and C characters that, on its own, tells you almost nothing useful. A freshly assembled genome sequence is a bit like receiving a massive library written in an unfamiliar script. The letters are all there, but without a way to identify where the sentences begin and end, what each word means, or how the chapters relate to one another, the information stays locked away. Genome annotation is the process of unlocking that information, transforming raw nucleotide sequences into a structured, interpretable map of biological function.
The scale of this challenge is worth appreciating. The human genome contains roughly 3.2 billion base pairs, yet only a fraction of those bases encode proteins. Identifying which regions are genes, which regulate gene expression, which are structural elements, and which remain functionally mysterious requires a sophisticated combination of computational tools, biological knowledge, and careful human judgment. For smaller microbial genomes, the task is more tractable but no less important. For complex plant genomes, which can be several times larger than the human genome and riddled with repetitive sequences, annotation becomes genuinely demanding work.
This book is designed for researchers, bioinformaticians, and students who already have a working foundation in genomics and want to move confidently into the practice of genome annotation. You will not need to start from scratch on basic molecular biology, but you will find that even familiar concepts take on new depth when viewed through the lens of annotation. The chapters ahead cover everything from preparing raw sequences for analysis to deploying automated pipelines, evaluating annotation quality, and keeping pace with technologies that are actively reshaping the field. The goal throughout is practical mastery: not just understanding what annotation is, but knowing how to do it well.
Genome annotation sits at the intersection of computation and biology, and that intersection is where some of the most exciting discoveries in modern science are happening. When a new pathogen emerges, annotating its genome is one of the first steps toward understanding how it causes disease and how it might be stopped. When a crop plant is sequenced, annotation reveals the genes responsible for yield, drought resistance, and nutritional content. When a rare genetic disorder is studied, annotation helps pinpoint the functional consequences of mutations. The work covered in this book is not abstract or academic in the narrow sense. It connects directly to medicine, agriculture, evolutionary biology, and biotechnology.
Why Genome Annotation Matters
Raw sequence data has become remarkably cheap and abundant. The cost of sequencing a human genome dropped from roughly $100 million in 2001 to under $1,000 by the mid-2010s, and costs have continued to fall since then.[1] The bottleneck in genomics is no longer generating sequence data. It is making sense of it. Annotation is the bridge between raw data and biological understanding, and without it, sequencing projects produce little more than expensive text files.
Consider what annotation actually delivers. When a genome is properly annotated, researchers can answer questions that would otherwise be unanswerable from sequence alone. Which genes are present? What proteins do they encode? Are those proteins enzymes, receptors, transcription factors, or structural components? Are there regulatory elements that control when and where genes are expressed? Are there non-coding RNA genes that play roles in gene regulation? Annotation provides the coordinate system that makes all of these questions answerable, and it provides the biological labels that connect sequence features to known functions.
The practical stakes are high across multiple fields. In clinical genomics, annotation determines whether a variant identified in a patient's genome falls within a gene, affects a splice site, or disrupts a known regulatory element. A variant in an annotated coding region with a known disease association carries very different clinical weight than a variant in an unannotated intergenic region. Annotation quality directly influences diagnostic accuracy, and errors in annotation can lead to misinterpretation of genetic test results with real consequences for patients and families.
In agricultural genomics, annotation enables marker-assisted breeding and the identification of candidate genes for important traits. When researchers sequenced the rice genome in 2002, the annotation of roughly 32,000 genes opened the door to systematic studies of yield, disease resistance, and stress tolerance.[2] Without that annotation layer, the sequence would have been far less actionable for breeders and crop scientists. The same principle applies to every newly sequenced organism: the sequence is the raw material, but annotation is what makes it useful.
Annotation also matters for basic science in ways that are harder to quantify but no less important. Comparative genomics, the study of how genomes differ and resemble one another across species, depends entirely on having reliable annotations to compare. Evolutionary analyses of gene family expansions, losses, and duplications require knowing which genes are present in which organisms. Studies of genome organization, chromatin structure, and three-dimensional nuclear architecture all rely on annotated reference genomes as their foundation. In short, annotation is not a preliminary step that gets done once and forgotten. It is an ongoing, living layer of knowledge that underpins virtually all downstream genomic research.
It is also worth being honest about what annotation cannot do, at least not yet. A significant fraction of genes in most genomes are annotated as hypothetical proteins or proteins of unknown function, meaning that computational tools can predict their existence but cannot assign a clear biological role. In some bacterial genomes, this fraction can exceed 30 to 40 percent of all predicted genes.[3] Annotation is a process of progressive refinement, not a one-time solution. Understanding its limitations is just as important as understanding its power.
The value of annotation also extends to the research community as a whole. When annotations are deposited in public databases like NCBI, Ensembl, or UniProt, they become shared resources that accelerate discovery across thousands of laboratories worldwide. A well-curated annotation of a model organism's genome, such as the Saccharomyces cerevisiae genome maintained by the Saccharomyces Genome Database, represents decades of collective scientific effort and serves as a reference point for researchers studying everything from cell biology to drug targets.[4] Annotation is, in this sense, a form of scientific infrastructure.
Key point: Genome annotation is not a technical formality. It is the process that converts sequencing data into biological knowledge, and the quality of that annotation determines the quality of every downstream analysis that depends on it.
The Annotation Landscape Today
The field of genome annotation has changed dramatically over the past two decades, driven by improvements in sequencing technology, the growth of biological databases, and advances in machine learning and computational biology. Understanding where the field stands today helps you appreciate both the power of current tools and the genuine challenges that remain unsolved. The annotation landscape is rich, sometimes confusing, and constantly evolving.
Modern annotation typically involves two broad categories of work. Structural annotation identifies the physical locations and boundaries of genomic features: where genes start and stop, where exons and introns are, where promoters and enhancers sit, and where repetitive elements are distributed. Functional annotation then assigns biological meaning to those features, connecting them to known proteins, pathways, and processes. Both layers are essential, and both present distinct technical challenges. A gene can be structurally annotated with high confidence but remain functionally mysterious, or it can have a predicted function that turns out to be incorrect when tested experimentally.
The tools available for annotation have multiplied enormously. For structural annotation of prokaryotic genomes, tools like Prokka and RAST can produce a reasonably complete annotation in minutes.[5] For eukaryotic genomes, the process is considerably more complex, typically requiring tools like AUGUSTUS, GeneMark-ES, or MAKER for gene prediction, combined with RNA-seq evidence and protein homology data to refine predictions. Functional annotation draws on databases like UniProt/Swiss-Prot, InterPro, Gene Ontology (GO), and KEGG to assign roles to predicted gene products.
Major genome annotation projects have established reference standards that the broader community relies on. The GENCODE project, which provides comprehensive annotation of the human and mouse genomes, combines automated computational annotation with extensive manual curation by expert biologists.[6] The Ensembl project provides automated annotation for hundreds of vertebrate and non-vertebrate genomes, making it one of the most widely used annotation resources in the world. These projects illustrate the two poles of the annotation spectrum: highly curated, resource-intensive annotation at one end, and scalable automated annotation at the other.
One of the most significant recent developments in the annotation landscape is the rise of long-read sequencing technologies from companies like Pacific Biosciences and Oxford Nanopore Technologies. Short-read sequencing, which dominated the field for over a decade, produces reads of 100 to 300 base pairs that are difficult to assemble across repetitive regions and challenging to use for resolving complex gene structures. Long reads, which can span tens of thousands of base pairs, make it possible to sequence through repetitive regions, resolve full-length transcript structures, and detect structural variants that short reads miss entirely. This has improved both genome assembly quality and the accuracy of subsequent annotation.
Artificial intelligence and machine learning are also reshaping annotation in meaningful ways. Deep learning models trained on large genomic datasets can now predict splice sites, transcription factor binding sites, and other regulatory elements with accuracy that rivals or exceeds traditional rule-based methods. Tools like DeepVariant for variant calling and SpliceAI for splice site prediction represent a new generation of annotation-adjacent tools that leverage neural networks rather than hand-crafted biological rules.[7] The integration of these approaches into standard annotation workflows is still in progress, but the direction is clear.
Despite all of this progress, significant challenges remain. Repetitive elements, which make up more than half of the human genome, continue to complicate both assembly and annotation. Alternative splicing, which allows a single gene to produce multiple protein isoforms, means that gene models are often more complex than simple exon-intron structures suggest. Non-coding RNAs, including long non-coding RNAs, microRNAs, and circular RNAs, represent a vast and still incompletely characterized layer of genome function. And for non-model organisms with no close relatives in existing databases, functional annotation can be severely limited by the absence of comparable reference data.
The annotation landscape is also shaped by community standards and data sharing practices. Formats like GFF3 (General Feature Format version 3) and GTF (Gene Transfer Format) provide standardized ways to represent annotation data, enabling tools and databases to exchange information reliably. Ontologies like the Gene Ontology provide controlled vocabularies for describing gene functions, ensuring that annotations from different projects can be compared and integrated. These standards are not glamorous, but they are the connective tissue that holds the annotation ecosystem together.
Where the field stands: Annotation today is faster, more automated, and more accurate than ever before, but it still requires biological expertise, careful quality control, and ongoing refinement. No fully automated pipeline yet replaces the value of expert human judgment for complex or novel genomes.
What You'll Learn in This Book
This book is organized to take you through genome annotation in a logical, progressive sequence. Each chapter builds on the ones before it, moving from foundational concepts to practical implementation to advanced topics and real-world applications. Whether you are approaching annotation for the first time in a professional context or looking to deepen expertise you have already started building, the structure is designed to meet you where you are and carry you further.
The early chapters establish the conceptual and technical foundation. Chapter 1 defines genome annotation precisely, distinguishes between structural and functional annotation, and walks through the overall workflow at a high level. This chapter ensures that everyone starts with a shared vocabulary and a clear mental model of what the annotation process involves. Chapter 2 then addresses sequence preparation, covering how raw sequencing reads become assembled genomes, how to evaluate assembly quality, and why preprocessing steps like repeat masking are critical before annotation begins.
The middle chapters dive into the core technical work of annotation. Chapter 3 covers gene prediction in depth, explaining both ab initio methods that rely on statistical models of gene structure and evidence-based methods that incorporate RNA-seq data, protein alignments, and other experimental evidence. You will learn how to combine multiple prediction approaches to produce more reliable gene models than any single method can achieve alone. Chapter 4 then moves into functional annotation, covering homology searches, protein domain identification, and pathway assignment. These are the steps that connect predicted genes to known biology.
Chapter 5 explores comparative genomics as both a validation strategy and a source of annotation evidence. Comparing a newly annotated genome to well-characterized relatives can reveal conserved genes that automated tools might miss, flag annotation errors, and provide evolutionary context for genomic features. Chapter 6 takes a practical look at annotation pipelines and tools, covering how to design an effective workflow, which tools are most widely used and why, and how to automate and integrate multiple components into a coherent system.
Quality control and manual curation are the focus of Chapter 7, and this chapter deserves particular attention. Automated annotation is powerful but imperfect. Understanding how to evaluate annotation quality, identify common error types, and apply manual curation where it matters most is what separates good annotation from great annotation. This chapter provides concrete metrics, practical strategies, and guidance on when to invest in manual review versus when automated results are sufficient.
Chapter 8 covers data standards and formats in detail. Understanding GFF3, GTF, FASTA, VCF, and related formats is essential for working with annotation data in practice. This chapter also addresses data management and sharing, including how to deposit annotations in public databases and how to document your work so that others can understand and build on it. Chapter 9 then looks ahead to emerging technologies, including long-read sequencing, single-cell genomics, and the growing role of artificial intelligence in annotation. These topics are not speculative; they are already influencing how annotation is done, and understanding them prepares you for where the field is heading.
The final chapter, Chapter 10, brings everything together through practical case studies. Annotating a microbial genome, a plant genome, and a complex human genome each present distinct challenges and require different strategies. Walking through these real-world scenarios illustrates how the concepts and tools from earlier chapters apply in practice, and it highlights the decisions and trade-offs that annotators face in actual research contexts.
Throughout the book, you will find concrete examples, specific tool recommendations, and practical guidance on common challenges. The goal is not to provide an exhaustive catalog of every annotation tool ever developed. The field moves too fast for any catalog to stay current for long. Instead, the goal is to give you a deep enough understanding of the principles and methods that you can evaluate new tools as they emerge, adapt your workflows to new data types, and make informed decisions about annotation quality and strategy. Here is a quick summary of what each chapter delivers:
- Chapter 1: Core concepts, vocabulary, and the annotation workflow overview
- Chapter 2: Sequence assembly quality, completeness metrics, and repeat masking
- Chapter 3: Ab initio and evidence-based gene prediction, combining approaches
- Chapter 4: Homology searches, domain identification, pathway and GO term assignment
- Chapter 5: Comparative genomics, ortholog identification, experimental validation
- Chapter 6: Pipeline design, major tools (MAKER, Prokka, AUGUSTUS, Ensembl), automation
- Chapter 7: QC metrics, manual curation strategies, error detection and correction
- Chapter 8: GFF3, GTF, VCF formats, data management, and public database submission
- Chapter 9: Long-read sequencing, single-cell genomics, AI and machine learning in annotation
- Chapter 10: Case studies in microbial, plant, and human genome annotation
One thing worth emphasizing before you begin: genome annotation is not a solved problem. It is an active area of research and development, and the best practitioners in the field combine technical skill with genuine biological curiosity. The tools are means to an end, and the end is biological understanding. Keeping that goal in mind, rather than getting lost in the mechanics of any particular software package, is what makes annotation work meaningful and productive. The chapters ahead are designed to help you develop both the technical competence and the biological judgment that good annotation requires.
Finally, annotation is increasingly a collaborative endeavor. Community databases, shared pipelines, and open-source tools have made it possible for researchers around the world to build on each other's work in ways that were not possible even ten years ago. As you develop your own annotation skills, you become part of that community. The knowledge you build, the annotations you produce, and the tools you contribute to or improve all add to a shared scientific resource that benefits researchers and, ultimately, the broader goals of understanding life at the molecular level. That is a worthwhile thing to be part of, and this book is your guide to getting there.
Notes
Introduction
- 1. Wetterstrand KA. DNA Sequencing Costs: Data from the NHGRI Genome Sequencing Program (GSP). National Human Genome Research Institute. Available at: www.genome.gov/sequencingcostsdata
- 2. International Rice Genome Sequencing Project, "The map-based sequence of the rice genome," Nature, 2005
- 3. Galperin MY and Koonin EV, "Conserved hypothetical," proteins: prioritization of targets for experimental study. Nucleic Acids Research, 2004
- 4. Cherry JM and others, Saccharomyces Genome Database: the genomics resource of budding yeast, Nucleic Acids Research, 40(D1), D700-D705, 2012
- 5. Seemann T, "Prokka: rapid prokaryotic genome annotation," Bioinformatics, 2014
- 6. Frankish A and others, GENCODE 2021, Nucleic Acids Research, 49(D1), D916-D923, 2021
- 7. Jaganathan K and others, "Predicting Splicing from Primary Sequence with Deep Learning," Cell, 2019
This is the end of the free sample. The full book has 10 chapters.
Want this book written for you?
Tell us your goals and background, and get your own version of this book, tailored by AI to you.


Benefits of AI-tailored books
- Read one book, not ten:
- all the Genomics knowledge you need, gathered into a single book.
- Save days of learning:
- tell us your goals, choose your topics, and the whole book is built around them.
- Learn effortlessly:
- Genomics book written for your specific background and expertise.
- Understand at a glance:
- includes charts, tables, timelines, checklists, decision trees, and more.
- Stay current:
- written the day you order it, not years ago.
- Trust what you read:
- every book is checked for accuracy, with real research when your subject needs it.
Create your unique book in 3 steps
- 1. Select your focus
Select the focus of your Genomics book and share your background
- 2. Personalize your book
Specify your goals and choose sub-topics to include
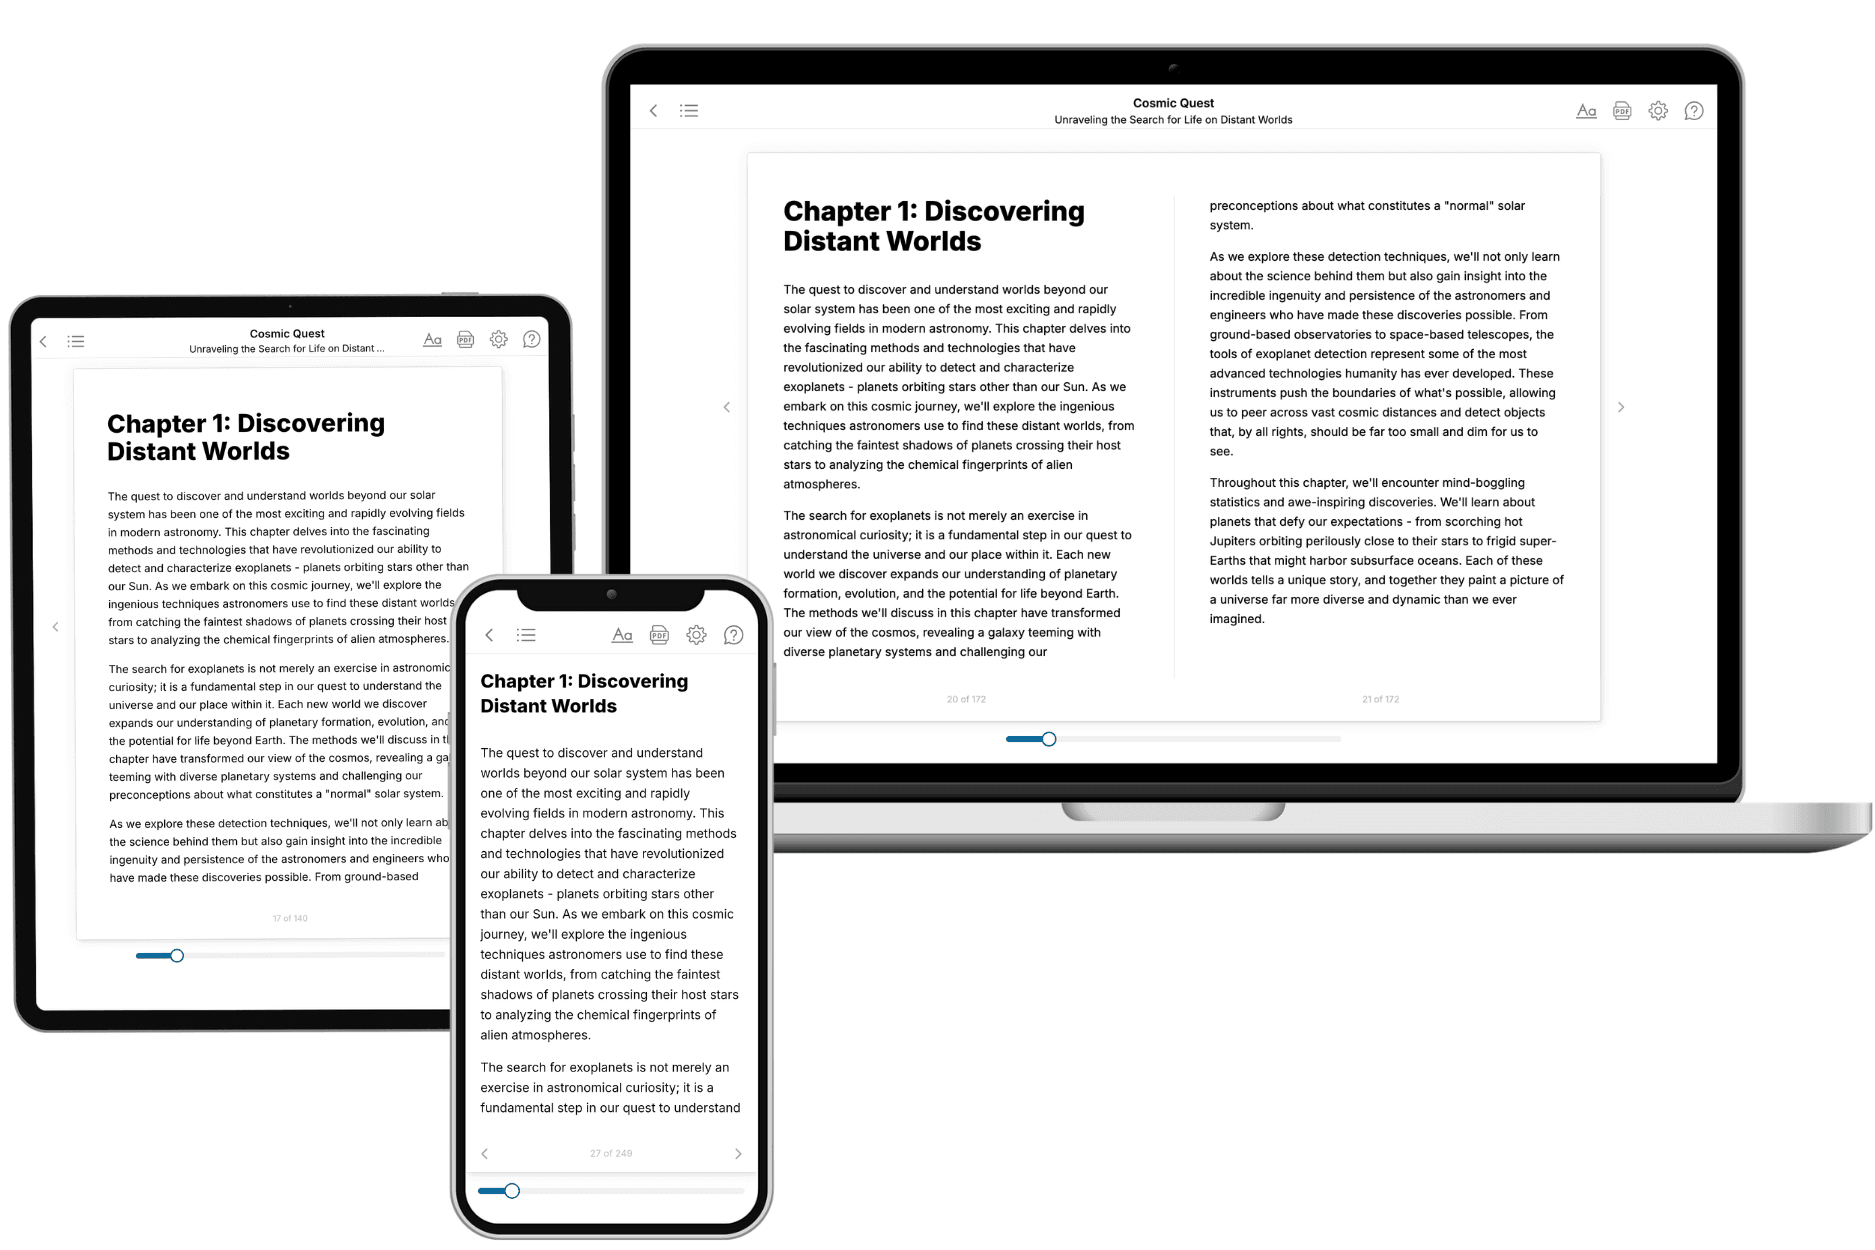
- 3. Get your tailored book
Your book is ready in 10 minutes. Read it online, download as EPUB or PDF, or send to Kindle.
Frequently asked questions
- What is TailoredRead?
TailoredRead creates complete, full-length nonfiction ebooks, written specifically for you. Tell us what you want to learn and why, and TailoredRead writes you a complete ebook on it, with charts, tables, and diagrams throughout. Read it online, on Kindle, or on any e-reader, or download it as a PDF or EPUB. Every book is written fresh the day you order it.
- How is the book tailored to me?
Before anything is written, you answer a few short questions about your goals, your background, and the topics you care about. Your book is then planned around your answers: written at your level, focused on your goals, and covering the topics you chose, instead of the one-size-fits-all book a store sells everyone.
- Will it read like generic AI content?
No. Your book isn't a chat transcript: it's planned chapter by chapter before a single word is written, told in a clear book voice, and explains ideas visually with charts, tables, and diagrams. After writing, every book goes through an editorial pass that polishes chapters so the book reads consistent from start to finish. Judge for yourself: browse thousands of sample books on our Explore Books page.
- How accurate is the content?
Our AI first checks whether your subject needs live research. Niche and fast-moving subjects are researched before writing, and the book plan and chapters are grounded in what it finds. After writing, every book goes through a quality pass that checks its facts and consistency, and researched books list their sources in a Notes section at the back.
- How long is the book?
You choose the length: Comprehensive (250-300 pages), Detailed (150-200 pages), Essential (70-100 pages), or Short (30-50 pages).
- Does the book include visuals?
Yes. Every book includes charts, tables, and diagrams: timelines, checklists, step-by-step guides, decision trees, comparison tables, matrices, and bar charts. A typical book includes dozens of these visual elements.
- Can I read it on Kindle? What formats can I download?
Yes. Every book can be read in our online reader or downloaded as a PDF or EPUB. The EPUB can be opened with Kindle, Apple Books, Kobo, and any e-reader. The Commercial and Author licenses also include an editable Word (DOCX) and Markdown download.
- How much does it cost?
About the price of a regular ebook. The exact price depends on your book's length and complexity, from $2 for the shortest books to $35 for the most comprehensive, and it's shown when you review your book, before you commit to anything. Each book is a one-time purchase, yours to keep, no subscription. Licenses that let you share, teach, or publish your book range from $35.99 to $49.99.
- Can I preview the book before purchasing?
Before you pay, you'll see what your book will cover: the title, a detailed description, the estimated length, and the complete chapter-by-chapter table of contents, so you know what you're getting before you decide. The full text itself is written after you purchase.
- How long does it take to create a book?
About 10 minutes. You can start reading the opening chapters while the rest is still being written.